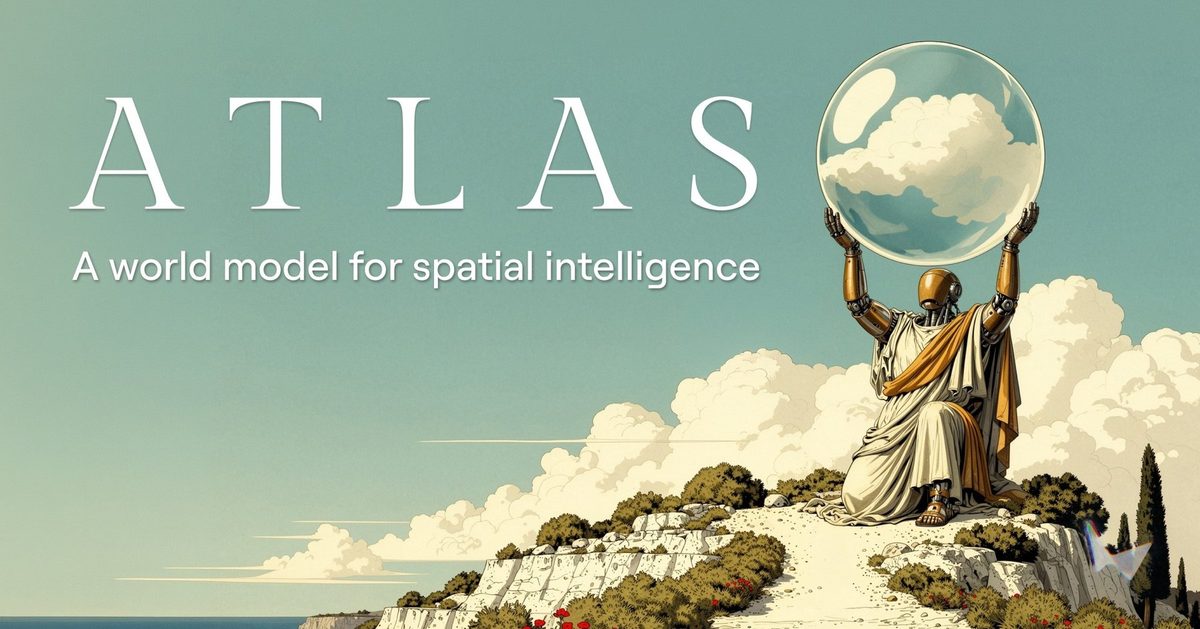
World Labs, the spatial intelligence startup co-founded by Fei-Fei Li, has unveiled Atlas, an omni-model designed to generate, reconstruct, and simulate 3D scenes using limited input photos. Built to understand spatial context directly, Atlas anchors text, image, video, and 3D data within geometric positions rather than treating inputs as flat, one- or two-dimensional sequences.
According to World Labs, Atlas generates camera-controlled videos at up to 1440p resolution based on geometric movement inputs rather than text prompts. The model also performs 3D spatial reconstruction, generating point clouds and 3D Gaussian splats from as few as one to several dozen standard photos, reportedly outperforming specialized 3D baselines on consistency tests.
For robotics and simulation workflows, Atlas functions as a real-to-sim framework, constructing virtual environments alongside physical depth data to generate synthetic sensor outputs for simulated autonomous agents.
Why it matters
Replaces fragmented 3D pipelines with a unified model generating native point clouds and Gaussian splats.
Unlocks real-to-sim capabilities for robotics startups by creating 3D environments from consumer smartphone camera footage.
Offers precise geometric camera controls for video generation instead of unpredictable text-prompted generation.
Source: the-decoder.com