Early-stage AI startups are prioritizing speed to market over infrastructure cost optimization, opting to build on hyperscale cloud platforms and mature APIs to accelerate prototype cycles. Rather than focusing on token efficiency or custom silicon performance during seed and Series A stages, founders are optimizing for rapid customer iteration and compressed development timelines.
However, trade-offs made for early velocity often turn into severe architectural constraints as startups scale. Relying exclusively on proprietary cloud features or cloud-only execution models can restrict operational freedom later when enterprise customers demand lower latency, edge compute, or strict data privacy protections.
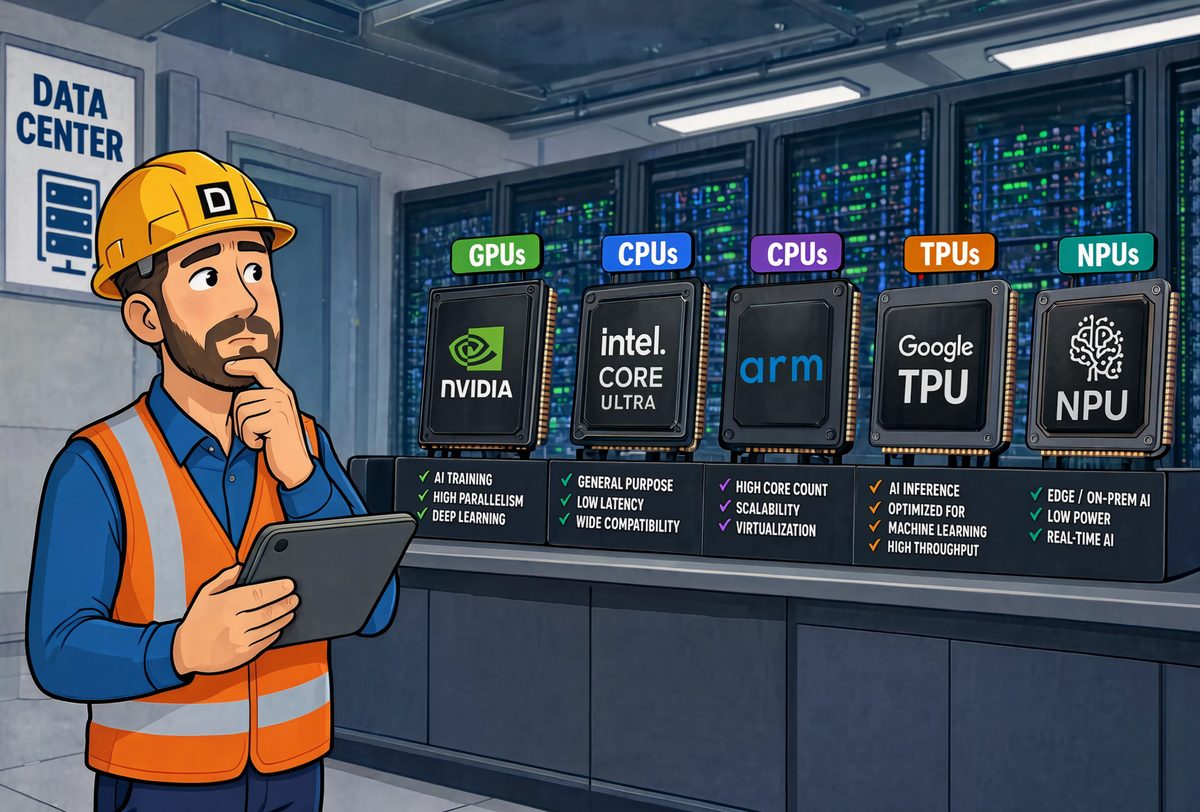
Industry experts suggest that winning startups avoid premature infrastructure optimization without locking themselves into narrow architecture paths. Preserving flexibility across hybrid execution environments—spanning cloud instances, edge devices, and local silicon—allows scaling companies to transition seamlessly when infrastructure cost and control become strategic priorities.
Why it matters
Prioritize shipping speed early, but avoid proprietary platform lock-in that restricts future cloud migration or edge deployment.
Plan for infrastructure inflection points around Series B, when token efficiency and inference costs become critical unit economics.
Design flexible architectures early to accommodate future enterprise demands for local execution and data privacy.
Source: siliconangle.com