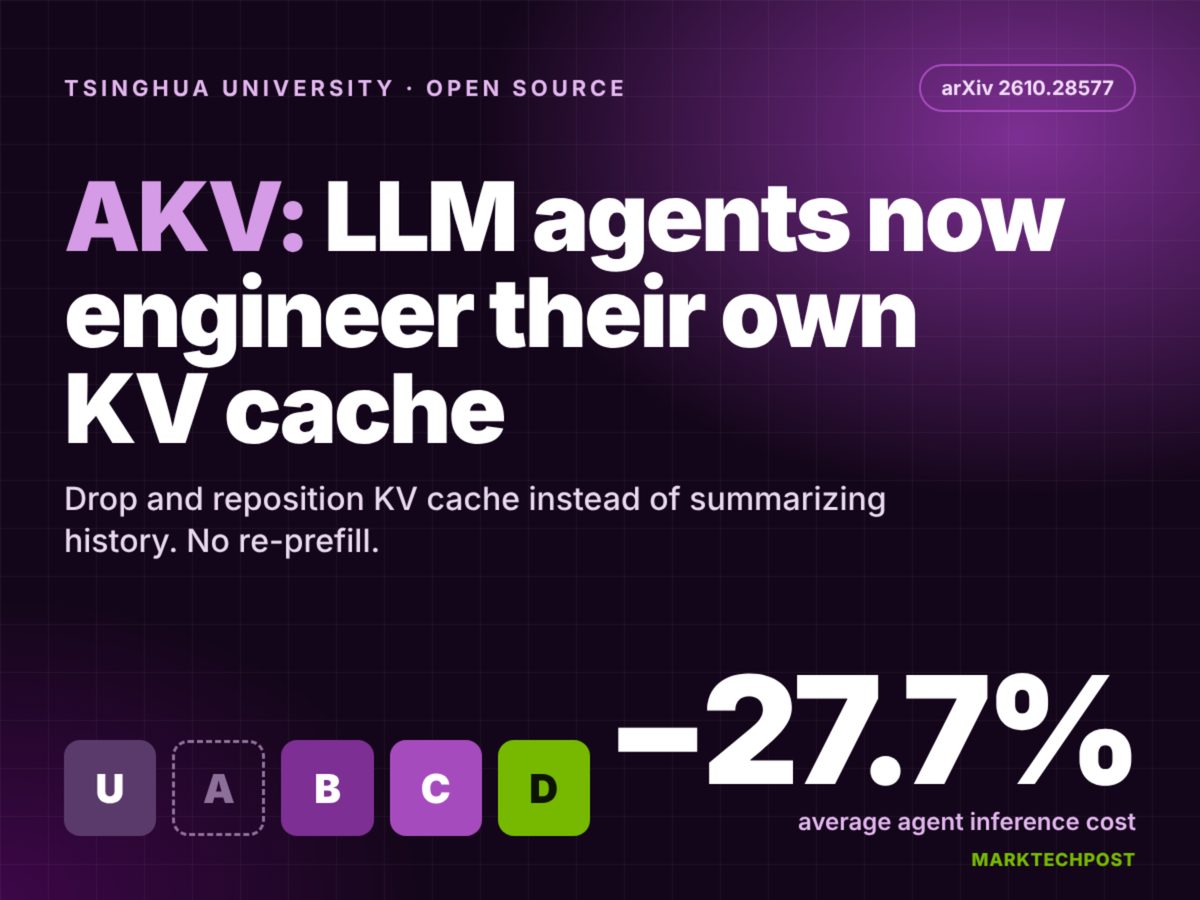
Researchers from Tsinghua University and CUHK have open-sourced AKV, an Apache-2.0 licensed serving system designed for KV cache engineering in LLM agents. Built on the SGLang framework, AKV allows agents to selectively drop and reposition KV cache entries without requiring recomputation or full text history summarization.
Traditional context engineering invalidates downstream KV states when text histories are modified, triggering expensive re-prefill operations. AKV avoids this by leaving text trajectories intact while controlling which cache entries remain visible during attention steps. The system extends SGLang’s radix tree with drop and reposition nodes, introducing three primary operations: Append, Drop, and Repos.
In evaluations across four benchmarks, AKV reduced average per-task costs by 27.7% while raising average task scores by 1.7 points compared to standard baselines. Serving tests on GPT-OSS-120B demonstrated a 1.53x boost in input throughput and significantly reduced P95 request latency during long-context workloads.
Why it matters
Reduces LLM agent inference expenses by 27.7% by preventing redundant prefill operations on long-context task histories.
Improves serving latency for enterprise agent workflows by maintaining stateless, OpenAI-compatible APIs while optimizing KV cache usage in SGLang.
Source: marktechpost.com