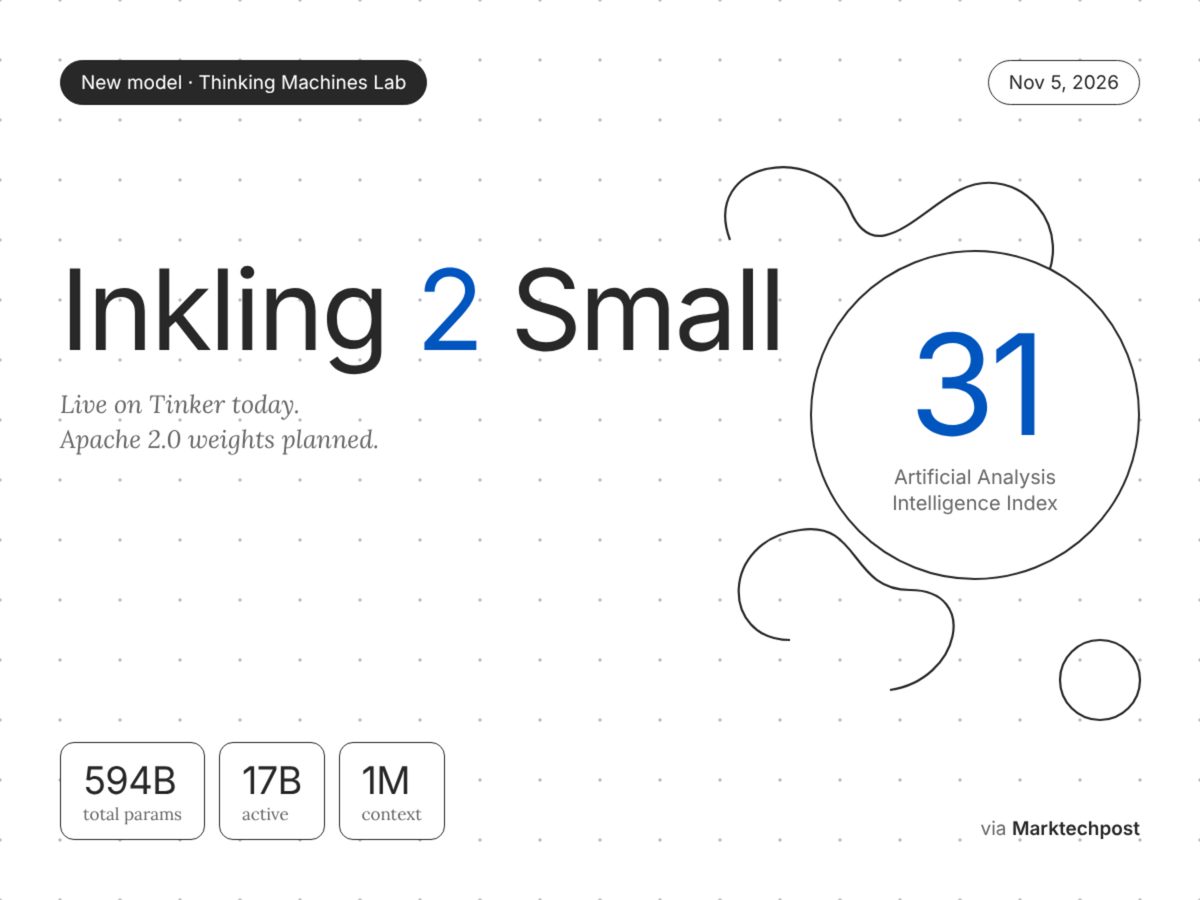
Thinking Machines Lab has launched Inkling 2 Small, the first model in its second-generation Inkling lineup. Built as a sparse Mixture-of-Experts (MoE) architecture with 594 billion total parameters and 17 billion active parameters per token, the model processes text and image inputs while offering variable reasoning effort. It achieved an initial score of 31 on the Artificial Analysis Intelligence Index, significantly surpassing its predecessor’s score of 13.
The model features a 48-layer decoder-only transformer and a 292-million-parameter vision encoder. Training was completed using a joint reinforcement learning run spanning 1,075 steps and over 17 million rollouts across 2,048 GPUs over nine days, consuming more than 4 × 10²³ FLOPs. Thinking Machines noted that coding made up 65% of the RL training tokens.
Inkling 2 Small is currently live on Tinker for inference and fine-tuning at $0.30 per 1 million input tokens and $1.00 per 1 million output tokens. Following red-teaming and external safety testing, the company plans to release open weights under an Apache 2.0 license.
Why it matters
Offers a high-performing open-weights alternative for vision, agentic coding, and knowledge work.
Demonstrates improved alignment techniques that significantly reduced internal misbehavior scores during training.
Provides cost-effective output pricing compared to previous generations and proprietary market alternatives.
Source: marktechpost.com