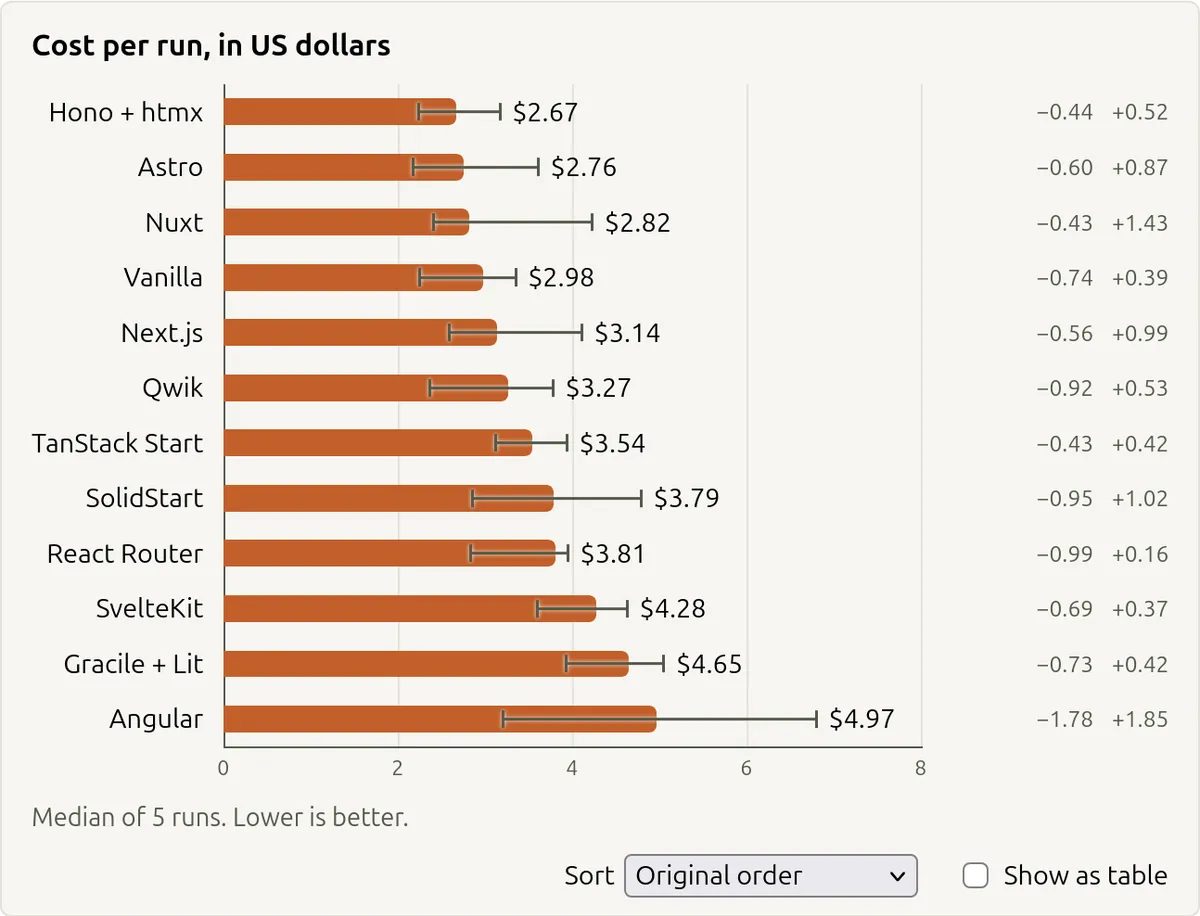
Developer Nolan Lawson created a benchmark to evaluate the performance and quality of web applications generated by AI agents using various JavaScript frameworks. Testing a content-focused Pokémon application spec using Opus 5.5 with official Model Context Protocol (MCP) tooling or skills, the experiment assesses how frameworks impact output performance and accessibility.
To standardize the test, the agent operated in a sandboxed environment without advance knowledge of performance evaluation metrics like Lighthouse, though it was given a conformance test suite. The benchmark evaluated applications against an accessibility tree rather than raw DOM structures to accommodate different framework architectures.
Lawson noted early findings highlight the stochastic nature of testing LLM-generated code, as variable model outputs complicate definitive performance claims regarding which frameworks are optimal for AI-driven development.
Why it matters
Provides empirical benchmark methodology to replace claims about which web frameworks are best suited for AI coding agents.
Highlights the stochastic nature of LLM code generation when evaluating agentic software development tools.
Source: nolanlawson.com