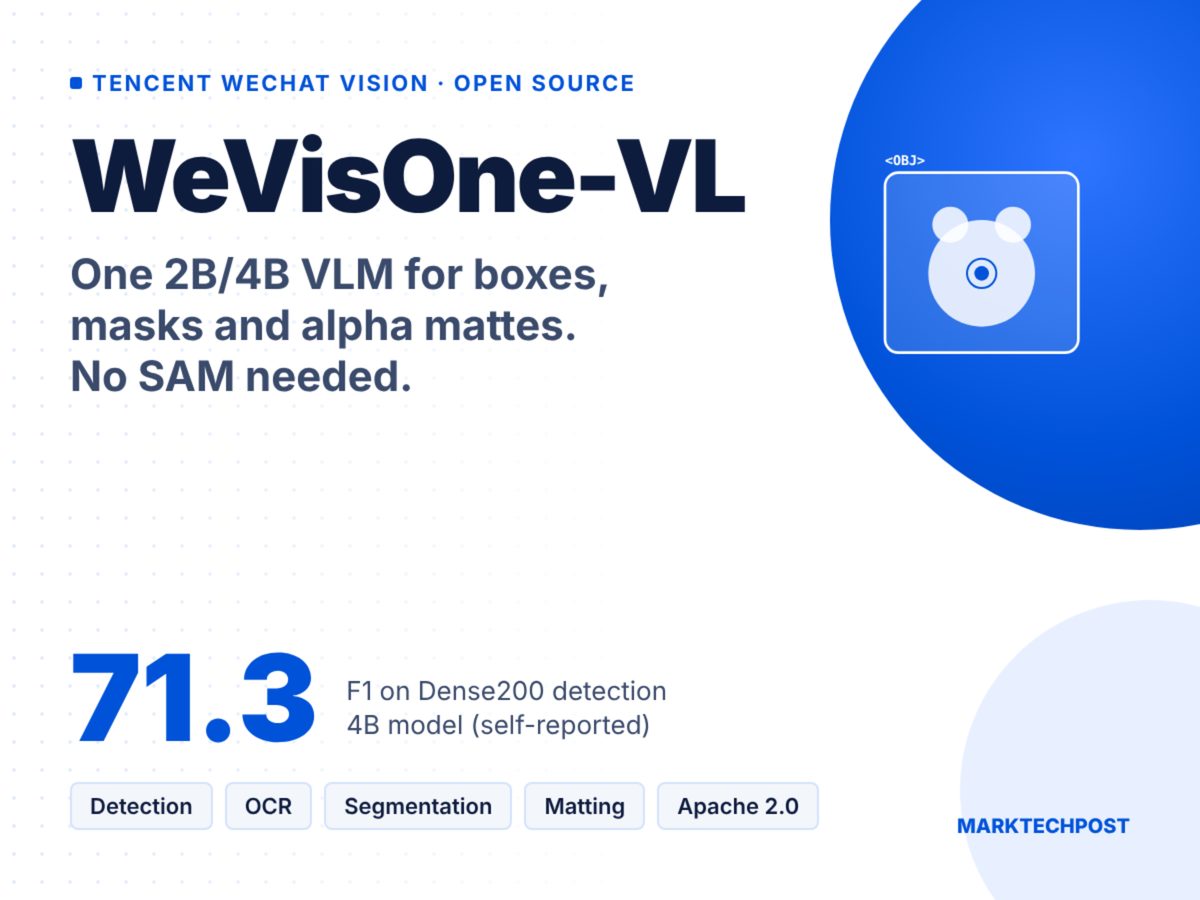
Tencent’s WeChat Vision team has open-sourced WeVisOne-VL, a perception-focused vision-language model released in 2-billion and 4-billion parameter sizes. Built on top of Qwen3-VL, the model consolidates object detection, referring, counting, pointing, OCR, segmentation, and alpha matting into a single architecture. Pixel-level outputs are handled directly by an integrated 9.6-million parameter decoder, eliminating the need for standalone models like SAM.
The model formats perception tasks as structured next-token prediction using normalized coordinate tokens from <0> to <1000>. To reduce hallucinations, the system explicitly returns a “None” output when a queried object is absent from an image. Training relied on a 3-stage supervised fine-tuning pipeline backed by a data engine that annotated over 100 million images.
Model weights for both sizes are published on Hugging Face alongside support for Transformers and vLLM backends. Tencent also open-sourced Mask2Alpha, its matting annotator, though fine-tuning scripts and GGUF mask support remain in development.
Why it matters
Consolidates complex multi-model computer vision pipelines into a single unified 2B or 4B model.
Eliminates auxiliary segmenters like SAM by incorporating an embedded 9.6M parameter pixel decoder.
Explicit “None” outputs mitigate false-positive hallucinated object boundaries in production perception workflows.
Source: marktechpost.com