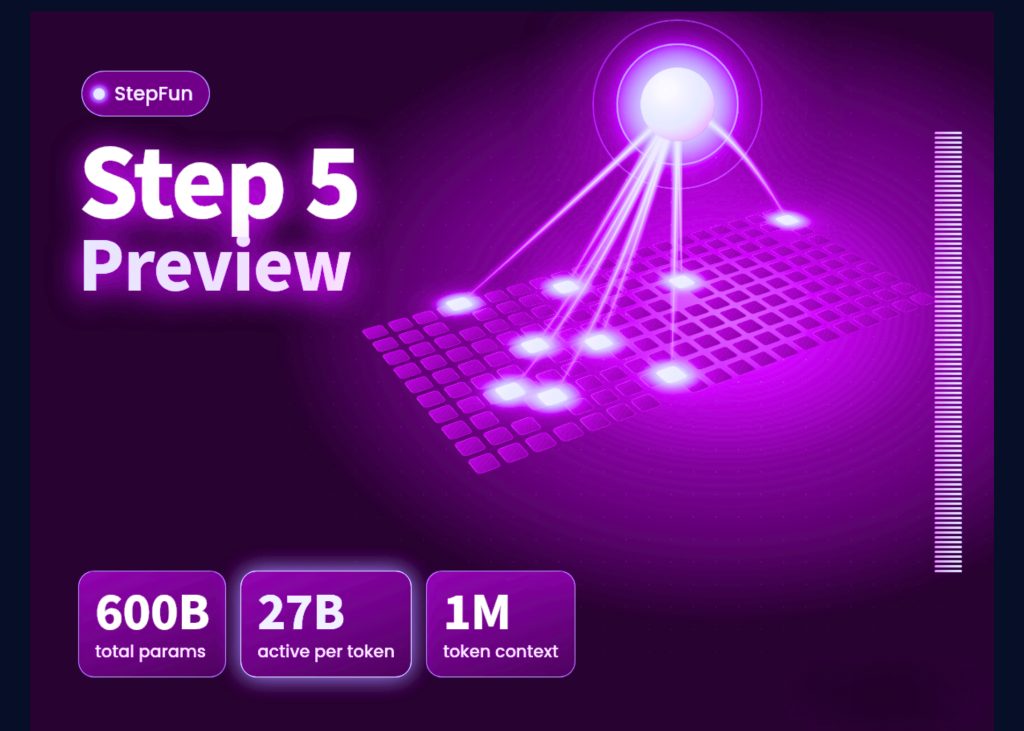
StepFun has unveiled Step 5 Preview, a sparse Mixture-of-Experts (MoE) model featuring 600 billion total parameters and 27 billion active parameters per token. Designed for long-horizon agentic tasks in software engineering, finance, and professional work, the model utilizes a narrow-deep architecture with 92 Transformer layers and a 1-million-token context window. StepFun plans to release open weights on October 15, 2026, while currently offering access via a hosted API and its primary platform.
To optimize training and inference, StepFun employed techniques such as on-policy long-horizon reinforcement learning, MTP-3 speculative decoding, FP8 MoE, and KV-cache offload. The company reports more than 3x end-to-end speedups for long-horizon RL and benchmarked performance including a 67.7 score on DeepSWE v1.1 and automated optimization of GPU kernels and sub-models during 24-hour agentic evaluations.
Independent testing by Artificial Analysis evaluated Step 5 Preview at an Intelligence Index score of 44—above the price-tier median of 24—at an output speed of 99.8 tokens per second. However, evaluators noted that verbose reasoning led to higher total output token counts, which partially offsets per-token cost savings.
Why it matters
Open-weights release scheduled for October 15 provides teams an option for local, deep-stack MoE deployment.
Deep 92-layer architecture and long prefill optimization specifically target complex multi-step reasoning and automated agent tasks.
Verbose output generation can increase overall token volume, impacting net deployment costs despite lower per-token pricing.
Source: marktechpost.com