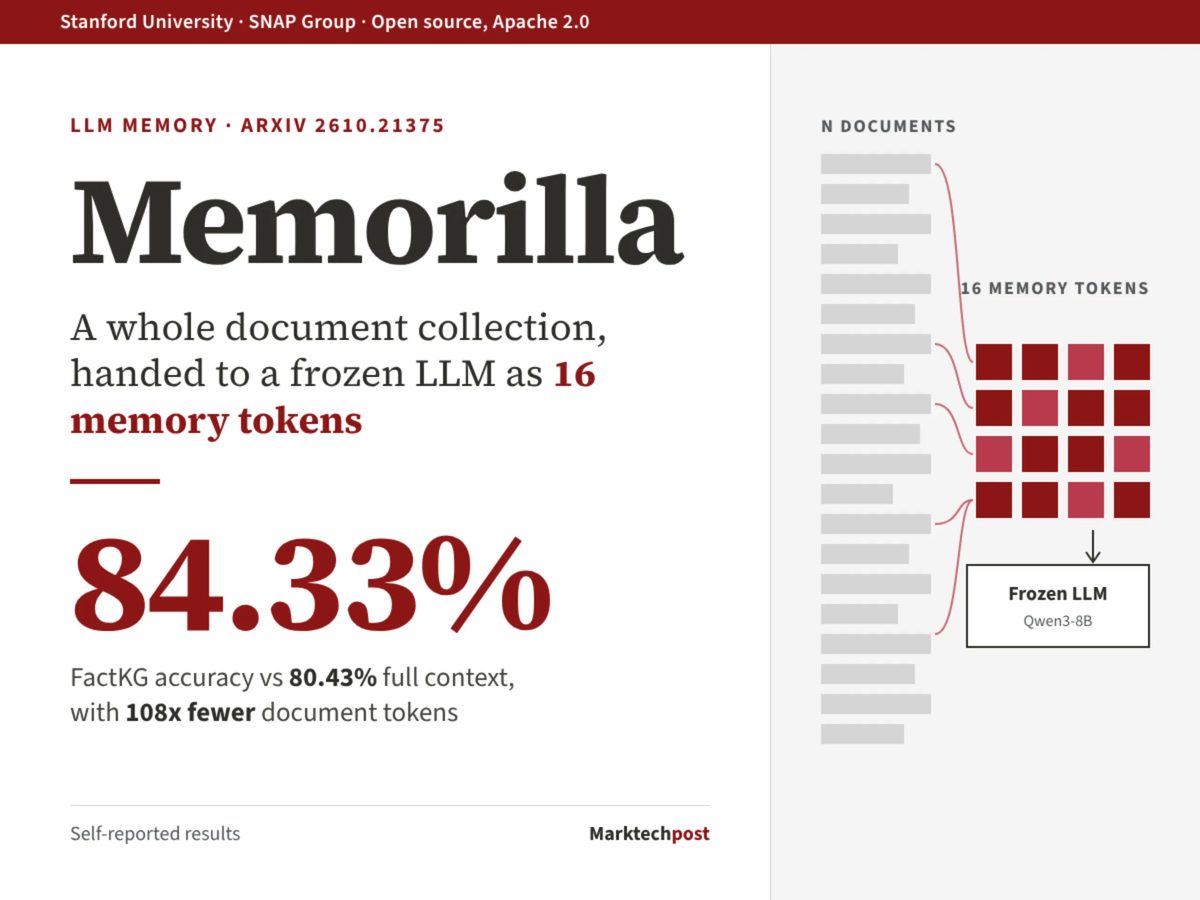
Researchers at Stanford University’s SNAP group have open-sourced Memorilla, a latent memory module under Apache 2.0 that drastically reduces context overhead for large language models. The system converts entire document stores into just 16 memory vectors passed to a frozen LLM, achieving a 27x speedup over full-context prompting on 128K-token workloads while outperforming full-context baselines on benchmarks like FactKG.
Why it matters
Significantly lowers inference latency and token costs for enterprise applications processing massive document stores.
Enables high-accuracy retrieval and personalization for frozen LLMs without expensive full-context window utilization.
Source: marktechpost.com