At IFA 2026, Nvidia, Microsoft, and software partners unveiled new local inference optimizations and simplified setup experiences for popular AI agents on Windows PCs. Built on llama.cpp, the streamlined setup reduces manual configuration steps such as quantization tuning and inference server setup for systems equipped with RTX GPUs and DGX Spark hardware. Compact RTX Spark Windows PCs were also announced for release in October.
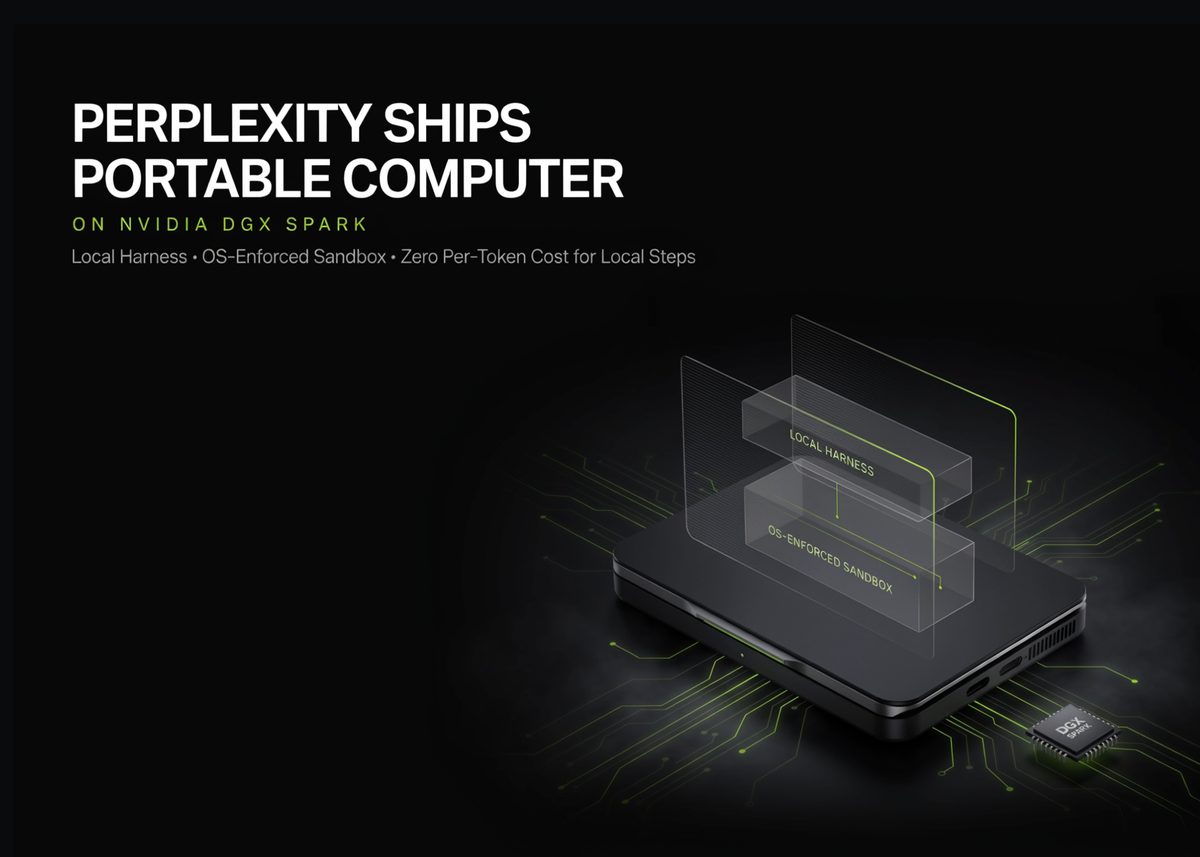
Key agent applications incorporating these built-in optimizations include Perplexity Portable Computer, Nous Research’s Hermes Agent, and OpenClaw. Perplexity’s application enables local workflows that execute privately while granting permissions to escalate complex requests to cloud frontier models. Hermes Agent introduces one-click GPU detection and automatic model selection on Windows, allowing context persistence and skill development locally.
Additionally, the OpenClaw Windows App brings optimized local model execution to any RTX GPU with at least 24GB of VRAM, expanding edge capabilities for developers, creators, and enterprise users.
Why it matters
Simplifies edge deployment for agent builders by removing manual environment configuration on local Windows hardware.
Enables privacy-focused enterprise workflows by keeping sensitive data on-device with optional cloud escalation.
Source: blogs.nvidia.com