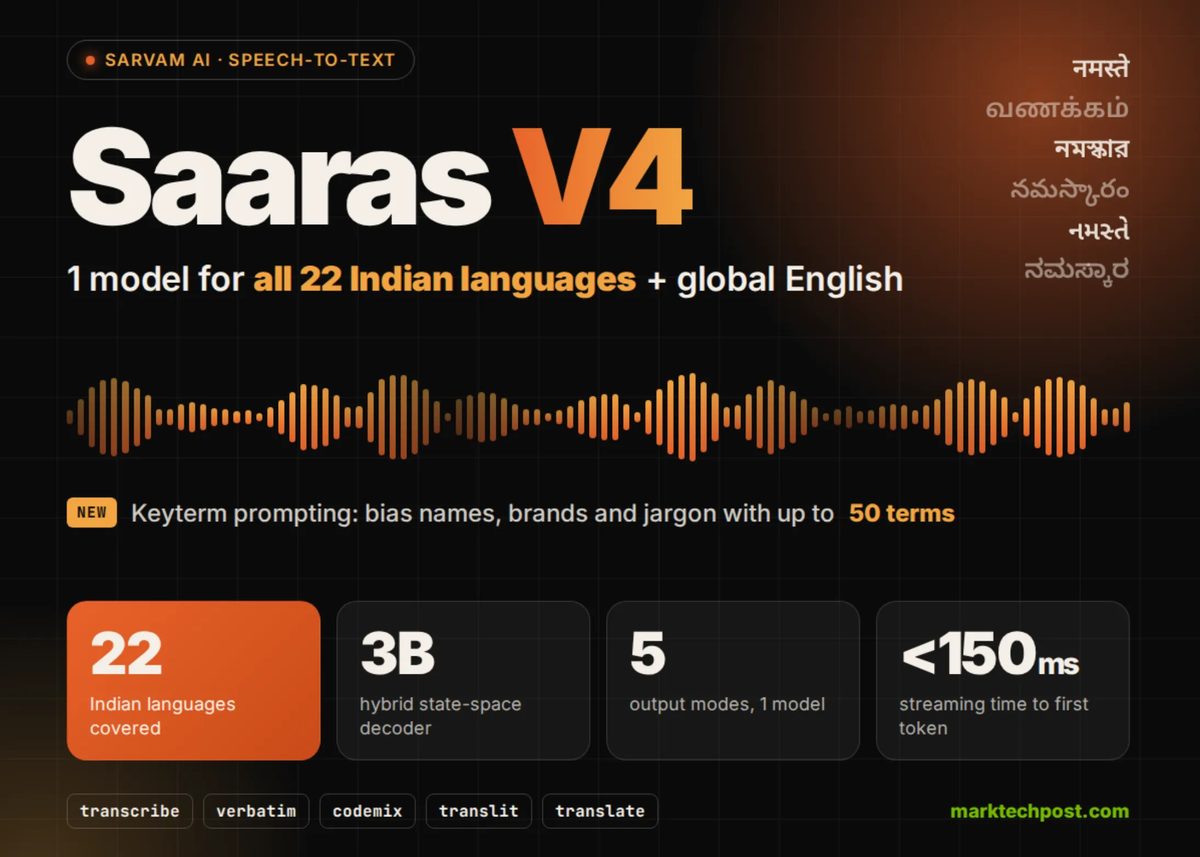
Sarvam AI has announced the launch of Saaras V4, its latest speech-to-text model covering all 22 scheduled Indian languages alongside global English accents. Powered by a custom 3-billion-parameter hybrid state-space language model (Sarvam-3B), the encoder-decoder system processes audio waveforms directly into embeddings to manage long recordings. The model is immediately available for integration via Sarvam’s API using the standard request shape.
Key features in Saaras V4 include keyterm prompting for domain-specific context biasing and a dedicated codemix mode designed to preserve foreign brand names in Latin script. According to vendor-reported benchmarks on IndicContextEval, the model achieved a 16.03% Word Error Rate in keyword-prompting tests, which Sarvam claims is the lowest recorded score on the benchmark.
While Saaras V4 offers an immediate API upgrade path for developers, weights remain proprietary and independent reproduction has not yet been published. Saaras v3 currently remains the default model in Sarvam’s developer documentation while self-hosting support for V4 remains pending.
Why it matters
Provides native API support for complex multilingual and code-mixed speech recognition across Indian regional markets.
Keyterm prompting features reduce post-processing overhead for enterprise applications handling specialized brand or domain terminology.
Proprietary model weights limit self-hosted enterprise deployments to vendor API environments for the time being.
Source: marktechpost.com