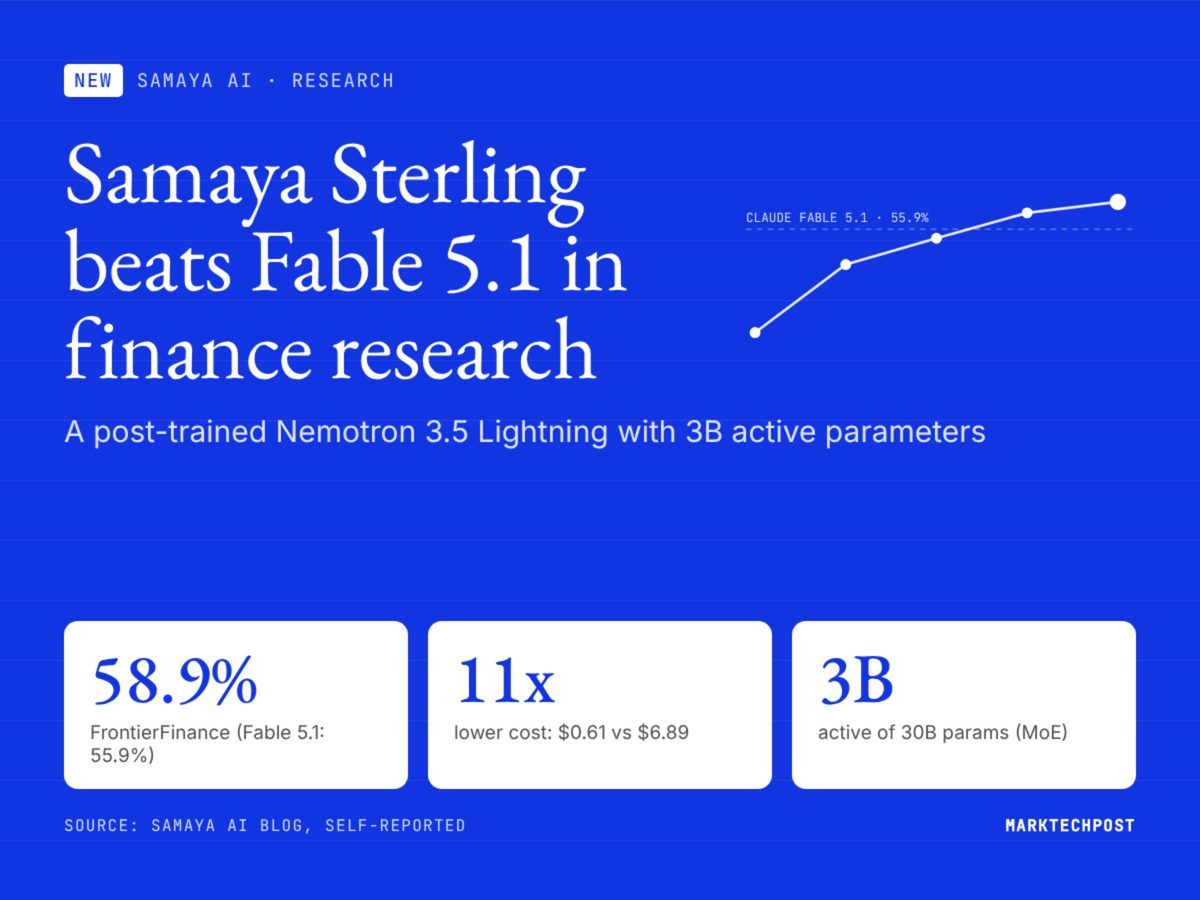
Samaya AI has released Samaya Sterling, a post-trained model tailored for agentic financial research. Built on NVIDIA’s 30B Nemotron 3.5 Lightning mixture-of-experts architecture, Sterling utilizes just 3B active parameters. On Samaya’s FrontierFinance benchmark, the model scored 58.9%, outperforming Anthropic’s Claude Fable 5.1 (55.9%) while drastically lowering inference costs from $6.89 to $0.61 per query.
To achieve these domain-specific results, Samaya adapted its production finance harness by stripping detailed system prompts and merging tool descriptions. Two auxiliary helper models manage context by condensing tool outputs and summarizing execution traces. Sterling was trained in four stages via LoRA on Thinking Machines Lab’s Tinker API, combining specialized tool orchestration with a designated report-writing model.
The release provides a concrete blueprint for developers, demonstrating that tightly co-training a compact model with its execution harness can outperform larger, general-purpose models in specialized enterprise domains. All benchmark figures are self-reported by Samaya AI, which has released the dataset, grader repository, and technical post publicly.
Why it matters
Small, domain-tuned active parameter models can beat frontier LLMs on complex agentic tasks while slashing compute costs over 10x.
Co-training light models alongside custom harnesses and context-helper models offers a scalable blueprint for vertical enterprise AI.
Benchmark performance demonstrates that agentic efficiency depends more on prompt optimization and system orchestration than sheer parameter size.
Source: marktechpost.com