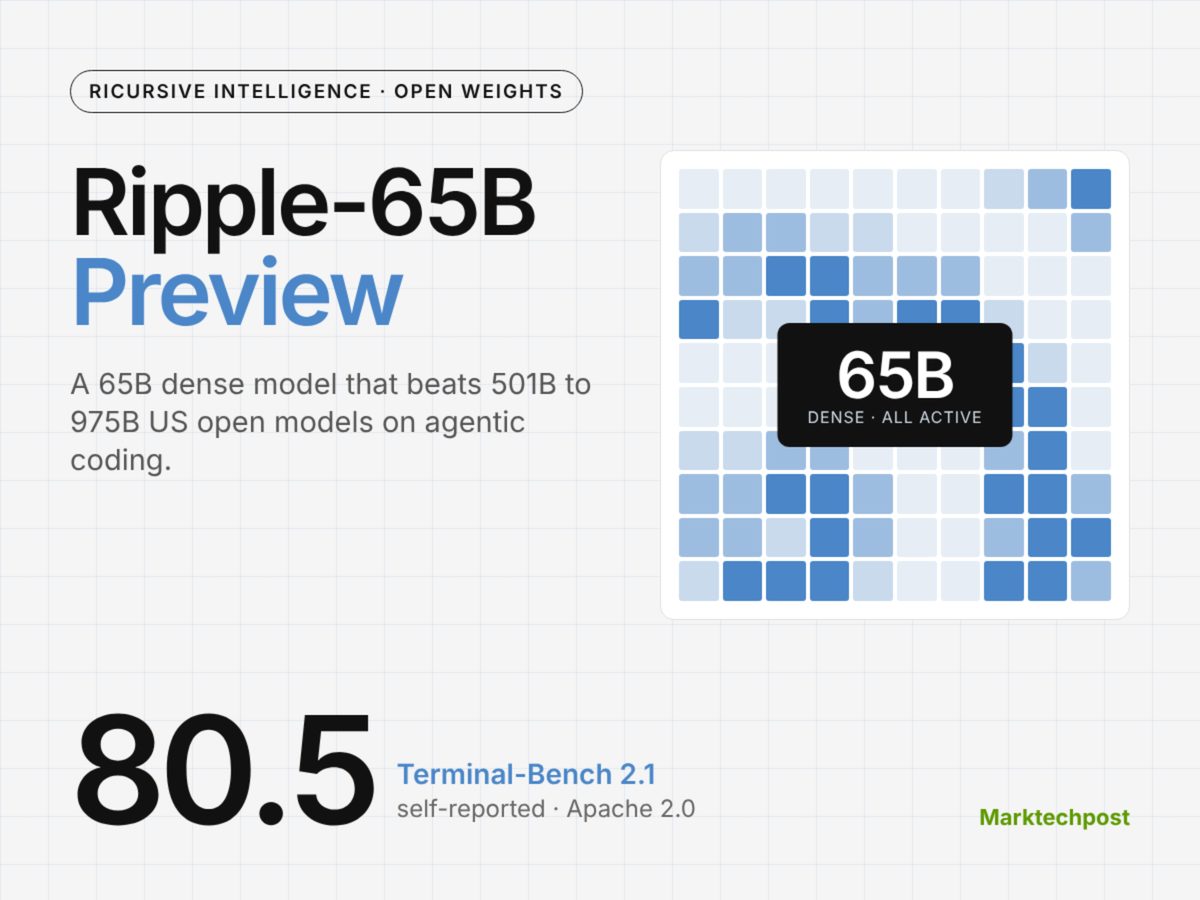
Ricursive Intelligence released Ripple-65B Preview, an open-weight 65-billion parameter dense model designed specifically for agentic coding applications. The company reported a top US open-weight score of 80.52 on Terminal-Bench 2.1, surpassing several larger Mixture-of-Experts models ranging from 501B to 975B parameters.
The project incurred $32 million in total R&D costs, spanning architectural experiments, synthetic data pipelines, and final training runs. Ricursive selected a dense Transformer architecture featuring 80 layers and a 5120 hidden dimension over MoE to simplify serving infrastructure, achieving 40 percent MFU during pretraining. Post-training involved long-context SFT up to 2 million sequence lengths and RL optimization.
The weights are published under an Apache 2.0 license across three checkpoints, including NVFP4 quantization for edge deployment on devices like NVIDIA DGX Spark. Inference throughput reaches 250 tokens per second on two B200 GPUs at batch size 8 prior to quantization.
Why it matters
Dense architectural choices provide lower deployment and infrastructure complexity compared to high-parameter MoE alternatives for coding agents.
Open Apache 2.0 licensing and native NVFP4 checkpoints allow enterprise teams to deploy high-performing coding models locally.
Targeted synthetic data generation and efficient RL algorithms significantly lower the capital required to train competitive frontier coding models.
Source: marktechpost.com