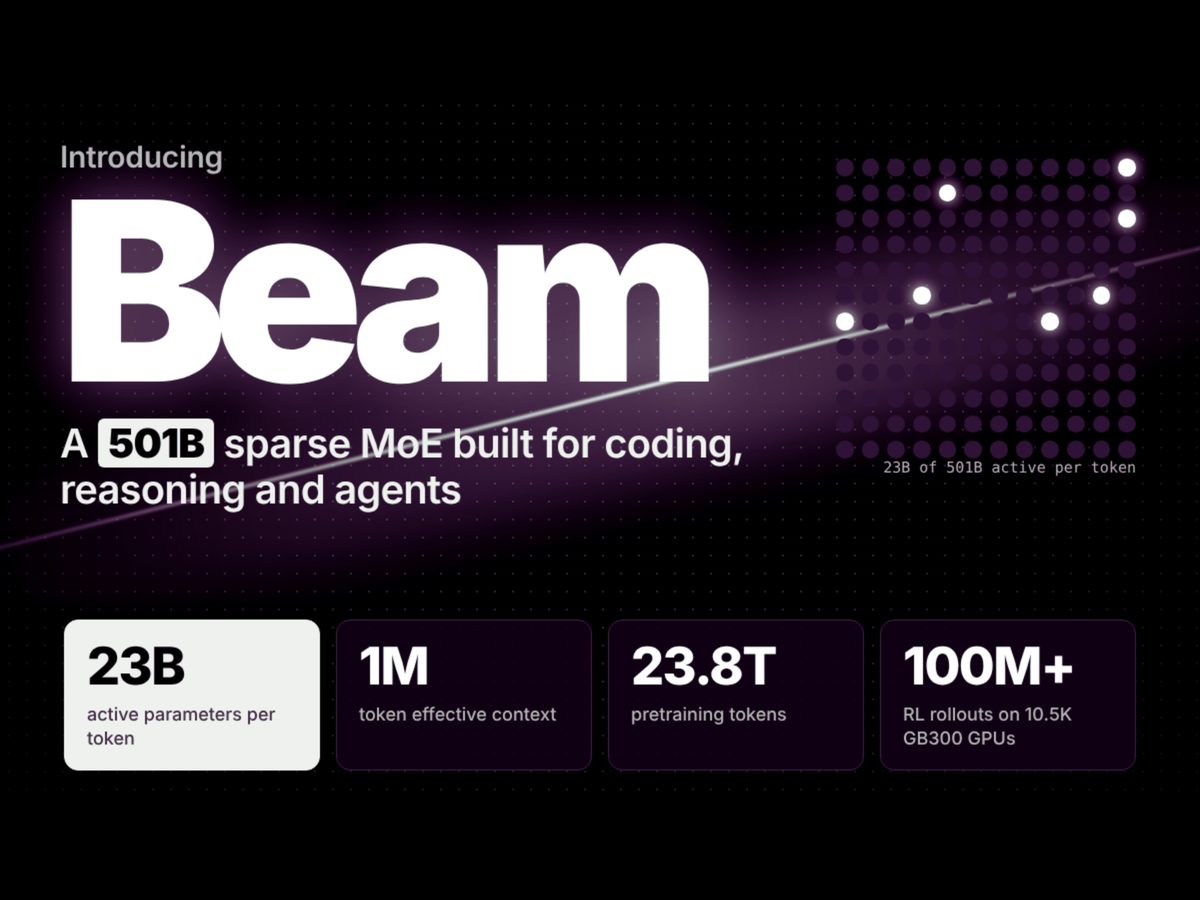
Reflection AI has introduced Beam, a 501-billion total parameter Mixture-of-Experts (MoE) model featuring 23 billion active parameters per token. According to the company, Beam matches or surpasses rival open models like GLM 5.2 on reasoning benchmarks while consuming 3x to 4x less inference compute. The model is currently undergoing final red-teaming with waitlist access available via Reflection’s platform prior to public weights release.
Pretrained on 23.8 trillion tokens, the model was built using 6,144 NVIDIA GB300 NVL72 GPUs over four weeks. Reflection applied asynchronous reinforcement learning using 10.5K GB300 GPUs over a subsequent four-week period, running more than 100 million rollouts across 1.3 billion sandbox environments. The model architecture uses local and global attention alongside auxiliary-loss-free expert load balancing derived from DeepSeek-V3 techniques.
In internal evaluations, Beam recorded a score of 80.9 on SWE-bench Verified, outpacing Nemotron 3 Ultra’s 70.7 score. On Terminal Bench v2.1, Beam scored 80.1, placing it just behind GLM 5.2 (81.0) and DeepSeek V4.1 Flash (90.6). The model incorporates a variable reasoning effort parameter, enabling enterprise users to scale compute depending on task complexity.
Why it matters
Enterprise teams can scale reasoning compute dynamically using controllable effort parameters to save inference costs.
Developers gain high-performing open-weight coding agents capable of competing with closed top-tier models.
ML engineers benefit from architectural techniques like auxiliary-loss-free balancing to improve MoE training stability.
Source: marktechpost.com