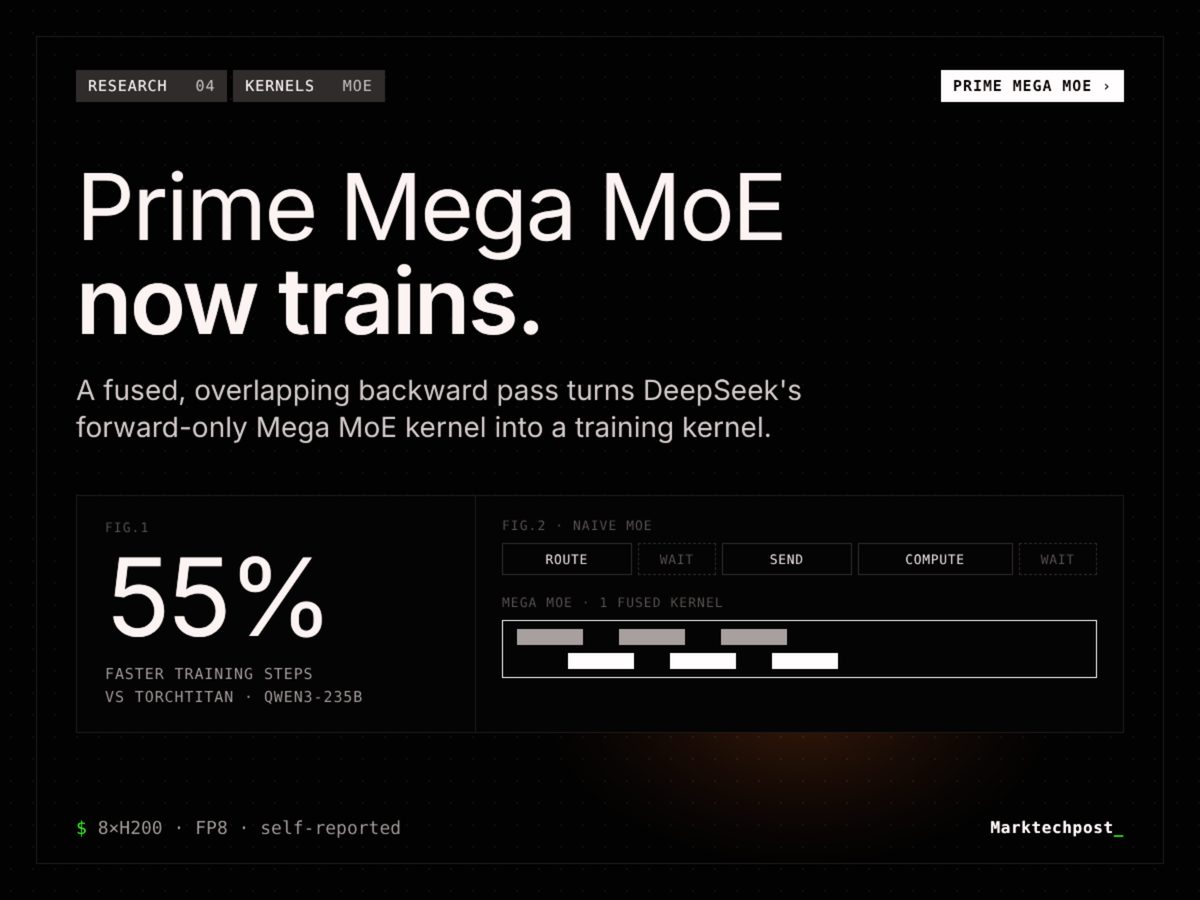
Prime Intellect announced the release of Prime Mega MoE, a fused and overlapping training extension built on DeepSeek’s open-source DeepGEMM library. While DeepSeek’s original Mega MoE kernel only executed forward passes, Prime Intellect added a fast, overlapping backward pass, making fused kernels viable for complete model training rather than just inference.
According to the company, integration into its prime-rl trainer yielded full training step speedups of up to 34% on Qwen3 MoE models and up to 55% compared to TorchTitan on 8×H200 nodes. The kernel achieves these performance improvements by overlapping compute and expert-parallel dispatch operations while utilizing GPU-only scratch buffers to bypass intermediate tensors.
Prime Mega MoE is available as a dispatch backend in prime-rl, supporting precision formats such as BF16, MXFP8 for Blackwell, and blockwise FP8 for Hopper architectures.
Why it matters
Significantly decreases training GPU hours for teams building or fine-tuning Mixture-of-Experts architectures.
Enables faster overlapping backward passes in FP8 and MXFP8 precision across modern Hopper and Blackwell clusters.
Offers an open-source alternative to standard TorchTitan setups with seamless integration inside the prime-rl ecosystem.
Source: marktechpost.com