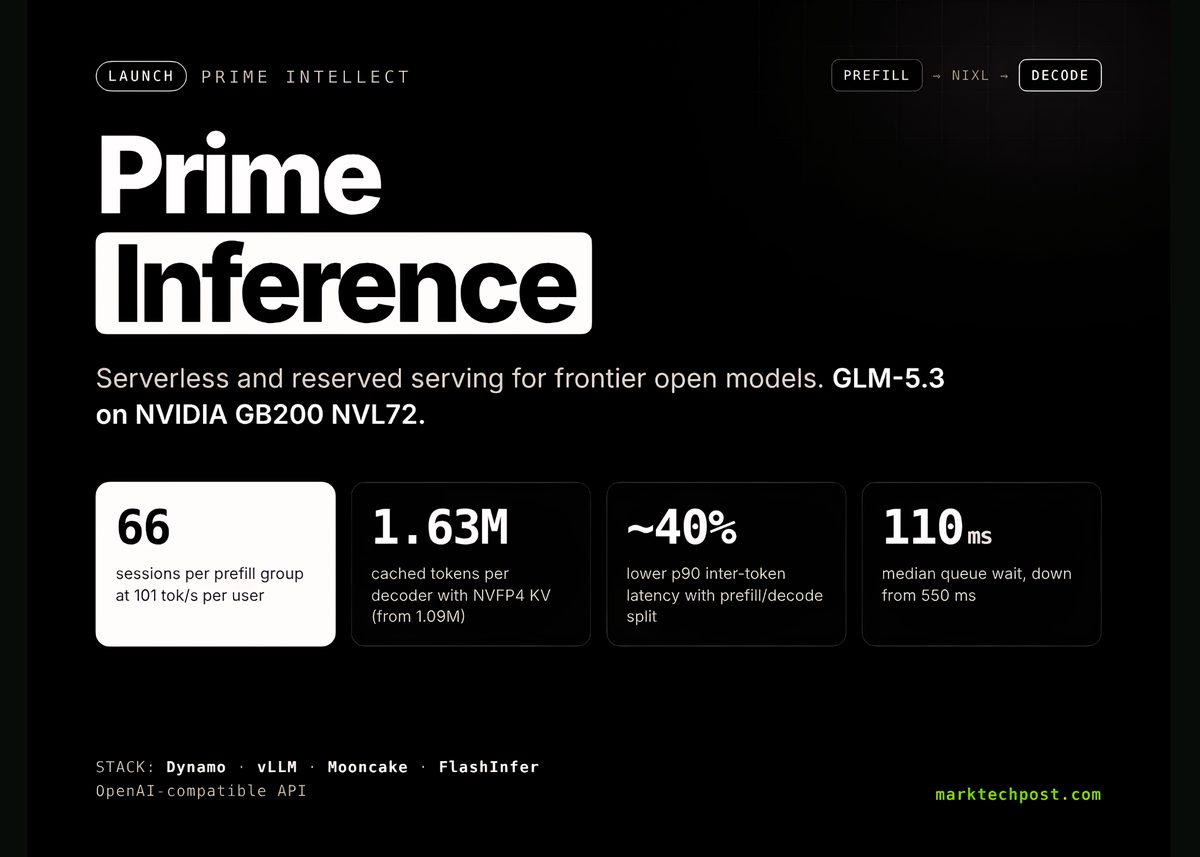
Prime Intellect has launched Prime Inference, a serving platform specifically engineered for frontier open-source models. Operating as the serving layer for Prime Intellect’s open training stack, the platform provides serverless endpoints alongside reserved GPU capacity across multiple data centers. Prior to its public release, Prime Inference processed nearly a trillion tokens per day internally across workloads such as RL rollouts, synthetic data generation, and long-running coding agents.
Technically, the infrastructure utilizes prefill and decode disaggregation on separate GPU groups using NVIDIA Dynamo, vLLM, Mooncake, and FlashInfer. Prime reports a near-zero tool-call error rate, 100% uptime since launch, and almost 40% lower p90 inter-token latency in tests. The setup was built in collaboration with Inferact and NVIDIA, targeting agentic interactivity speeds of 100 end-to-end tokens per second per user.
Why it matters
Enables developers to run agentic LLM workloads with disaggregated prefill/decode, significantly reducing p90 inter-token latency.
Integrates model serving directly with training loops, allowing production traces to easily feed back into open post-training pipelines.
Improves tool-call reliability by implementing schema masking and structural-tag builders specifically tailored for complex agent workflows.
Source: marktechpost.com