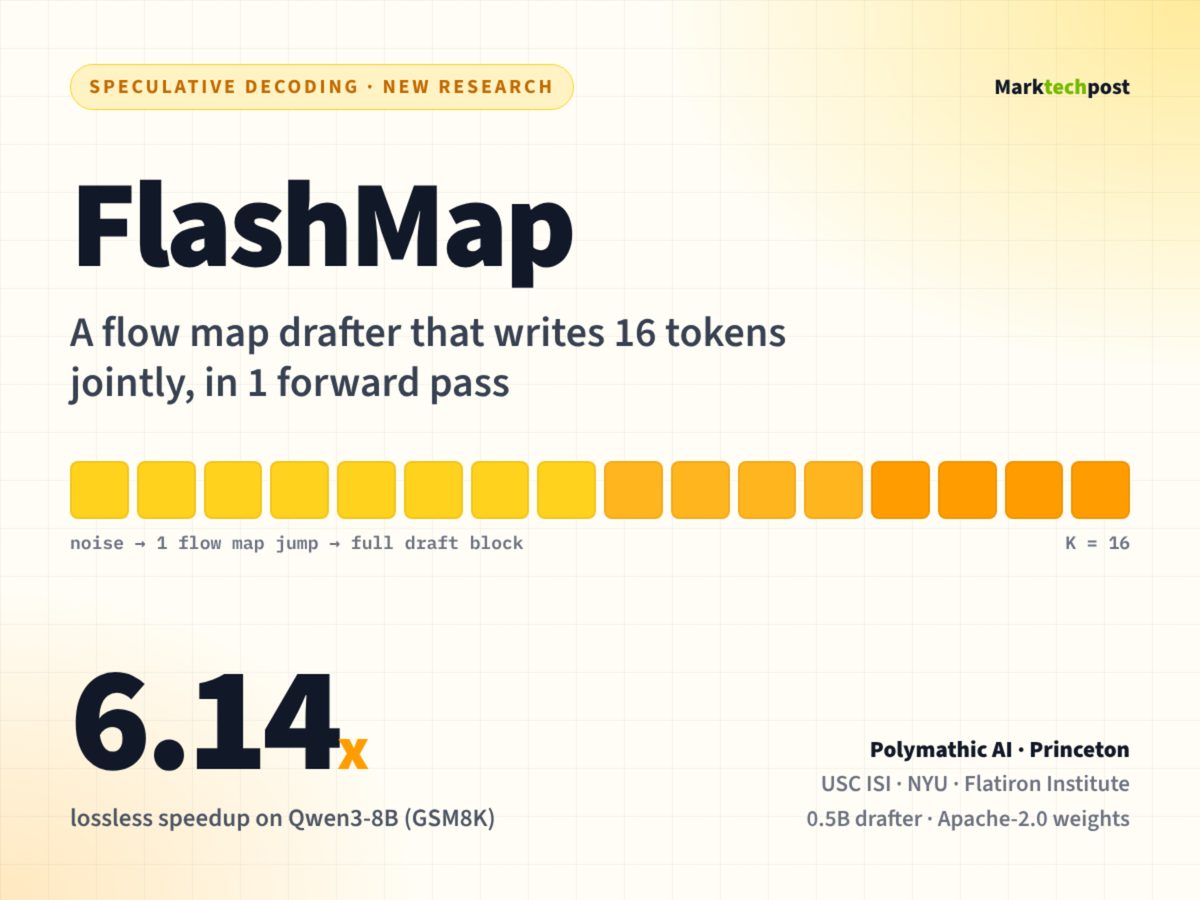
Researchers from Polymathic AI, Princeton University, USC ISI, NYU, and the Flatiron Institute have introduced FlashMap, an open-source continuous flow map drafter for speculative decoding. Designed to accelerate large language model decoding, FlashMap drafts a full 16-token block in a single forward pass by mapping continuous Gaussian noise to target token structures.
The research team reported lossless speedups up to 6.14x on the GSM8K benchmark when pairing FlashMap with Qwen3-8B. Unlike traditional speculative drafting methods that generate tokens sequentially or independently, FlashMap preserves structural dependencies between tokens in a block, leading to significantly higher acceptance rates during target model verification passes.
FlashMap drafter weights for Qwen3-8B and Qwen3-4B have been published on Hugging Face, alongside plugins for high-throughput serving engines including vLLM and SGLang. The underlying codebase requires standard PyTorch dependencies and can be integrated into existing inference setups via standard generation calls.
Why it matters
Significantly lowers inference costs and latency for enterprise LLM deployments through efficient speculative decoding.
Replaces autoregressive block drafting with continuous flow mapping to achieve high token acceptance rates without loss of quality.
Offers immediate integration for open-source serving frameworks like vLLM and SGLang, lowering operational overhead for developers.
Source: marktechpost.com