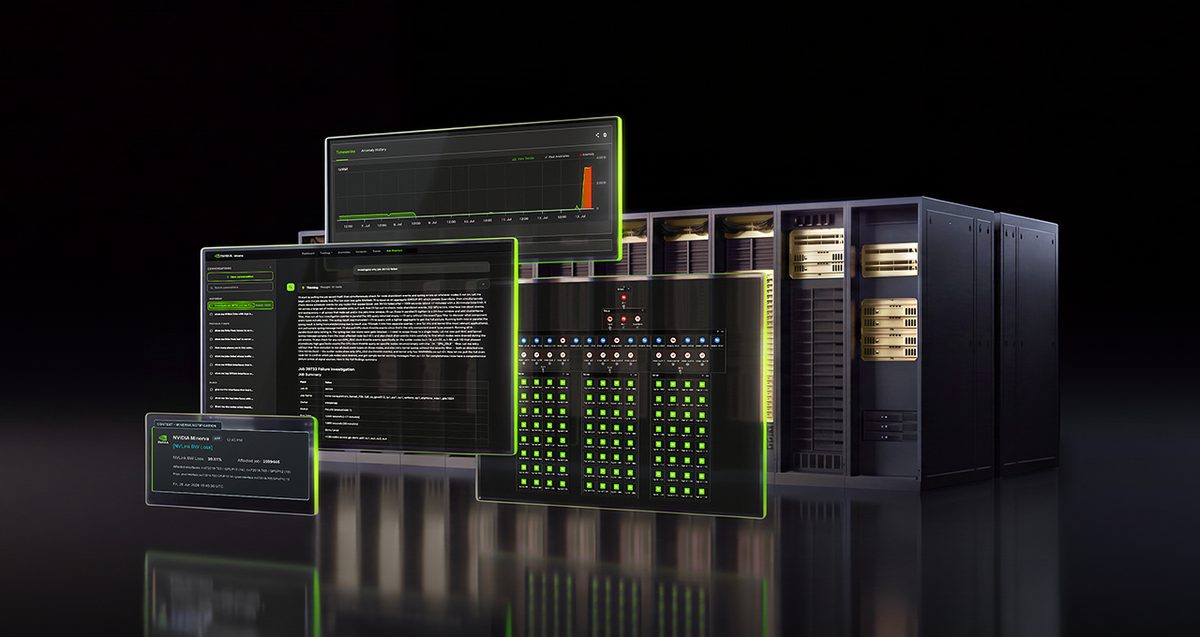
NVIDIA has launched Minerva, an AIOps platform built to monitor, diagnose, and optimize data center infrastructure powering large-scale AI operations. Designed to maximize “AI factory yield”—measured through GPU uptime, goodput, token production, and cluster availability—Minerva aggregates multi-layer telemetry across compute, networking, storage, and job schedulers into a consolidated operational view.
The platform constructs a dynamic knowledge graph that continuously maps physical infrastructure—including GPUs, SuperNICs, and switches—to active workloads. Minerva uses machine learning models to analyze telemetry data, detect anomalies, and correlate scattered system alerts into unified incidents with root-cause diagnoses. The system also features a natural-language conversational AI interface, allowing system operators to investigate telemetry data and execute remediations via automated APIs.
Multiple hardware manufacturers and cloud operators, including Dell Technologies, Lenovo, Supermicro, IREN, Bitdeer AI, IBM, Lambda, and Tesla, plan to integrate or deploy Minerva. According to partner IREN, the single-pane visibility allows operations teams to shift focus toward proactive maintenance and maximize overall GPU productivity across expanding infrastructure.
Why it matters
Addresses critical operational bottlenecks in massive GPU clusters where single-component degradations severely reduce overall training and inference output.
Provides data center operators and cloud providers a unified topology map correlating raw hardware telemetry directly with running AI workloads.
Strengthens NVIDIA’s ecosystem lock-in by pairing hardware sales with proprietary enterprise management and observability software.
Source: blogs.nvidia.com