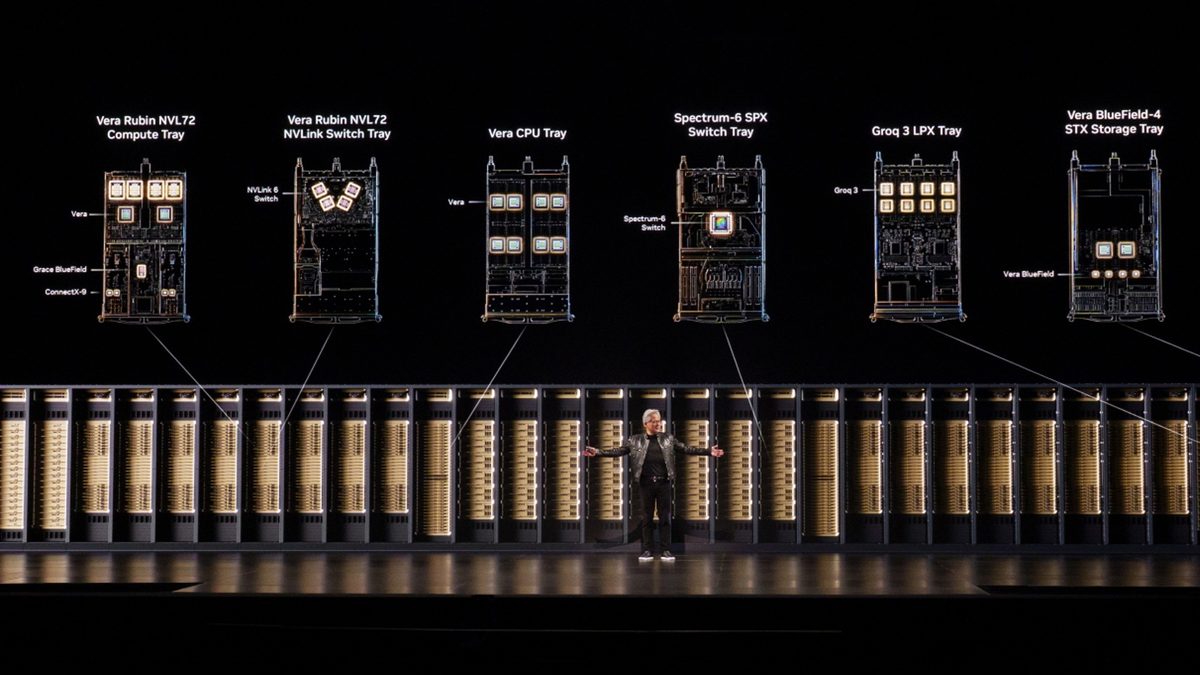
NVIDIA announced performance results for its new Vera Rubin platform across the latest MLPerf Training v6.1 benchmarks and MLPerf Endpoints tests. The company achieved clean sweeps across every training workload category, including LLMs, reinforcement learning, and image generation.
In its benchmark debut, the Vera Rubin NVL72 demonstrated up to double the per-GPU performance of the GB300 NVL72 generation. Scaling tests showed 97% training efficiency when expanding from 256 to 1,024 GPUs on DeepSeek-V3, while cloud partners like Microsoft Azure deployed up to 10,240 NVIDIA GPUs in unified benchmark runs.
For agentic workloads, Vera Rubin systems yielded over 10x generational throughput-per-watt improvements compared to GB300 hardware on models like Kimi K3, addressing critical data center power limitations during multi-step AI reasoning.
Why it matters
Demonstrates 2x per-GPU generational gains and 10x power efficiency improvements for serving multi-step AI agents.
Validates near-linear linear scaling performance across 10,000+ GPU clusters for frontier model training.
Reinforces NVIDIA’s competitive moat across hardware and software in supercomputing and enterprise data centers.
Source: blogs.nvidia.com