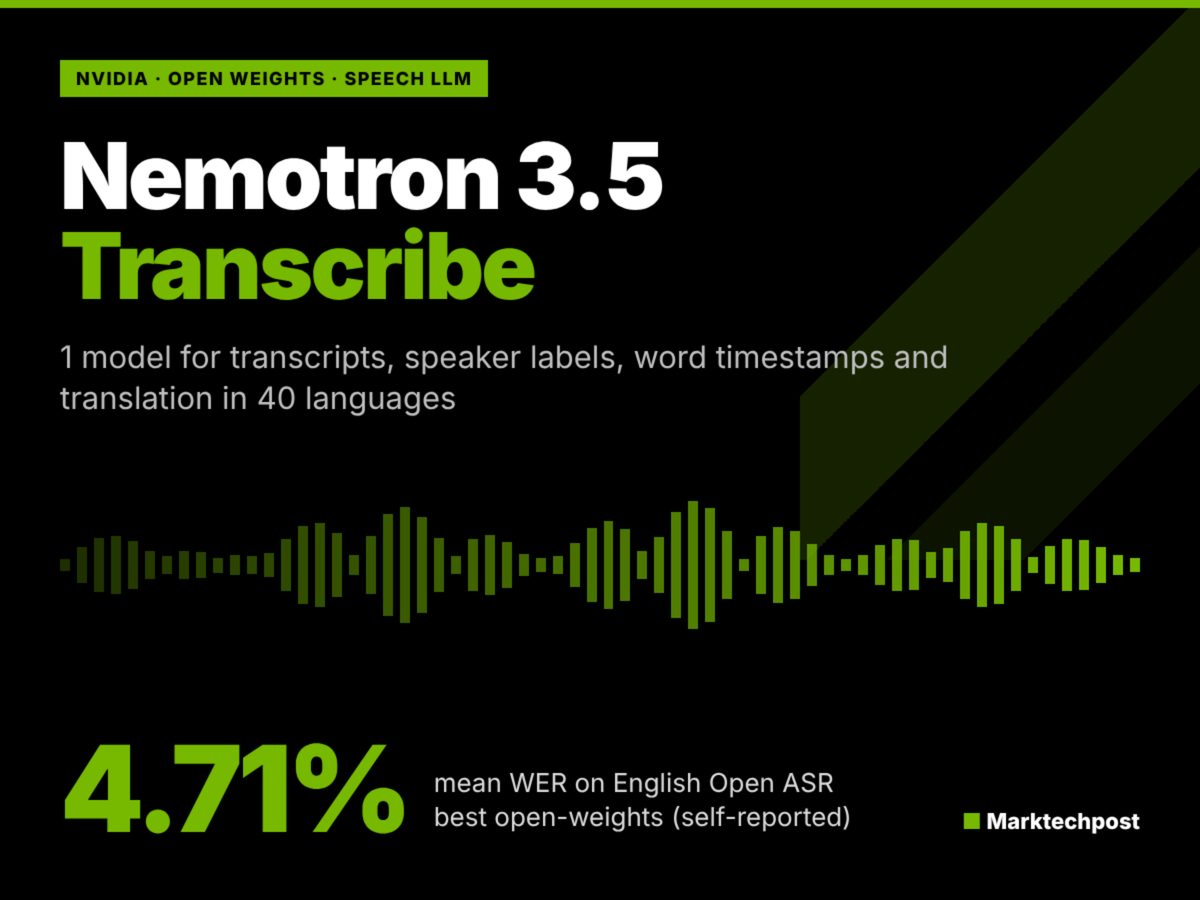
NVIDIA has released Nemotron 3.5 Transcribe, an open-weights 30B mixture-of-experts (MoE) speech LLM optimized for transcription across 40 languages. The checkpoint contains roughly 34B total parameters, active parameters around 4B, and combines an audio encoder with an LLM decoder. The model allows developers to customize output styles—including verbatim, written form, contextual, or translated output—using standard text prompts.
The model was trained on 256 H100 GPUs using supervised fine-tuning and reinforcement learning over 1.72 million unique hours of audio. According to NVIDIA’s technical report, Nemotron 3.5 Transcribe achieves up to 2,238 seconds of processed audio per second on a single RTX PRO 6000 Blackwell Server Edition using NVFP4 precision and DFlash2 speculative drafting via its proprietary NIM microservice.
Released under the OpenMDW-1.1 license for commercial use, the model supports open runtimes including vLLM, Transformers, and SGLang-Omni. However, NVIDIA noted that the highest-performance NIM microservice optimizations remain proprietary, with standard open-source vLLM implementations running roughly two times slower.
Why it matters
Provides an open-weights, commercially usable 30B MoE model that consolidates speech recognition, diarization, and formatting into promptable workflows.
Achieves high inference throughput on Blackwell server hardware, though maximum optimization relies on NVIDIA’s proprietary NIM stack.
Source: marktechpost.com