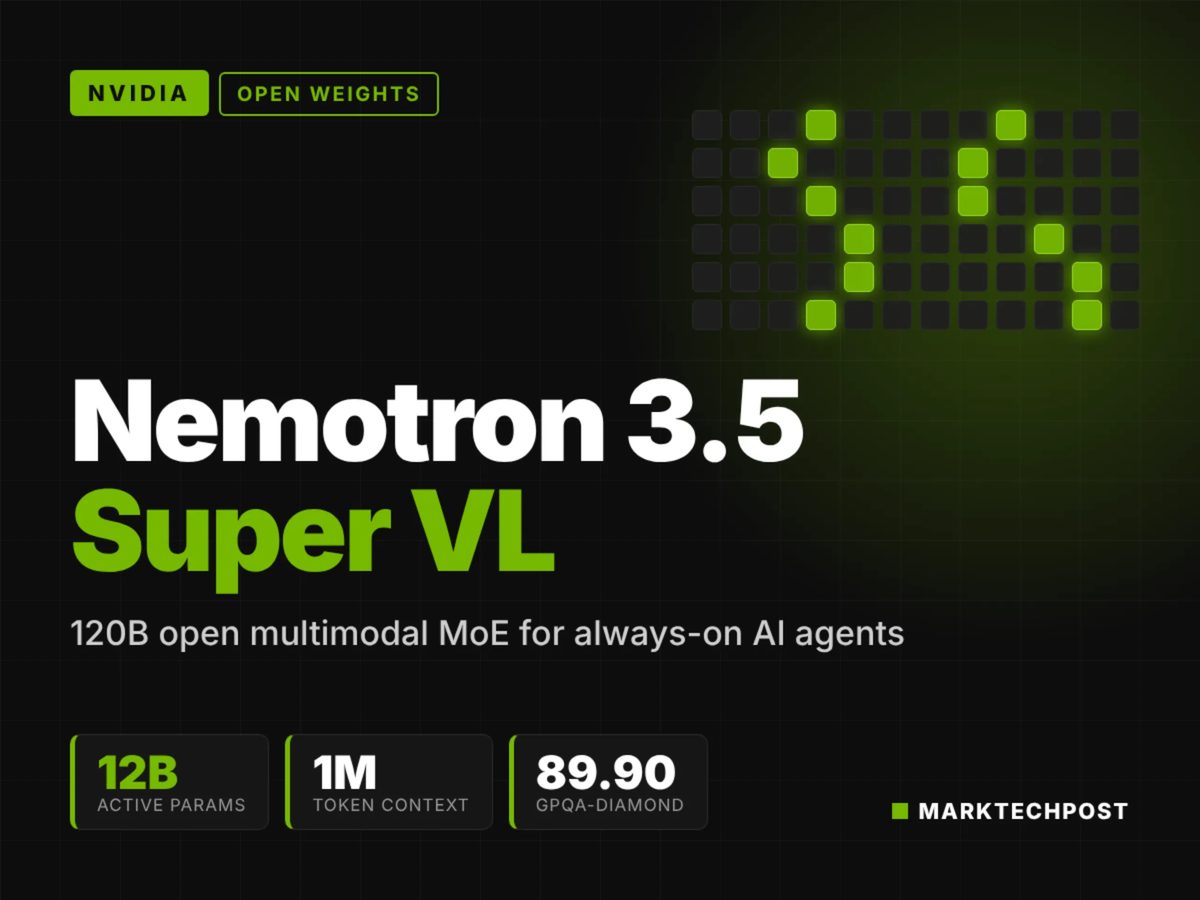
NVIDIA has launched Nemotron 3.5 Super VL, an open 120-billion-parameter vision-language model tailored for always-on enterprise agents. The model activates 12 billion parameters per token using an architecture that interleaves Mamba-2, mixture-of-experts, and attention layers to handle text, image, document, and video inputs in a single checkpoint.
According to NVIDIA, Super VL outperforms its larger predecessor, Nemotron 3 Ultra, across key agent benchmarks, scoring 63.44% on Hermes Bench and 87.05% on LangChain evaluations. The company also released open datasets, training recipes, and reinforcement learning environments in NeMo Gym alongside two smaller edge models under the OpenMDW-1.1 license.
The model is available on Hugging Face, OpenRouter, ModelScope, and as an NVIDIA NIM, supported by vLLM, SGLang, and TensorRT-LLM runtimes on Hopper and Blackwell hardware. NVIDIA reports that production deployments using Dynamo recipes can deliver up to 8x higher user capacity on B200 GPU setups.
Why it matters
Consolidates text and vision capabilities into a single open model, simplifying agent deployment architectures.
Reduces infrastructure overhead with high throughput and low first-token latency on modern GPU hardware.
Provides open datasets and RL environments to help teams fine-tune custom enterprise agents.
Source: marktechpost.com