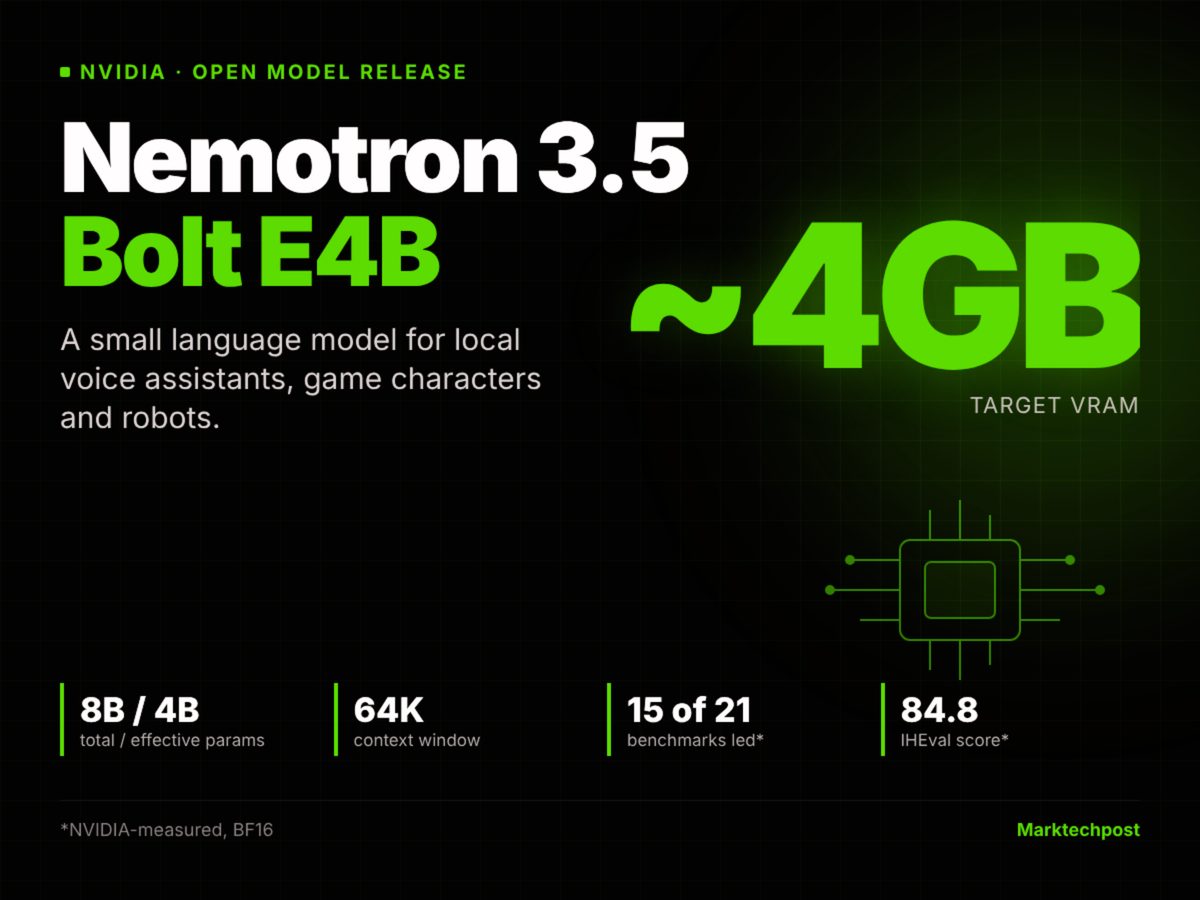
NVIDIA has launched Nemotron 3.5 Bolt E4B 4GB, an open small language model designed for fast, local conversational agents. Post-trained exclusively via reinforcement learning (RLVR and RLHF) from Google’s Gemma 4 E4B, the model targets low-resource hardware like RTX, Jetson, and Spark. Skipping supervised fine-tuning allowed the team to preserve dialogue quality while improving tool calling.
The model operates within a 4GB VRAM envelope, leaving operational headroom on edge devices for concurrent vision and audio models. In hardware demonstrations, NVIDIA showcased the model driving speech and tool invocation on a Jetson Orin Nano alongside vision models. To achieve real-time performance, the checkpoint was quantized to Q4_K_M using importance-matrix calibration and paired with a spec-decoding drafter, delivering up to 272.6 tokens per second on an RTX 5070.
While the model outperforms predecessors like Nemotron 3 Nano 4B and leads in specific multi-turn benchmarks, competitive open models such as Qwen3.5-4B still maintain advantages in long-context and specific agent benchmarks. Bolt is available immediately across open repositories, Ollama, LM Studio, and as an NVIDIA NIM.
Why it matters
Enables local execution of complex conversational and tool-calling agents alongside vision models within consumer-grade 4GB VRAM envelopes.
Demonstrates that pure reinforcement learning post-training without SFT can yield superior multi-turn tool calling without degrading conversational fluency.
Provides optimized deployment pathways for edge AI, robotics, and game NPCs via llama.cpp, Ollama, and NVIDIA NIM integration.
Source: marktechpost.com