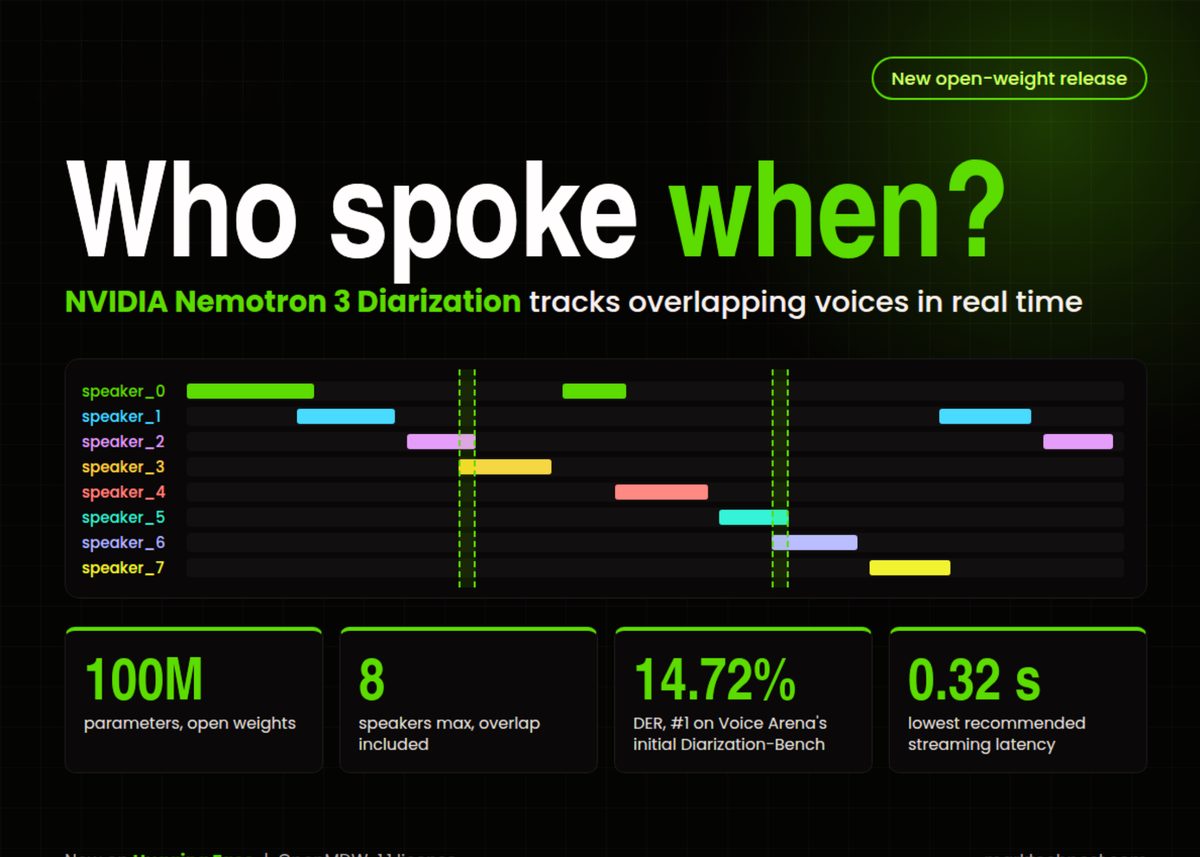
NVIDIA has released Nemotron 3 Diarization, an open-weight, 100-million-parameter speaker diarization model available on Hugging Face under the commercially permissive OpenMDW License 1.1. The model determines speaker attribution for multi-party audio, doubling the capacity of NVIDIA’s previous 4-speaker checkpoint to track up to 8 simultaneous or overlapping voices in real time.
Built on a 31-layer Transformer encoder architecture with rotary positional embeddings, the model processes single-channel audio into Mel-spectrogram features and uses an Arrival-Order Speaker Cache to maintain stable speaker labels across streaming chunks. In benchmark evaluations on Voice Arena’s Diarization-Bench, the system secured first place out of 12 candidate systems with a 14.72% Diarization Error Rate (DER) and demonstrated execution throughput up to 15,113× real-time factor on compatible Linux GPU setups.
The deployment provides developer infrastructure for applications requiring precise speech attribution, including meeting transcription, call center analytics, podcast processing, and conversational agent memory. By releasing open weights compatible with its NeMo framework, NVIDIA further expands its open-source toolchain for enterprise speech processing.
Why it matters
Provides developers with a commercially usable, open-weight model for accurate multi-speaker real-time transcription.
Doubles real-time speaker tracking capacity while delivering significant throughput gains on standard Linux GPU hardware.
Enhances essential pre-processing pipelines for enterprise voice agents, call analytics, and meeting summarization tools.
Source: marktechpost.com