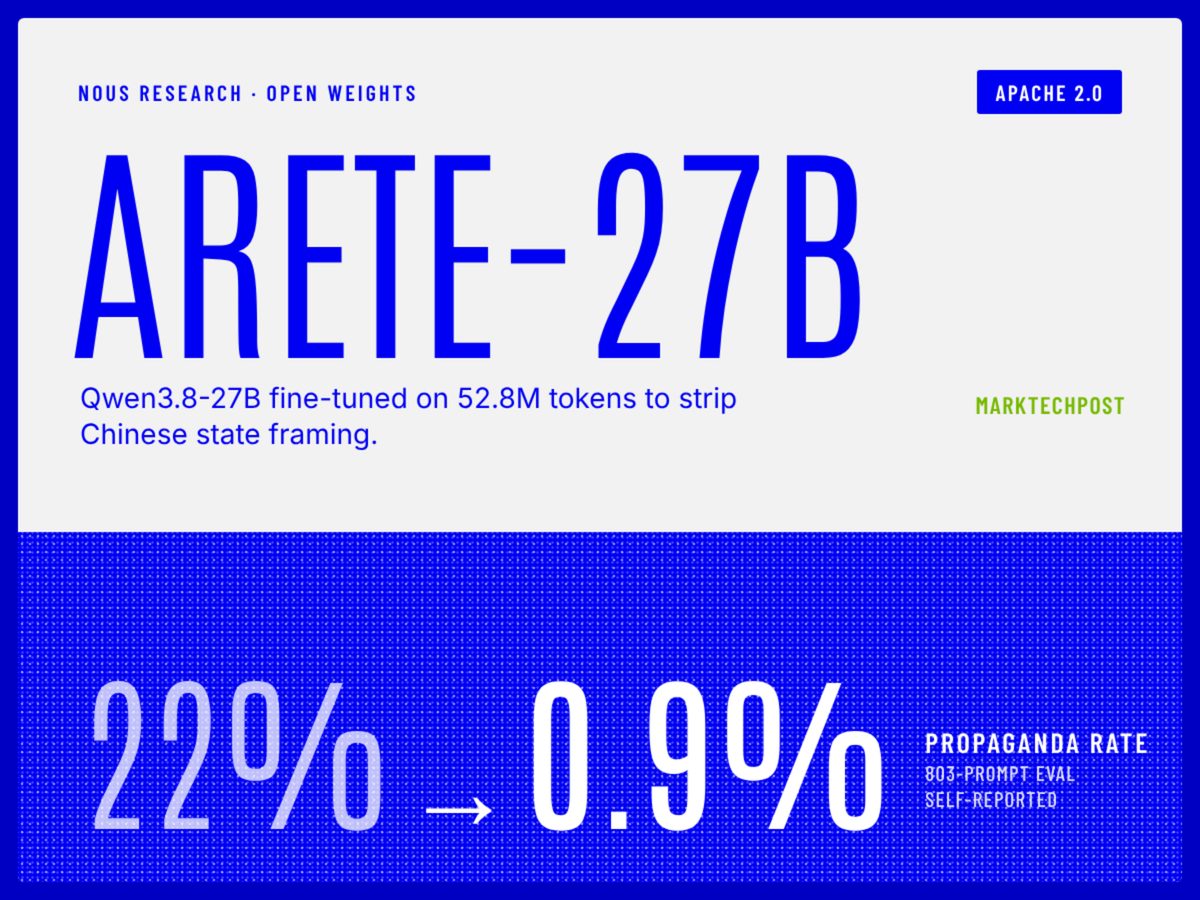
Nous Research has released Arete-27B, an open-weight supervised fine-tune of Alibaba’s Qwen3.8-27B model designed to strip out state-aligned political framing and refusals. Tested on Nous’s 803-prompt evaluation set, the proportion of answers containing Chinese state propaganda dropped from 22 percent in the base model to 0.9 percent in Arete-27B, while maintaining core agentic capabilities.
The fine-tuning process relied entirely on supervised dataset pairs generated by Thinking Machines’ open model Inkling, explicitly avoiding proprietary teacher models to bypass commercial distillation restrictions. Training ran across approximately 52.8 million tokens without architectural modifications or reinforcement learning, leaving the base model’s vision encoder intact.
Arete-27B and its training data are available under an Apache 2.0 license on Hugging Face in BF16 format alongside community GGUF quantizations. Benchmark results showed preserved baseline performance on Hermes Bench and a slight improvement on Terminal-Bench-2.1.
Why it matters
Delivers a sanitized, open-weight alternative to Chinese base models without sacrificing benchmarked reasoning capability.
Provides open-source evaluation sets and datasets for measuring and removing political bias in open LLMs.
Enables local deployment via GGUF format for enterprise privacy and compliance requirements.
Source: marktechpost.com