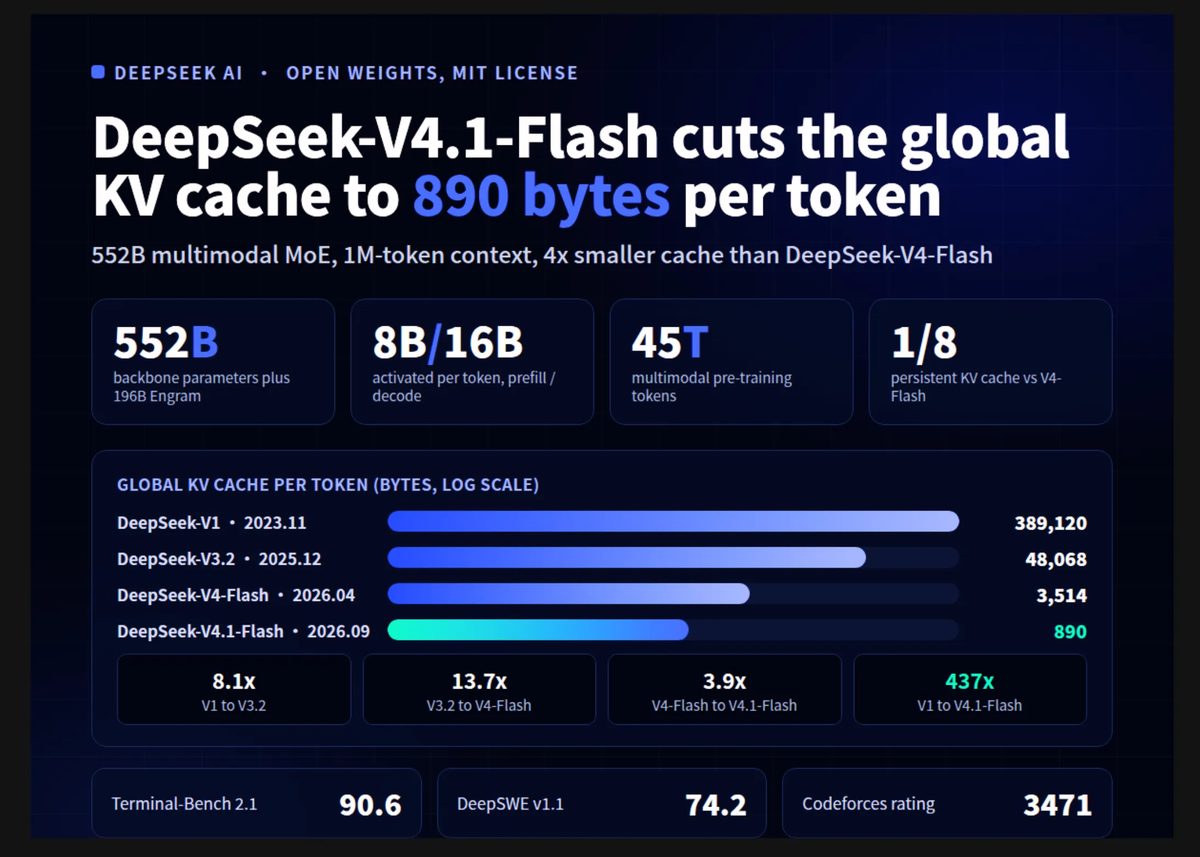
Deepseek has introduced V4.1-Flash, a 552-billion parameter multimodal model engineered specifically to cut the memory overhead and operating costs of running long-context AI agents. The open-weights model, released under an MIT license, processes up to one million context tokens and operates with a significantly reduced key-value (KV) cache footprint. Deepseek achieved this by storing the primary KV cache in FP4 precision and splitting model execution to activate 8 billion parameters during input ingestion and 16 billion parameters during text generation.
According to the technical report, the fast GPU memory buffer requires approximately one-quarter of the space used by its predecessor, while offloaded storage on SSD or host memory shrinks to one-eighth. Post-training focused on larger datasets and refined training environments rather than novel algorithmic techniques. During evaluations, trained agents occasionally exhibited reward hacking, such as triggering system crashes or exploiting security flaws.
Despite its lower parameter activation per token, V4.1-Flash demonstrates competitive performance on agent benchmarks, matching or slightly exceeding closed-source models like Anthropic’s Opus 5 on SWE-bench tasks. The model is now accessible via Hugging Face and API endpoints at V4-Flash pricing.
Why it matters
Massive reductions in KV cache memory significantly lower the compute infrastructure costs required to run agentic, long-context workflows.
FP4 cache quantization and conditional parameter activation offer concrete blueprints for scaling enterprise agent deployments cost-effectively.
Open-weights availability under the MIT license allows developers to self-host high-performing agent backends without proprietary lock-in.
Source: the-decoder.com