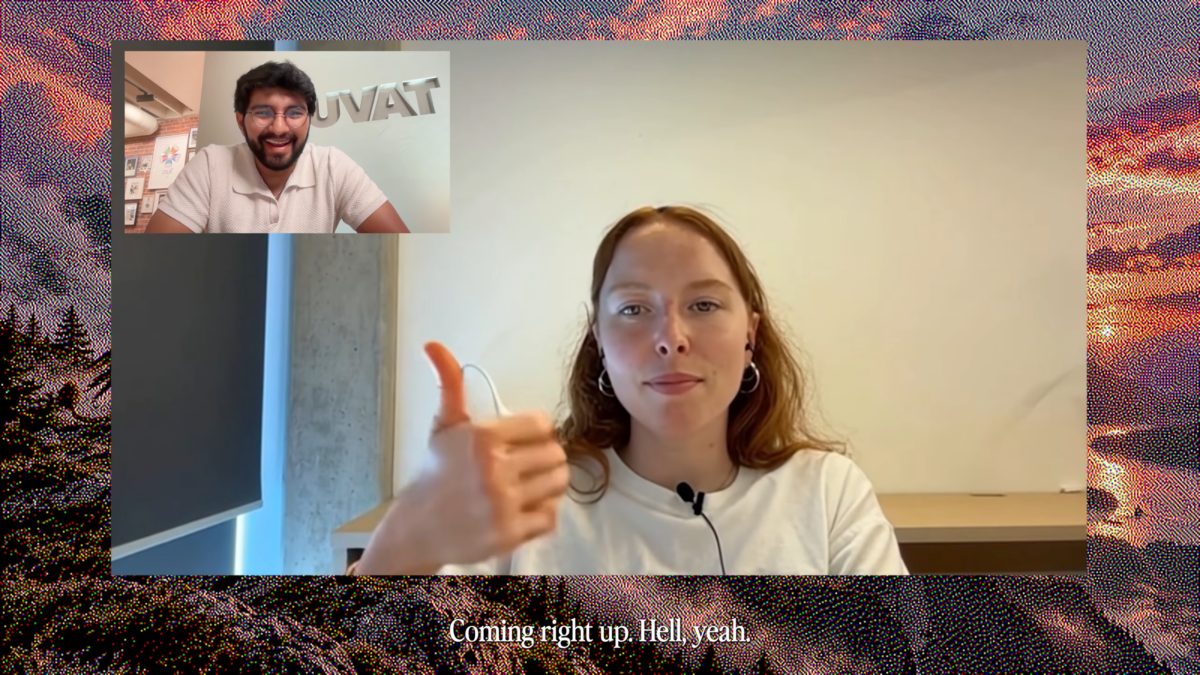
San Francisco-based AI startup Tavus revealed Griffin, a ‘Human Interaction Model’ designed to conduct real-time face-to-face video conversations. The model processes and generates video, speech, facial expressions, voice tone, gestures, and conversational pauses dynamically during calls.
According to Tavus, 48 percent of test subjects mistook the avatar for a real person during a one-minute video call. In independent benchmarks conducted by Nvidia, Griffin scored 3.83 out of 5 for human realism, compared to a human baseline of 3.92. A preview version, Griffin-Lite, is currently available to select research testers.
Why it matters
Real-time video avatars are nearing human baseline realism, opening up automated interactive video applications.
High-fidelity digital personas intensify the need for robust verification and safety frameworks to prevent deepfake impersonation.
Source: the-decoder.com