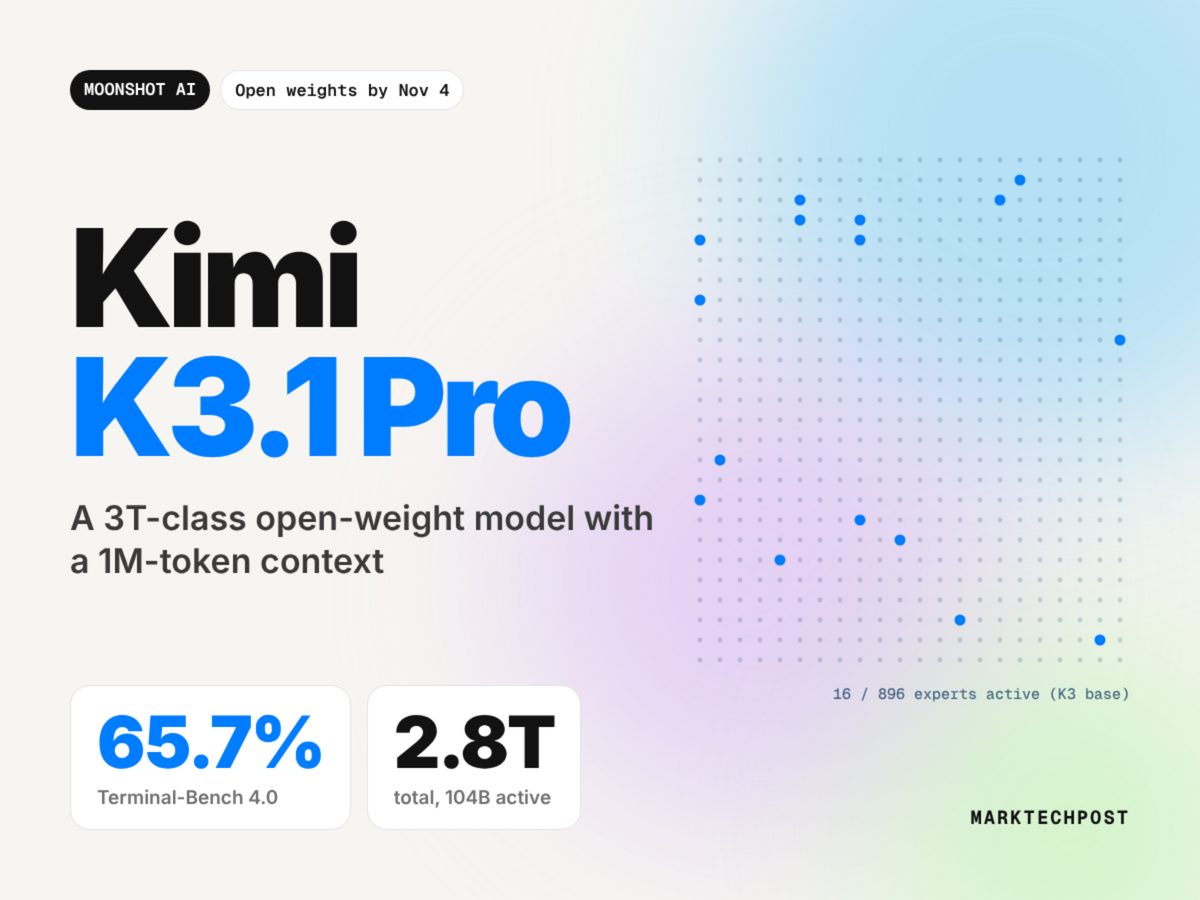
Moonshot AI has unveiled Kimi K3.1 Pro, the latest model in its K3.1 series featuring 2.8 trillion total parameters with 104 billion active parameters across 896 experts. The Mixture-of-Experts model supports a 1-million-token context window and handles text, image, and video inputs. It relies on a post-training scale-up using joint reinforcement learning across hundreds of downstream domains.
The base architecture utilizes Kimi Delta Attention and Attention Residuals, activating 16 experts per pass. Moonshot also introduced a high-speed API variant capable of 2x to 3x faster inference. According to internal benchmarks, the company reported strong performance across coding and reasoning harnesses, though it noted cyber-related dataset exclusions intentionally reduced offensive capabilities prior to planned open-weight availability.
The model is currently accessible via Moonshot’s web products and an OpenAI-compatible API priced at $2.00 input and $10.00 output per million tokens. Open weights for the model are scheduled for release in November 2026.
Why it matters
Offers lower API pricing ($2/$10 per million tokens) for a 1M-context MoE model compared to preceding versions.
Provides a upcoming high-parameter open-weight candidate for developers requiring deep context and agentic performance.
Demonstrates the scaling of reinforcement learning during post-training to boost performance in specialized coding and agentic environments.
Source: marktechpost.com