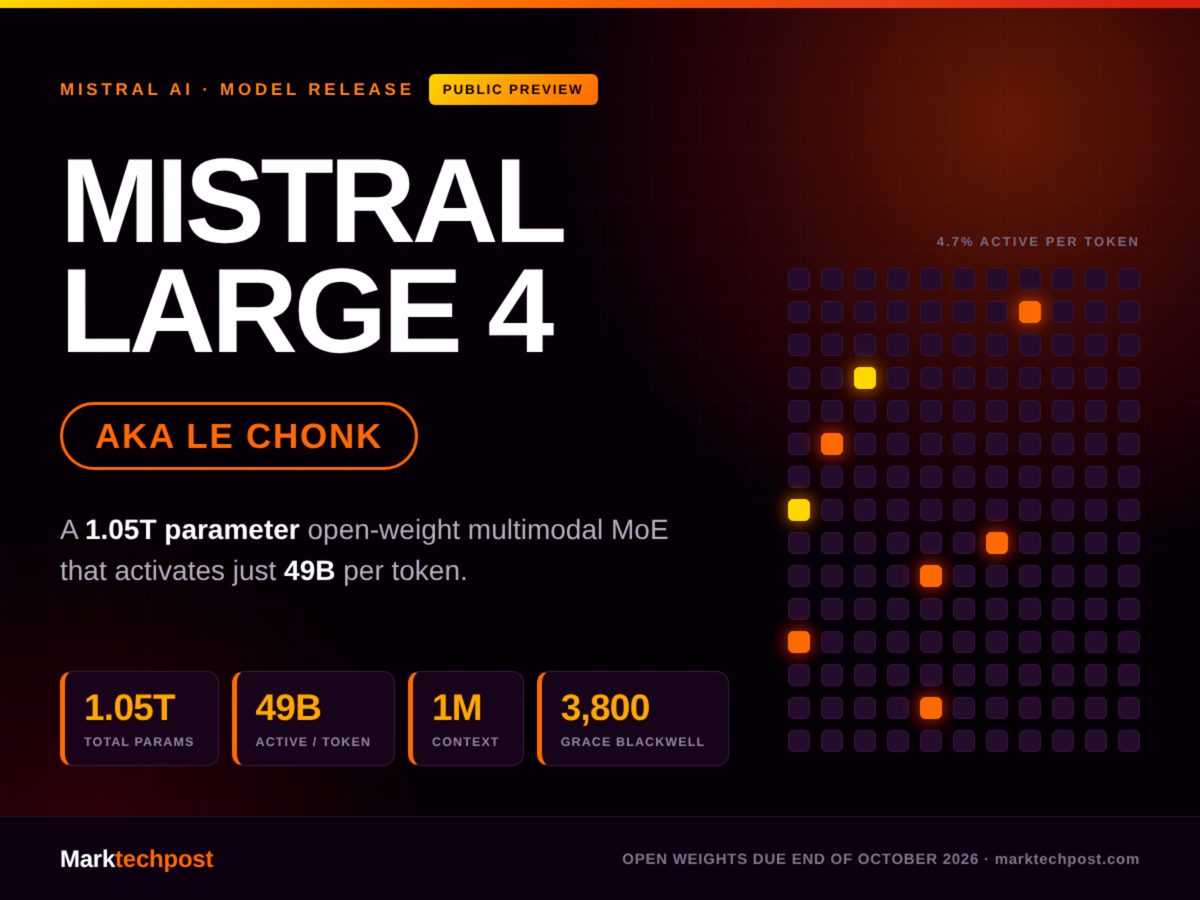
Mistral AI has released a public preview of Mistral Large 4 (ML4), internally codenamed “Le Chonk.” The model features a granular Mixture of Experts (MoE) architecture with 1.05 trillion total parameters, activating 49 billion parameters per token. It integrates a 1.6 billion parameter native vision encoder, supports over 160 languages, and offers a 1 million token context window. Trained on 3,800 NVIDIA Grace Blackwell GPUs in European datacenters, the preview API is available now, with public weights scheduled for release in late October 2026.
The model demonstrates strong capabilities in specialized evaluations, notably scoring 93% on Cybench and 82% on CyberGym-E2E for cybersecurity tasks. Mistral attributes these scores to reduced task refusal on standard defensive security workflows relative to competing proprietary models. On coding benchmarks, ML4 recorded an Artificial Analysis Coding Agent Index of 49.8%, while private human evaluations by Surge AI scored the model 3.74 out of 5, placing it behind Claude Opus 5.
ML4 is available via API priced at $1.36 per 1 million input tokens and $4.18 per 1 million output tokens, with cached inputs priced at $0.14 per million tokens. The API supports structured outputs, function calling, document Q&A, and conversational endpoints, offering favorable economics for long-context agentic operations.
Why it matters
Offers highly competitive API pricing and low cached-context rates, making 1M-token agent loops economically viable for enterprises.
Delivers top-tier cybersecurity benchmark performance by allowing legitimate defensive security workflows without triggering over-broad safety refusals.
Upcoming open-weights release in late October provides a path for full on-premise deployment of trillion-parameter class models.
Source: marktechpost.com