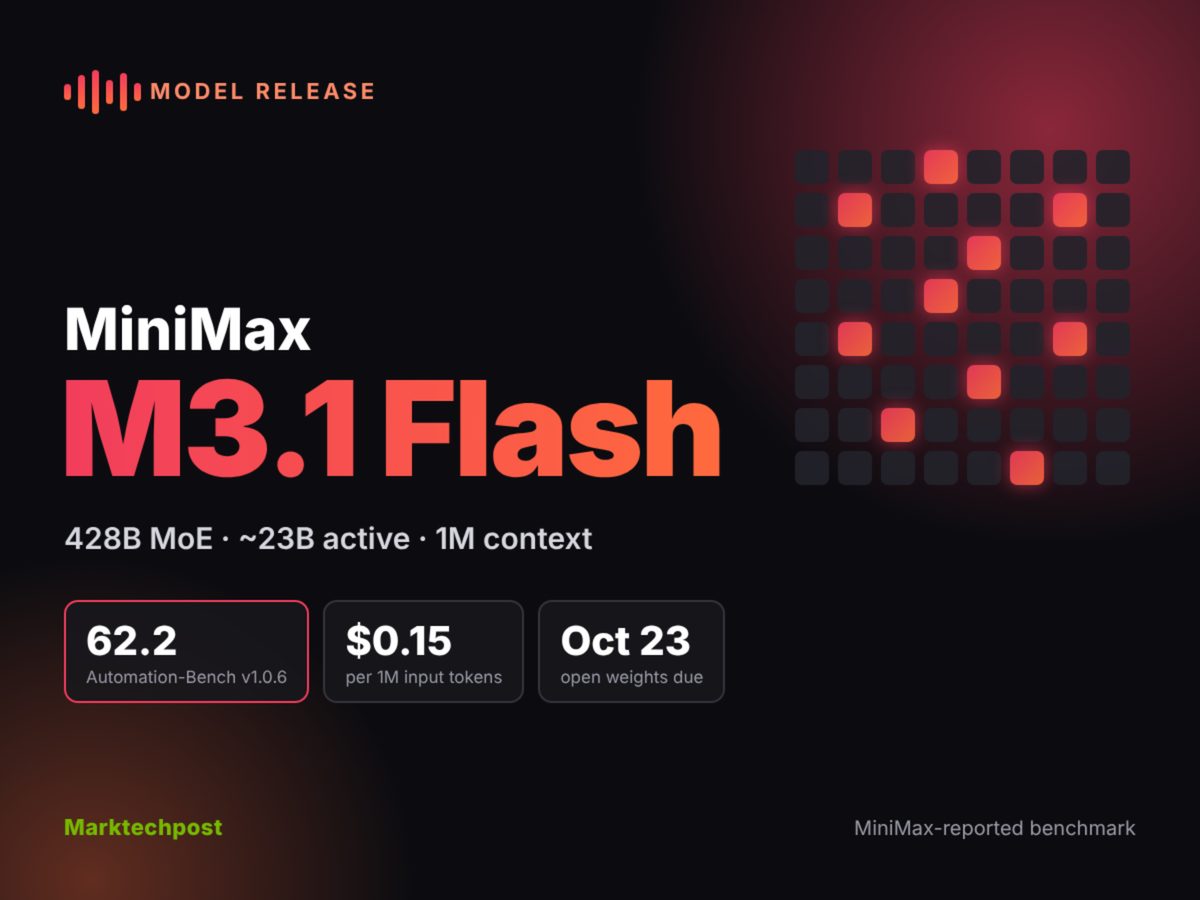
MiniMax launched MiniMax M3.1 Flash on its developer API, featuring a 428 billion parameter Mixture-of-Experts (MoE) architecture with roughly 23 billion active parameters per token. Priced at $0.15 per million input tokens, the multimodal model supports text, image, and video inputs with a 1 million token context window. MiniMax confirmed that an unbranded stealth model previously tested across 200 trillion tokens ran on an earlier build of this system.
The model features mandatory built-in reasoning with five configurable effort levels, targeting automated coding, enterprise office workflows, and visual reasoning tasks. Vendor-reported benchmark scores place M3.1 Flash near frontier performance on agentic task suites like Automation-Bench. Open-weights for the 428B parameter model are slated for release in late October 2026.
Why it matters
API cost reductions for high-parameter MoE models lower the financial barrier for running high-volume agentic workflows.
Integrated reasoning and multimodal inputs are becoming standard features in low-cost, high-throughput inference models.
Upcoming open-weight releases of massive models allow infrastructure teams to self-host competitive agentic backends.
Source: marktechpost.com