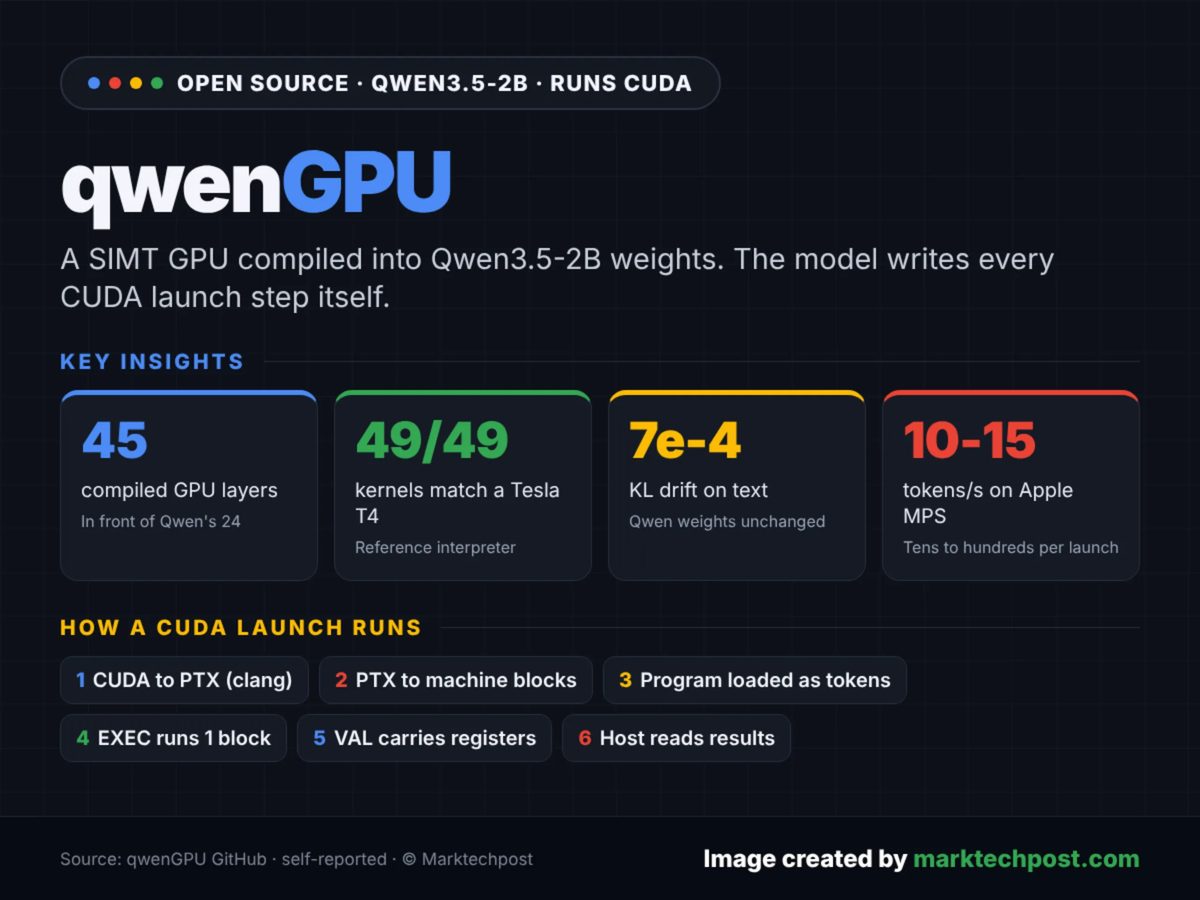
Independent developer Vixhal has released qwenGPU, an experimental project that compiles a SIMT GPU architecture directly into the transformer weights of Qwen3.5-2B. Published under the MIT license on GitHub, the setup inserts 45 compiled transformer layers into the base model to execute CUDA code natively during model forward passes.
The compiled virtual GPU functions as a 4-lane SIMT execution engine featuring registers, memory state, and instruction processing constructed using Qwen3.5’s native Gated DeltaNet attention and SwiGLU MLP layers. The host system compiles input CUDA code to PTX using LLVM/Clang and feeds instruction tokens directly into the model, which resolves execution and returns state updates without external host computing.
According to the repository, the added execution layers do not alter the base model’s standard language generation weights, keeping text output distribution nearly unchanged. The release relies on transformer compiler techniques to demonstrate deterministic mathematical execution within neural network architecture.
Why it matters
Demonstrates advanced architectural techniques for executing deterministic, stateful code directly inside transformer neural networks.
Provides developers with open-source reference implementations for embedding custom virtual execution environments inside open-weight LLMs.
Highlights ongoing innovation in hybrid neural-symbolic execution pipelines using open-source models.
Source: marktechpost.com