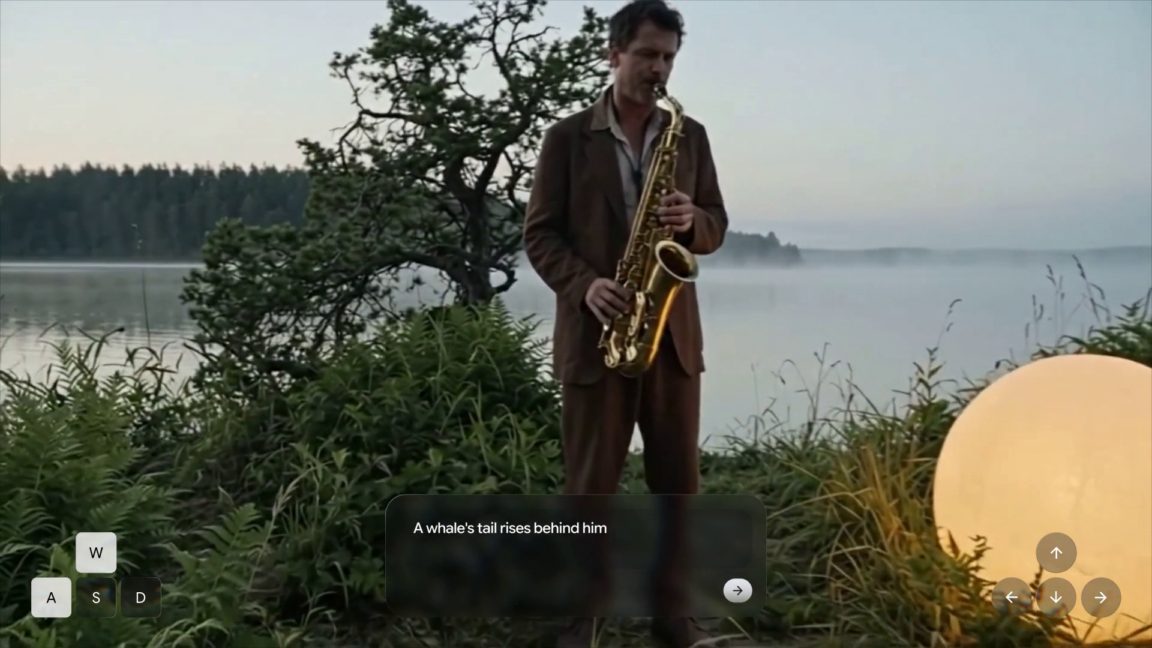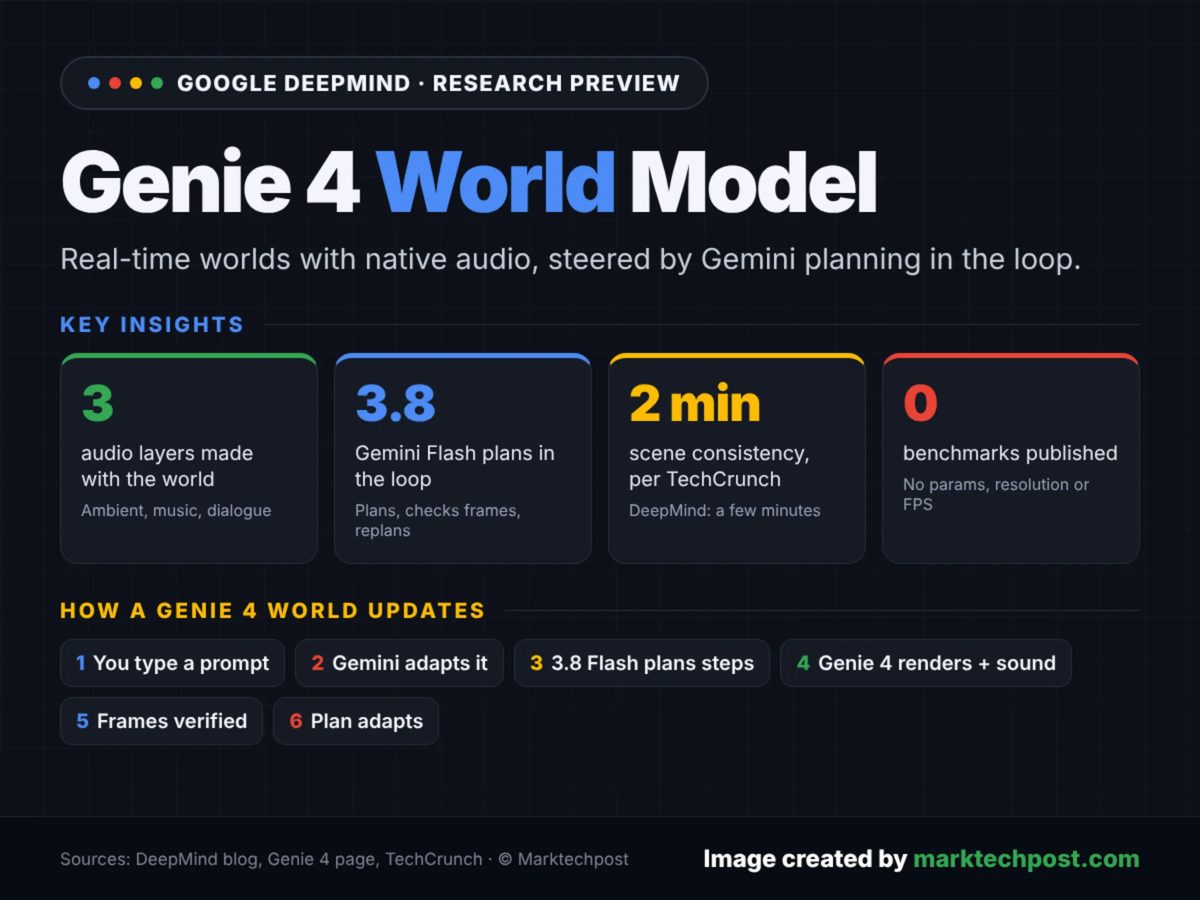
Google DeepMind has released Genie 4 as a research preview for trusted testers, marking its first real-time world model capable of natively generating audio alongside visuals. Moving beyond static video generation, Genie 4 continuously simulates interactive environments frame by frame based on user controls and natural language prompts, generating dynamic soundscapes, character dialogue, and music.
Architecturally, Genie 4 integrates a Gemini model inside its simulation loop to act as a high-level planner, maintaining structural and narrative consistency as scenes progress. The system relies on Gemini Omni for visual rendering while leveraging other Gemini models for spatial and logical reasoning, establishing a hybrid framework that bridges language models and spatial rendering engines.
Genie 4 is currently accessible to selected research testers and is slated for upcoming availability to Google AI Ultra subscribers within Project Genie, followed by early-access partners on the Gemini API and Google AI Studio. All generated media content includes SynthID watermarking, and DeepMind noted that internal safety evaluations were completed prior to the preview.
Why it matters
Offers a real-time, audio-visual simulation environment that can serve as a training ground for autonomous agents and robotics.
Introduces a hybrid architecture coupling language models for high-level planning directly with generative rendering loops.
Expands creative and gaming possibilities by enabling interactive, prompt-steerable worlds with natively synchronized dialogue and audio.
Source: marktechpost.com