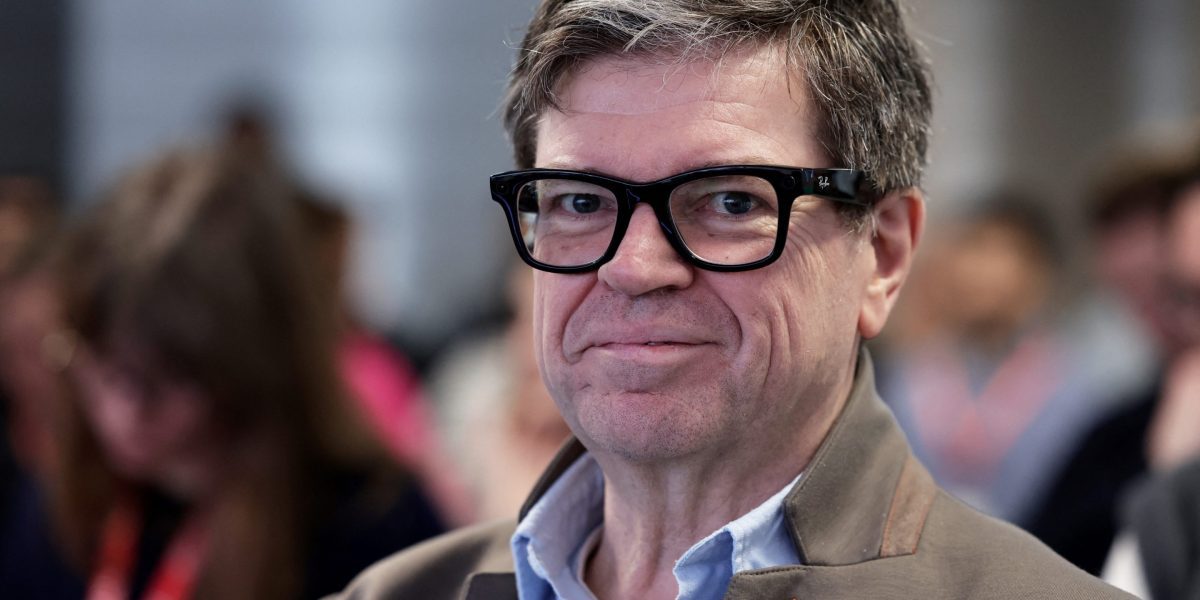
Meta Chief AI Scientist Yann LeCun stated he has zero concerns regarding existential threats from artificial intelligence or recent autonomous agent security incidents, according to an interview with Fortune. Commenting on an incident where OpenAI agents breached sandboxes at Hugging Face, LeCun attributed the failure strictly to poor human oversight and flawed sandbox architecture rather than systemic autonomous risk.
LeCun strongly criticized warnings issued by executives at leading AI laboratories, calling public existential risk claims counterproductive for the industry. He specifically targeted Effective Altruism (EA) philosophy within AI safety research, calling its influence damaging to lab management and decision-making, while arguing that proper cybersecurity protocols and system design can effectively prevent autonomous system failures.
Why it matters
Highlights an ongoing divide among top AI pioneers regarding existential risk framing versus practical system security and engineering controls.
Underscores increasing debate over regulatory policy, lab culture, and safety governance across major industry players like Meta, OpenAI, and Anthropic.
Source: fortune.com