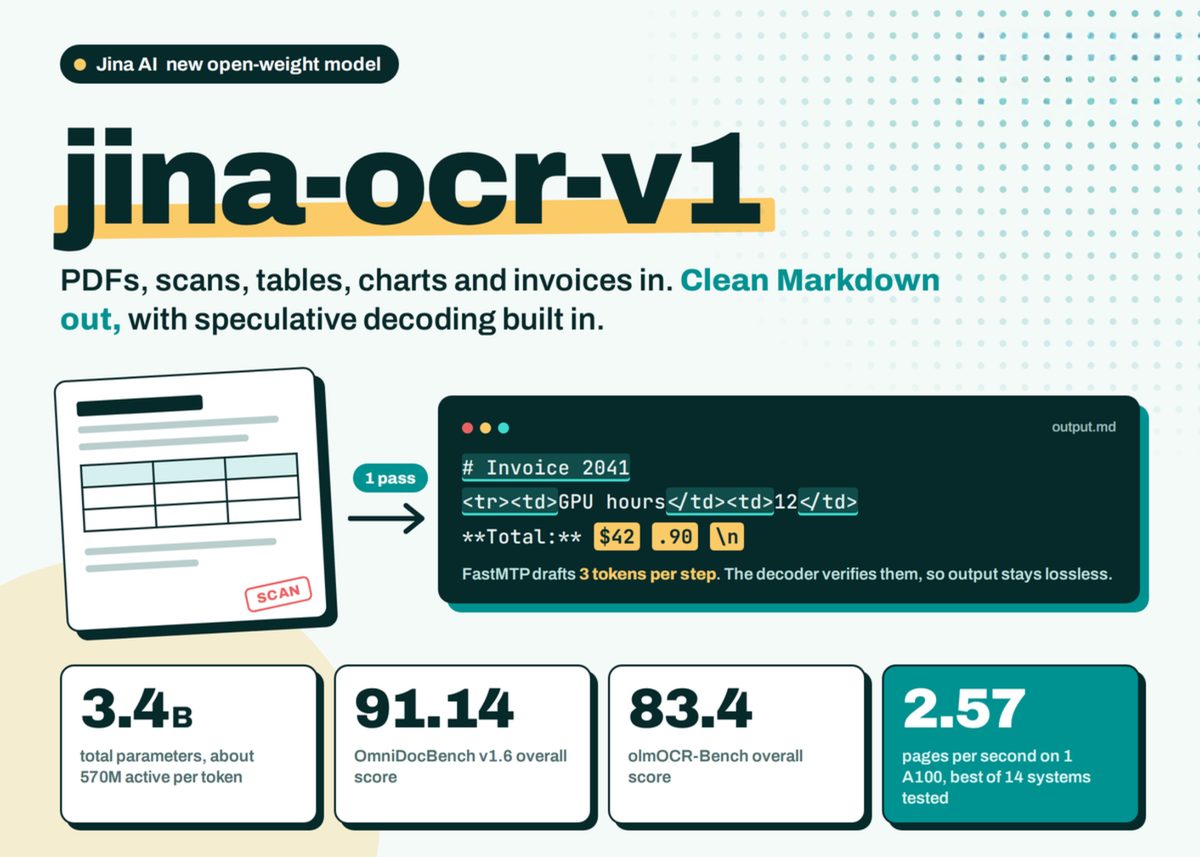
Jina AI, a subsidiary of Elastic, released jina-ocr-v1, a 3.4-billion parameter Mixture-of-Experts (MoE) visual document parser. The model converts PDFs, scans, tables, and invoices directly into clean Markdown in a single pass. Designed for deployment on low-budget GPUs like the NVIDIA L4, it activates approximately 570 million decoder parameters per token and features an integrated speculative decoding head to maximize processing efficiency.
The model post-trains DeepSeek-OCR and utilizes a DeepEncoder combined with a DeepSeek-3B-MoE decoder. On an NVIDIA A100 GPU, jina-ocr-v1 achieves a throughput of 2.57 pages per second at concurrency 32, outperforming competing models in speed while keeping output token counts low. On an NVIDIA L4, its processing speed increases from 42.7 to 83.1 tokens per second with speculative decoding.
Open weights (6.8 GB in BF16) are available under a CC BY-NC 4.0 license for research and non-commercial use, requiring commercial entities to contact Jina AI. While the model achieves strong benchmark scores, including 91.14 on OmniDocBench v1.6, its core advantage lies in throughput and low-resource hardware deployment rather than top-tier accuracy.
Why it matters
Enables cost-effective, high-throughput document parsing on lower-tier enterprise GPU infrastructure like the NVIDIA L4.
Demonstrates practical gains from combining Mixture-of-Experts architectures with speculative decoding for specialized tasks.
Source: marktechpost.com