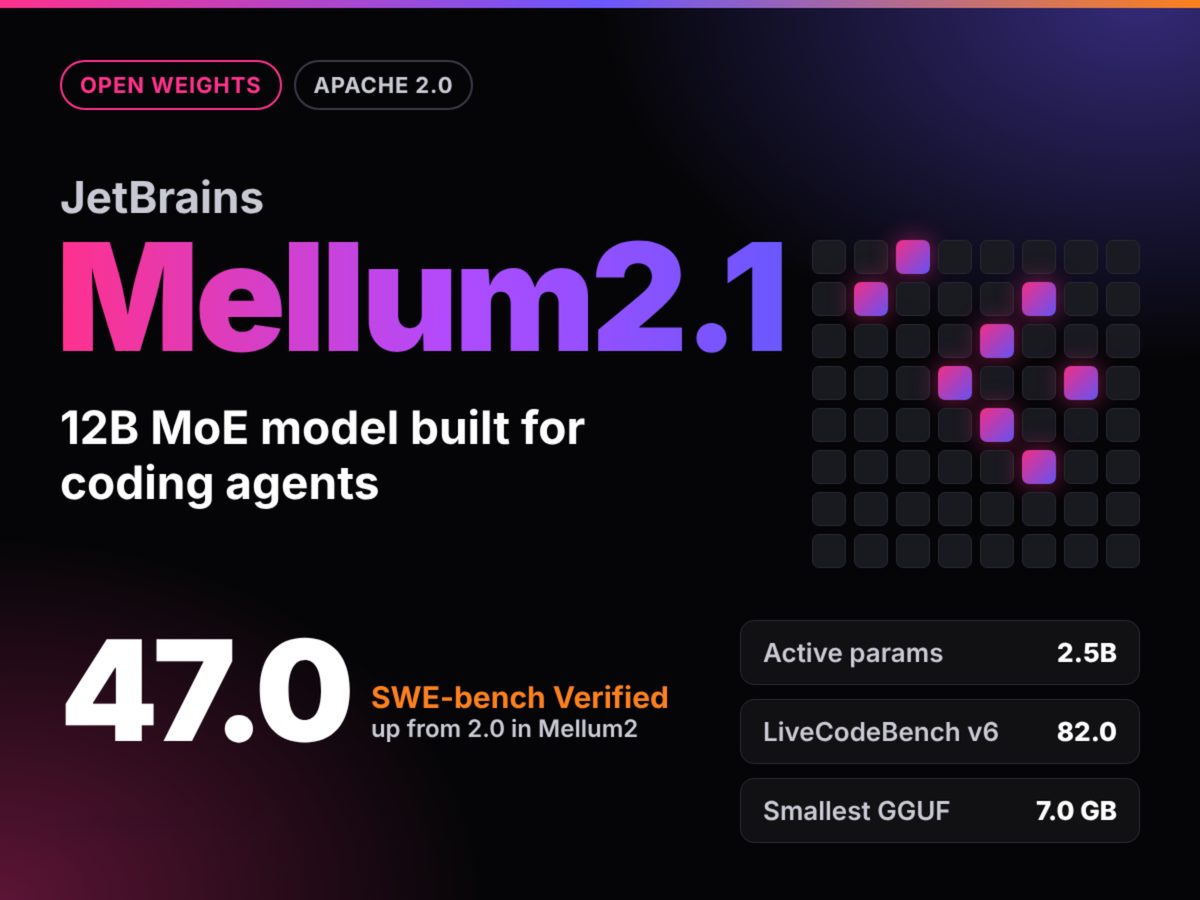
JetBrains has released Mellum2.1, an open 12B mixture-of-experts (MoE) reasoning model optimized for coding agents and fast sub-agents. Available under the Apache 2.0 license on Hugging Face, the model activates 2.5B parameters per token and features a 131,072-token context window. While its architecture remains unchanged from Mellum2, JetBrains significantly improved post-training performance by shifting reinforcement learning to the primary training stage across millions of sandboxed repository environments.
Evaluation benchmarks provided by JetBrains indicate substantial performance gains in agentic coding tasks. The model’s score on SWE-bench Verified rose from 2.0 to 47.0, and LiveCodeBench v6 reached 82.0. On single H200 GPUs, JetBrains claims Mellum2.1 serves almost twice the tokens of Qwen3.5-9B under heavy load, aided by multi-token prediction heads for speculative decoding.
JetBrains positions the model for three primary use cases: agent workers, general reasoning assistants, and private self-hosted deployments. Serving integrations support vLLM, with GGUF quantizations actively in development for broader local hardware deployment.
Why it matters
Offers engineering teams an Apache 2.0 open-weights 12B MoE model capable of running repo-level coding agents locally or on-premise.
Demonstrates significant SWE-bench improvements purely through RL in real software environments without architectural changes.
Provides high-throughput inference efficiency, serving nearly 2x the tokens of Qwen3.5-9B on single H200 GPUs under load.
Source: marktechpost.com