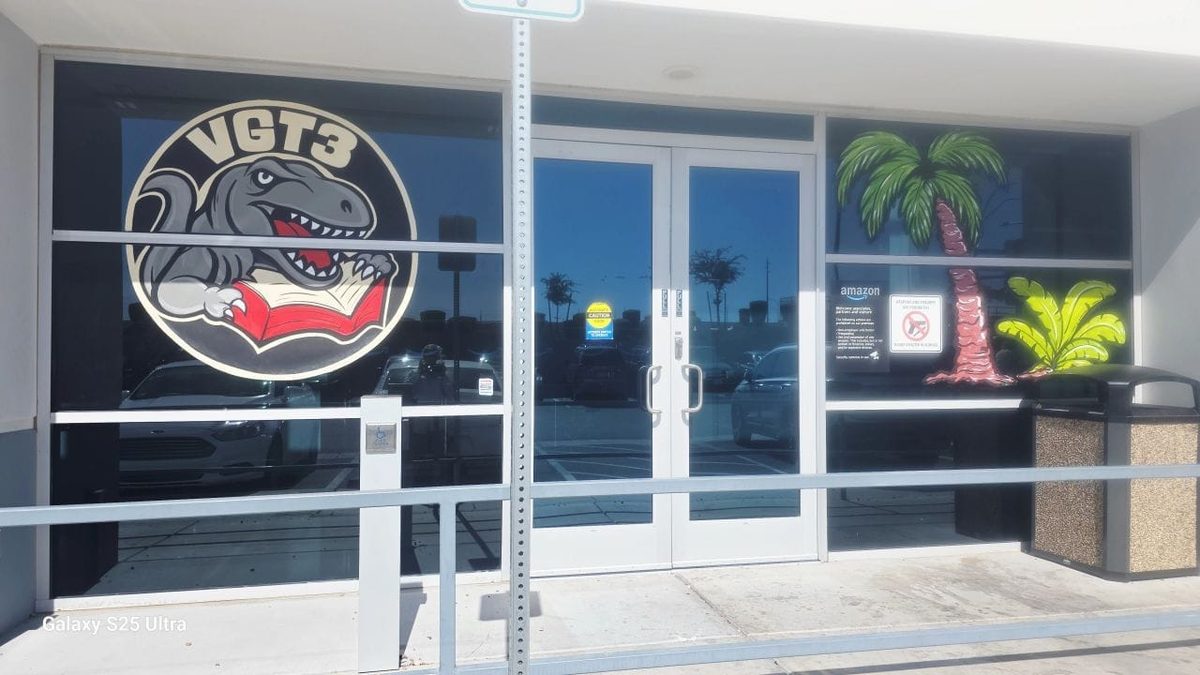
An investigation into Amazon’s operations has revealed that the company is actively scanning and destroying thousands of physical books at a Las Vegas warehouse facility to generate AI training data. An interview with an anonymous warehouse worker at facility VGT3 detailed how workers process bulk shipments of new, used, public, and foreign-language books by slicing off their bindings and scanning individual pages.
According to the employee, the facility receives diverse print materials ranging from liquidated library stock and imported Japanese books to historical British parliamentary documents. Once scanned, the loose pages are discarded into large cardboard shuttles, permanently destroying the original texts. The facility shares location space with Amazon’s LAS8 facility, which handles print-on-demand operations.
The practice highlights the expanding efforts of major tech companies to secure novel, non-web datasets to train advanced language models. By physically digitizing offline print collections, Amazon can acquire clean, copyrighted, and hard-to-find text to expand its data resources as web data scraping faces increasing legal and technical restrictions.
Why it matters
Reveals physical data pipeline tactics used by tech giants to source offline training data for proprietary LLMs.
Underscores growing copyright and legal scrutiny surrounding commercial dataset acquisition and physical book digitization.
Highlights how data scarcity is driving companies to spend capital on manual hardware scanning operations.
Source: 404media.co