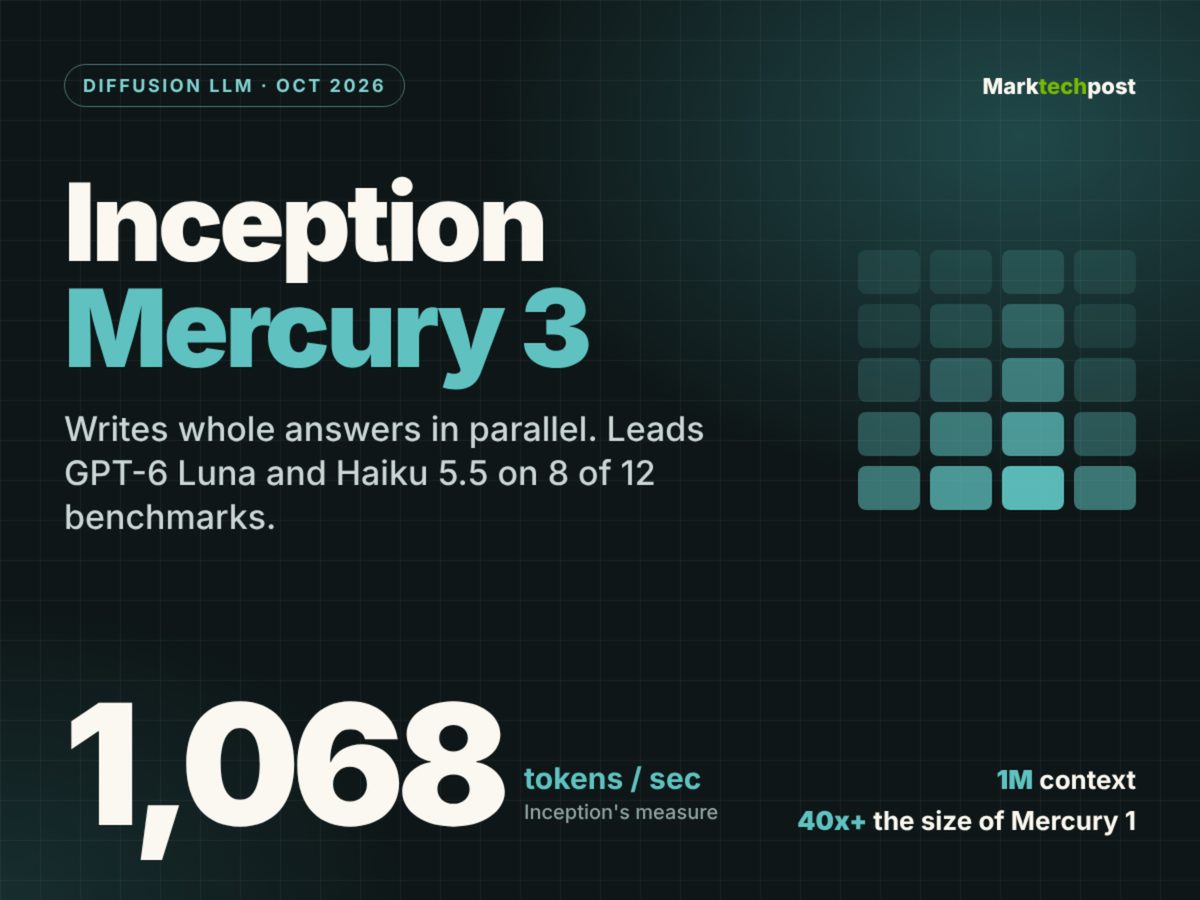
AI startup Inception has officially released Mercury 3, the latest iteration of its diffusion language model architecture. Operating by refining drafts in parallel rather than generating text token-by-token, the model achieves output speeds of 1,068 tokens per second on Nvidia GPUs while supporting a 1M-token context window.
According to Inception’s self-reported benchmark comparisons, Mercury 3 leads rival models like GPT-6 Luna and Claude Haiku 5.5 on 8 out of 12 standard tests. The model demonstrates its strongest performance in agentic coding and instruction following, though it lags slightly behind competitors on long-context retrieval and specific software engineering tasks.
The model is available immediately via Inception’s API platform, OpenRouter, Baseten, and Vercel with OpenAI-compatible endpoints. Standard pricing is set at $0.20 per 1M input tokens and $0.70 per 1M output tokens, with launch discounts offering 50% off.
Why it matters
Offers high-speed, parallelized output critical for real-time AI agents, voice applications, and search tools.
Validates diffusion-based text generation as a scalable alternative to traditional autoregressive LLMs.
Provides competitive API pricing and standard OpenAI compatibility for fast developer adoption.
Source: marktechpost.com