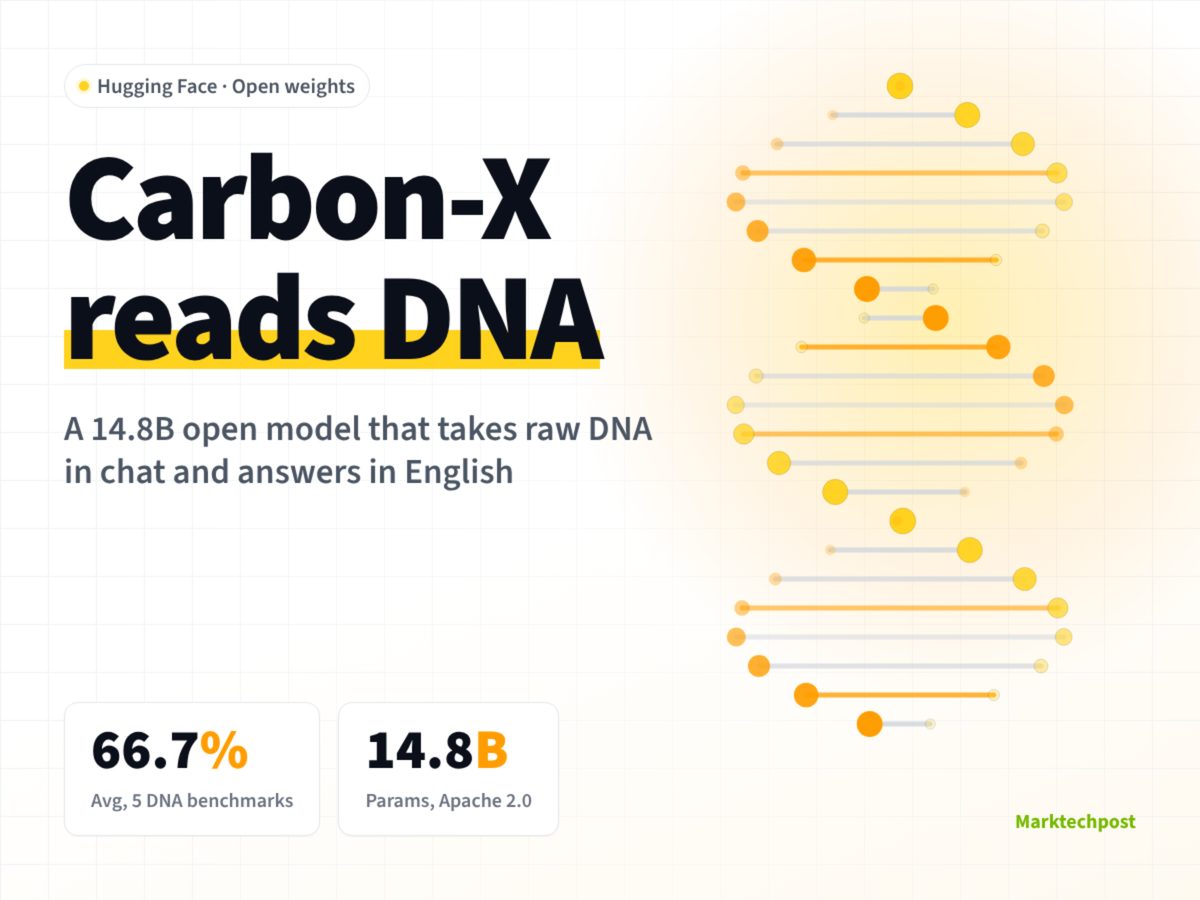
Hugging Face has launched Carbon-X, an open 14.8-billion parameter DNA language model built under an Apache 2.0 license. Developed alongside Zhongguancun Academy and TIGEM/University of Naples Federico II, the decoder-only architecture adapts Qwen3-14B by incorporating a hybrid tokenizer that adds 5,515 DNA tokens directly into Qwen3’s byte-pair encoding vocabulary. This unified token stream allows the model to process raw DNA sequences and output natural English without relying on a separate DNA encoder.
In benchmark evaluations, Carbon-X performed near frontier capabilities on biological tasks, scoring 27 points above its Qwen3-14B base and just 0.8 points below GPT-6.1 Sol on genomic benchmarks. It demonstrated particular strength in predicting coding-variant effects and next-base sequences while maintaining standard text abilities, such as a 79.3% accuracy on IFEval.
By operating at an estimated $5 per hour on an H200 GPU, Hugging Face claims Carbon-X delivers roughly 1/1,800th the inference cost of GPT-6.1 Sol for genomic tasks. The release offers laboratories an open-weights, low-cost alternative for analyzing sensitive genetic sequences locally.
Why it matters
Enables open-source, low-cost genomic AI processing on local GPUs, reducing dependence on expensive proprietary frontier API calls.
Introduces a single-stream architecture combining DNA and natural language, simplifying multimodal bio-AI pipelines for developers.
Provides small labs and startups affordable diagnostic sequence analysis, drastically reducing variant classification costs.
Source: marktechpost.com