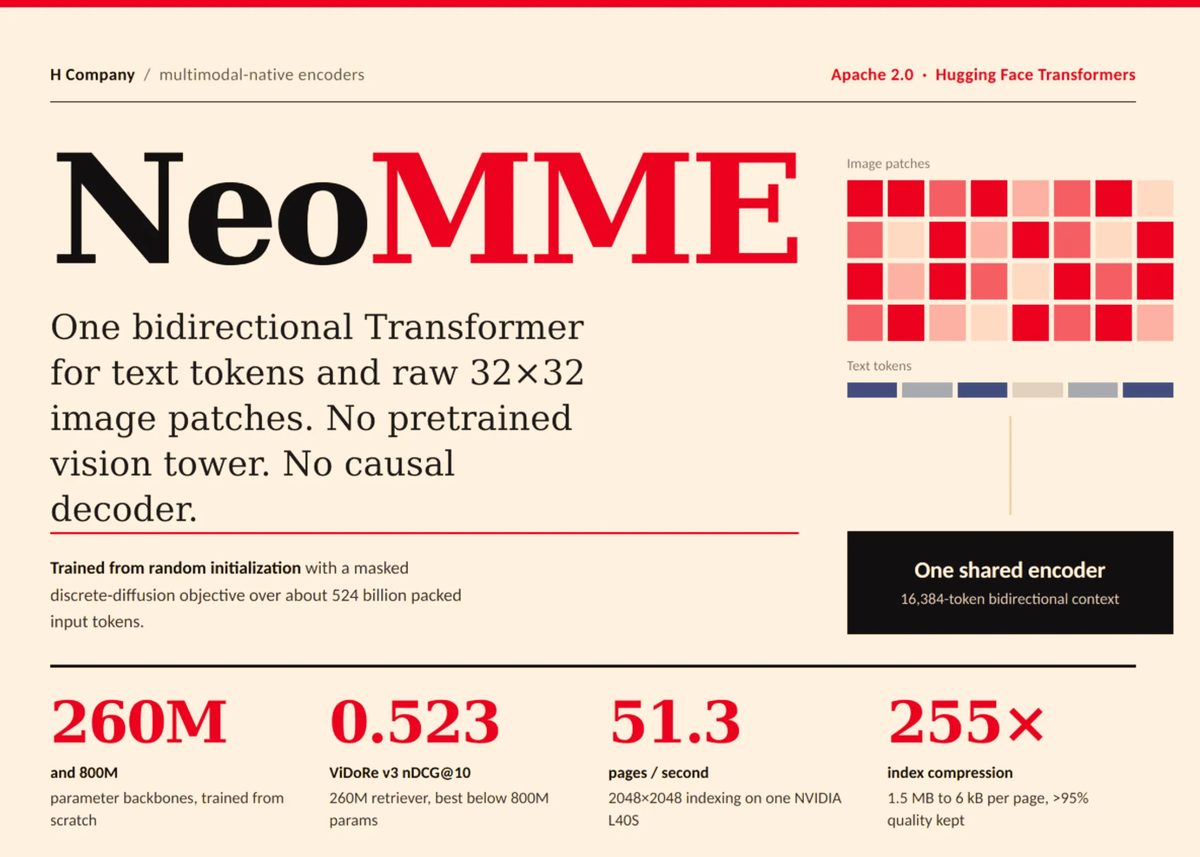
H Company has launched NeoMME, an open-source family of 260M and 800M parameter bidirectional multimodal encoders. Released under the Apache 2.0 license, the architecture processes text and raw 32x32 image patches directly through a single unified Transformer, eliminating the need for a separate vision tower or causal decoder. The models are immediately available on Hugging Face Transformers with explicit optimization for retrieval tasks.
By dropping the traditional decoupled components, NeoMME significantly reduces computational overhead. The 260M variant can process 51.3 pages per second on an NVIDIA L40S GPU and encode query inputs on CPU hosts in under 80 milliseconds. Pre-trained on discrete masked diffusion over 524 billion tokens, the models demonstrated strong cross-modal page processing capabilities during testing.
On the visual document retrieval benchmark ViDoRe v3, the 260M model achieved a score of 0.523 nDCG@10, matching significantly larger multi-billion parameter models. While text-only retrieval showed lower relative accuracy due to dataset supervision limits, the architecture introduces efficient hierarchical pooling techniques to manage dense index storage overhead.
Why it matters
Single-tower architecture significantly reduces compute requirements for visual document search, enabling fast CPU-based inference.
Apache 2.0 licensing provides cost-effective alternatives to heavy generative models for enterprise document retrieval pipelines.
Source: marktechpost.com