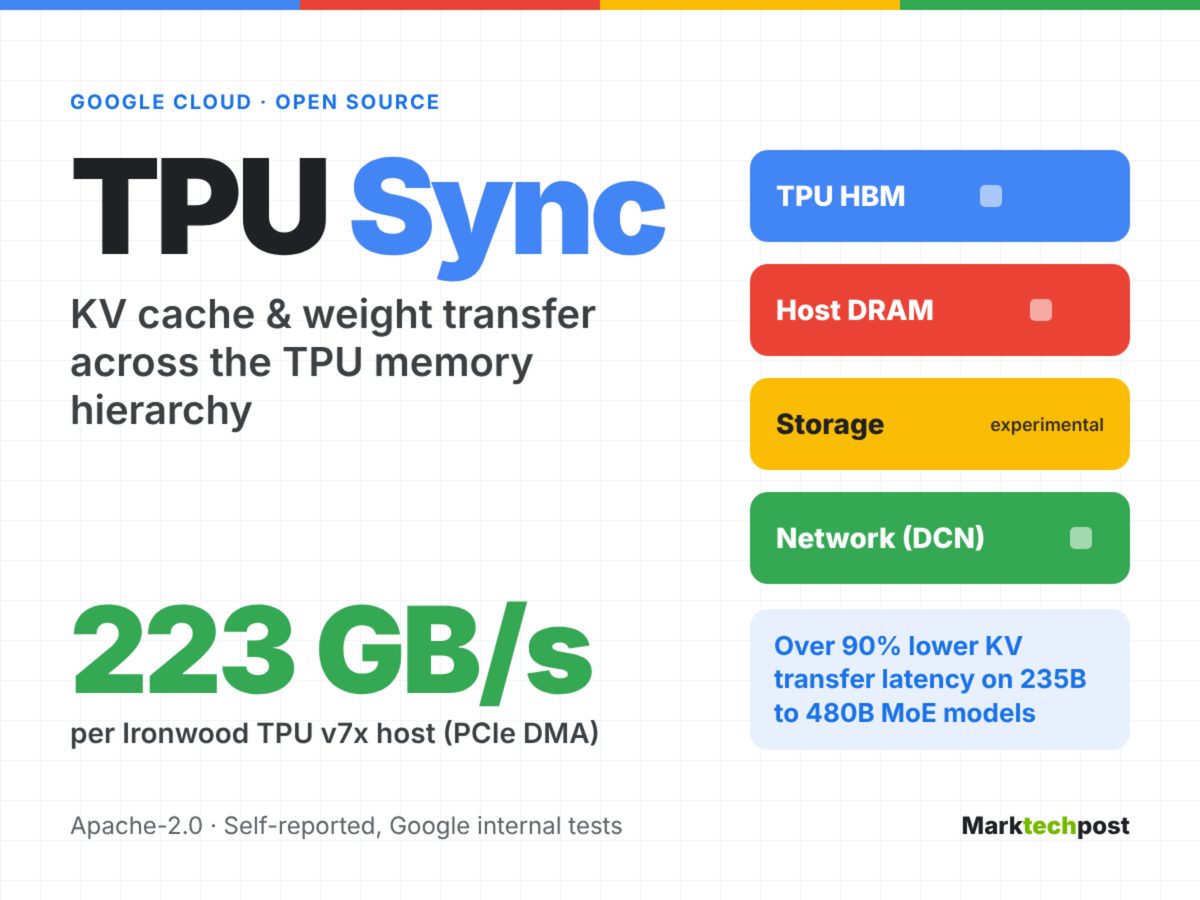
Google Cloud has released TPU Sync, an open-source C++ library under the Apache-2.0 license designed to accelerate memory state transfers across Cloud TPUs. The library manages key-value (KV) cache state during LLM inference and weight broadcasting for reinforcement learning, addressing data movement bottlenecks across TPU memory, host DRAM, and data center networks.
According to Google, TPU Sync achieved over 90% lower KV transfer latency on Mixture-of-Experts (MoE) models ranging from 235 billion to 480 billion parameters during internal benchmarks. The system coordinates tensor movement using asynchronous direct memory access (DMA), integrating with storage backends including Cloud Managed Lustre.
The library natively supports PyTorch via TorchTPU and JAX, featuring direct integrations with open-source serving frameworks vLLM and SGLang. Google noted that enterprise organizations including Meta and Wayfair are currently evaluating the architecture for production scaling.
Why it matters
Reduces distributed inference bottlenecks for large MoE models by optimizing off-chip memory and network transfers.
Provides open-source primitives for engineering teams scaling inference workloads on Google Cloud TPU infrastructure.
Enhances performance parity for open-source frameworks like vLLM and SGLang running on non-GPU acceleration hardware.
Source: marktechpost.com