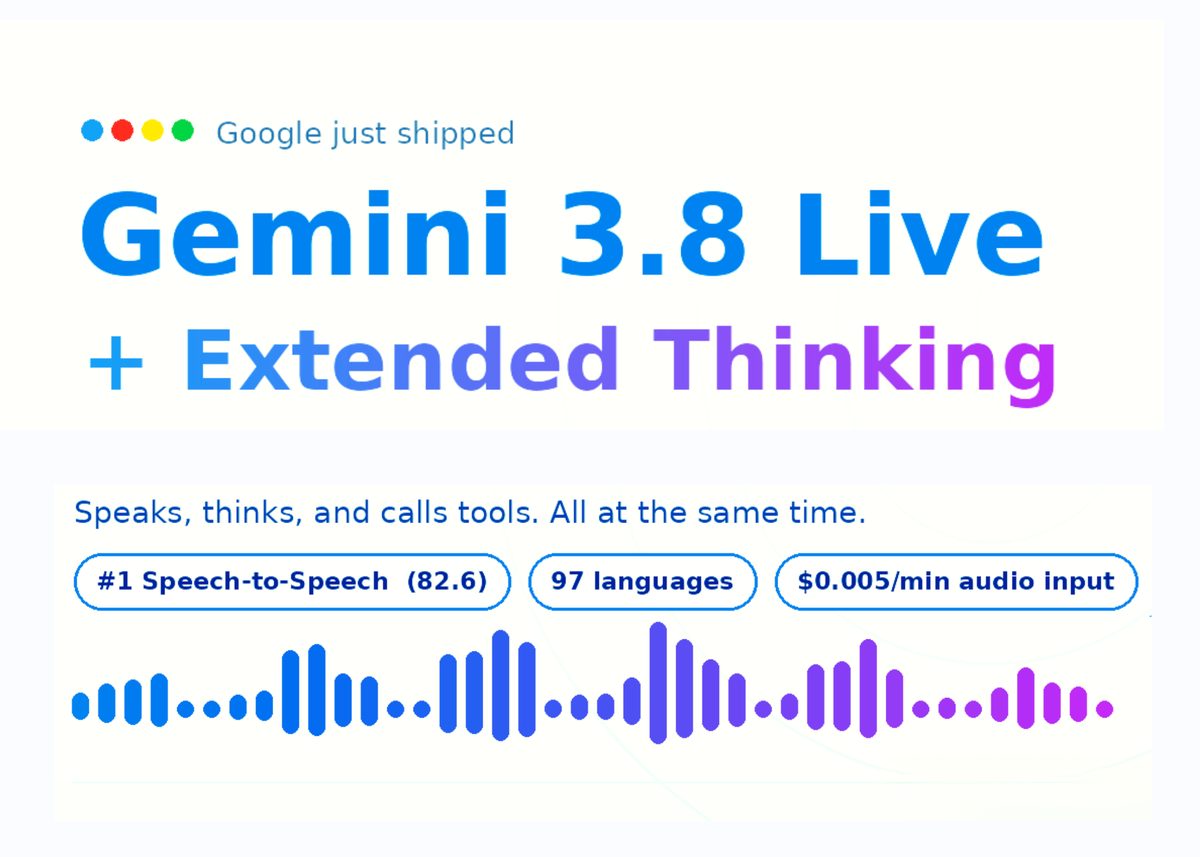
Google has announced Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking, two native speech-to-speech models designed for real-time voice applications. Available via the Gemini Live API and Google AI Studio, the hosted models aim to eliminate latency and integration friction associated with traditional cascaded voice stacks that connect separate speech recognition, language, and text-to-speech models.
The flagship Gemini 3.8 Live Extended Thinking model scored 82.6 on Artificial Analysis’ Speech to Speech Quality Index and reached 68.6% on the τ-Voice agent benchmark. The model handles multi-step reasoning while simultaneously conversing, using audio prompts like “Let me check that” to maintain flow while executing tasks such as background tool integration, sketch parsing, and dynamic scheduling.
Google has priced both models at $0.005 per minute for audio input and $0.018 per minute for audio output, based on standard token pricing. Google is partnering with real-time streaming platforms like LiveKit, Agora, and Vercel, alongside enterprise software vendors including Salesforce, to support deployment across corporate workflows.
Why it matters
Developers can eliminate complex ASR-LLM-TTS chains using single-latency native speech-to-speech APIs.
Voice agent startups can build complex, tool-calling enterprise workflows with background reasoning capabilities.
Competitive audio API pricing ($0.005/min input) accelerates the commercial viability of real-time conversational applications.
Source: marktechpost.com