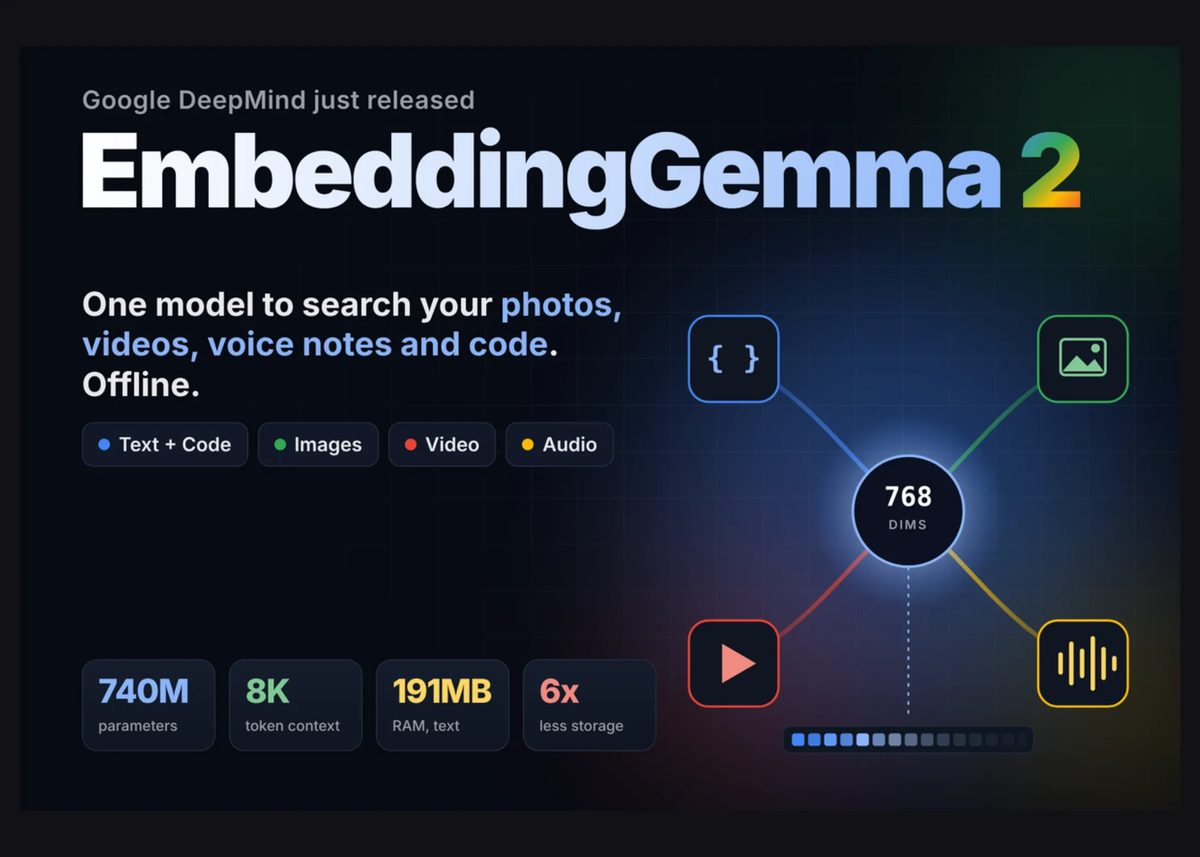
Google DeepMind has launched EmbeddingGemma 2, an open-weights multimodal embedding model with up to 740 million parameters under an Apache 2.0 license. Built on the Gemma 4 architecture, the model maps text, code, images, video, and audio into a unified 768-dimensional vector space. It is designed specifically for on-device applications, including local search, classification, and privacy-preserving Retrieval-Augmented Generation (RAG) pipelines.
The model features a modular design that allows developers to load only the parameter weights required for specific modalities, ranging from a 270M text-only variant to the full 740M multimodal configuration. Utilizing Matryoshka Representation Learning (MRL), the 768-dimensional vectors can be truncated to 512, 256, or 128 dimensions to optimize storage and compute footprint. Quantization-aware training enables execution with active RAM footprints as low as 191MB on mobile hardware.
According to Google DeepMind, EmbeddingGemma 2 achieves top benchmark results among sub-1B multimodal embedders on MTEB Code and MAEB benchmarks. Weights and runtimes are currently live across open platforms, including Hugging Face, Kaggle, Ollama, llama.cpp, vLLM, and LiteRT, with ML Kit support for Android coming soon.
Why it matters
Enables ultra-low-latency, privacy-first local search and RAG applications directly on edge hardware with minimal RAM overhead.
Modular architecture lets developers optimize mobile memory footprints by loading only necessary modality modules without breaking vector space compatibility.
Apache 2.0 open-weights release gives developers a fully accessible, zero-cost alternative to proprietary multimodal embedding APIs.
Source: marktechpost.com