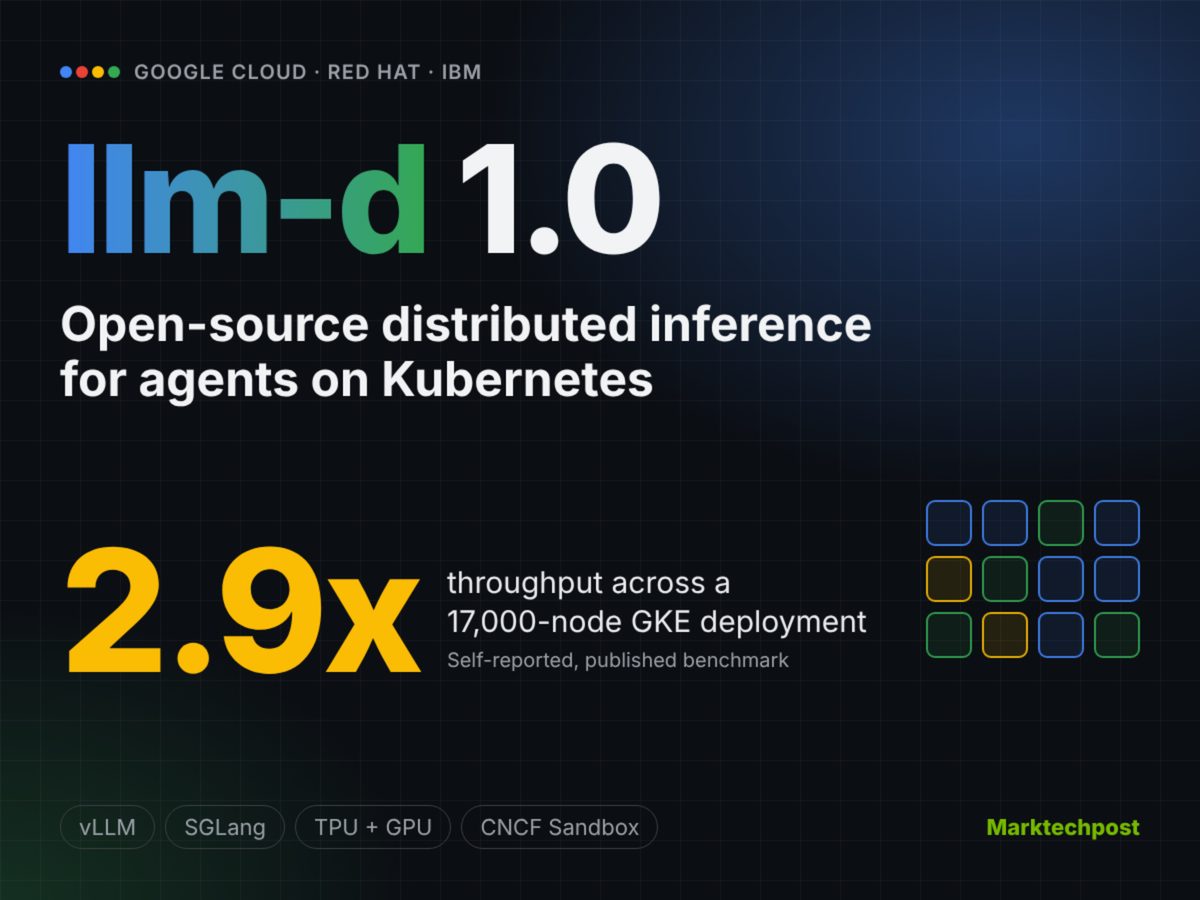
Google Cloud, IBM, Red Hat, CoreWeave, and NVIDIA released version 1.0 of llm-d, an open-source distributed inference stack for Kubernetes. Originally launched in 2025 and accepted as a CNCF Sandbox project, llm-d coordinates vLLM and SGLang servers into unified compute pools designed for high-concurrency agent and reinforcement learning workloads.
Version 1.0 focuses on production operations, featuring cache-aware routing based on the Kubernetes Gateway API Inference Extension, tiered KV cache offloading, and disaggregated prefill and decode execution pools. Google Cloud announced it is offering the llm-d router as a managed service via the GKE Inference Gateway to support multi-cluster deployment and autoscaling.
Why it matters
Enables AI operators to maximize GPU/TPU utilization and reduce inference latency for multi-step agent workloads via prefix caching.
Establishes a vendor-neutral CNCF open-source standard for running large-scale LLM inference on Kubernetes.
Source: marktechpost.com