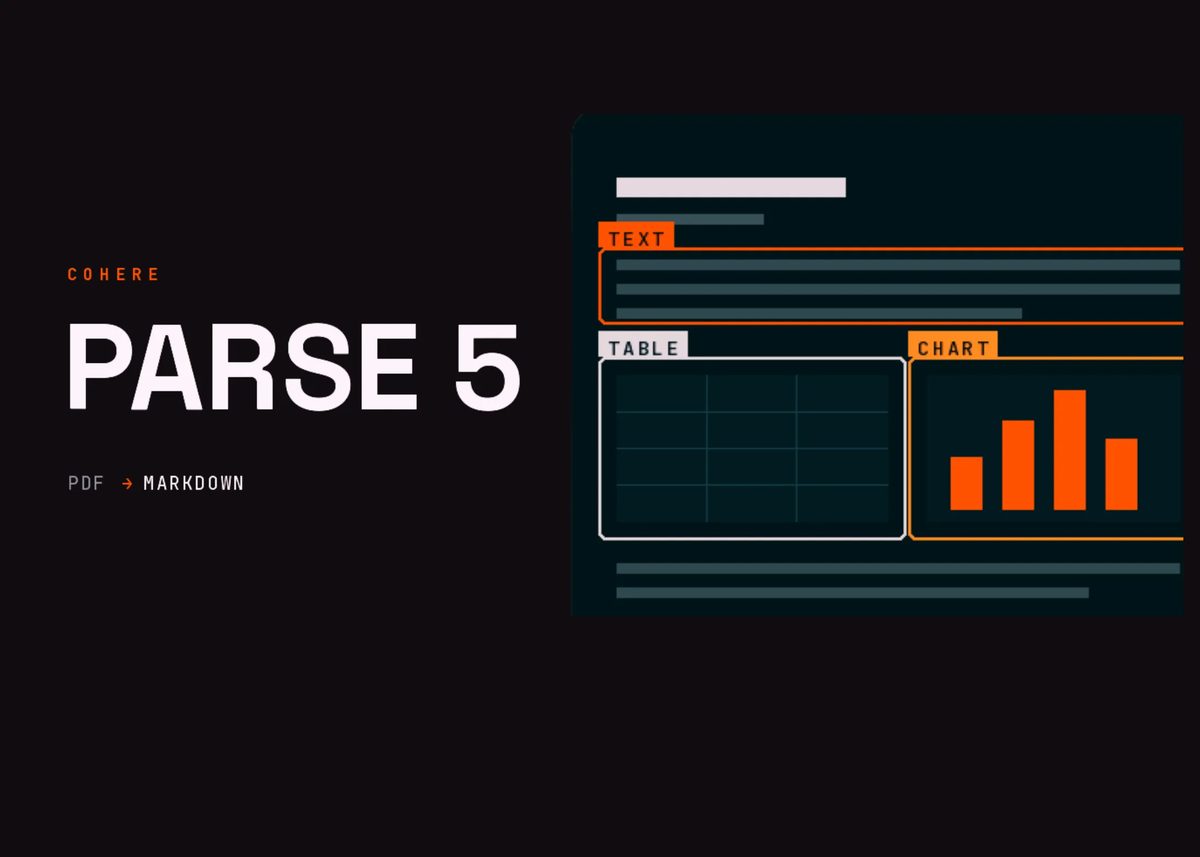
Cohere has released Parse 5 (parse-v5.0), a 2.3-billion parameter vision language model designed to convert unstructured enterprise documents directly into structured Markdown without an explicit OCR pipeline. Built on the North-Micro-Vision-Instruct architecture, the model features an 8,192-token context window and a 4.6GB footprint. It accepts PDFs, presentations, and images, extracting text, reading order, HTML tables, forms, and bounding boxes in a single inference pass.
The model is generally available via the Cohere Parse API at $1.50 per 1,000 pages, as well as on Microsoft Foundry, AWS SageMaker, and dedicated Model Vault deployments costing between $2,500 and $4,300 monthly. Cohere claims a self-reported 79.2 score on three dimensions of the LlamaIndex ParseBench evaluation, positioning the offering around cost efficiency and deployment flexibility for large-scale document ingestion.
For enterprise architectures, the release provides an alternative to traditional multi-stage OCR pipelines. By offering typed output blocks with visual coordinates, Parse 5 supports citation-level traceability for Retrieval-Augmented Generation (RAG) pipelines across nine natively supported languages.
Why it matters
Vision language models are replacing multi-stage OCR pipelines, simplifying data ingestion pipelines for enterprise RAG applications.
Clear unit economics ($1.50 per 1k pages) let operators evaluate API vs dedicated host costs for document extraction.
Structured block outputs with visual bounding boxes improve document chunk attribution and traceability for LLM applications.
Source: marktechpost.com