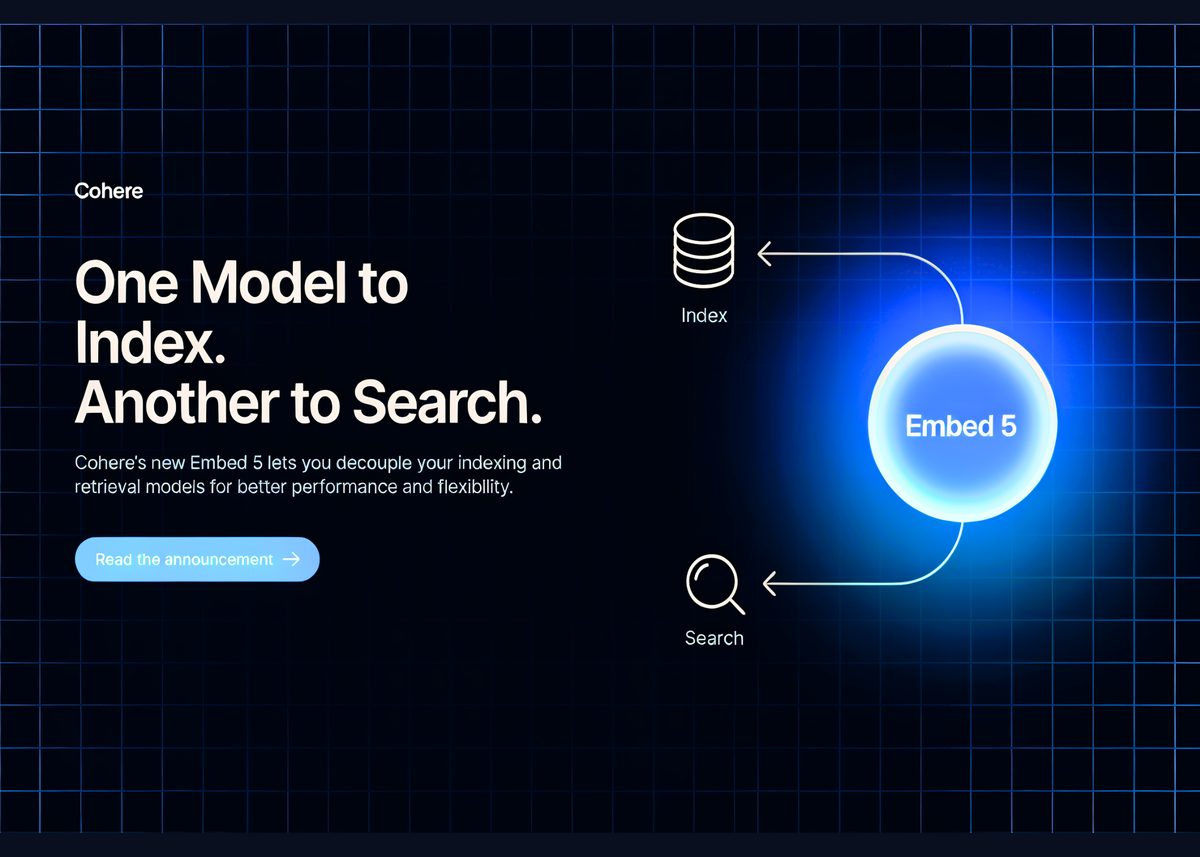
Cohere has released Embed 5, a new family of embedding models built for enterprise search, retrieval-augmented generation (RAG), and agentic workflows. The models are available in two tiers—Pro for maximum retrieval quality and Fast for low latency—that share a single embedding space, allowing systems to index documents with Pro and execute live queries with Fast.
Both tiers support text, images, and multimodal inputs up to 128K tokens across 100+ languages. Available via Cohere’s API, Microsoft Foundry, and Amazon SageMaker, the models support flexible output dimensions and precision levels. Using 1024-dimension int8 quantization reduces raw vector storage requirements from 819 GB to 3.2 GB per 100M document chunks while preserving near-full-precision performance.
According to Cohere, Embed 5 Pro achieved top scores on benchmark evaluation suites, outperforming Voyage 4 Large, Gemini Embedding 2, and OpenAI’s text-embedding-3-large on financial tasks and parsed-PDF retrieval. The asymmetric architecture is explicitly designed to reduce compound latency in multi-query agentic pipelines.
Why it matters
Asymmetric indexing/querying allows operators to cut query costs and latency without rebuilding vector databases.
Multimodal and high-context (128K) embeddings significantly improve RAG accuracy on complex enterprise assets like PDFs.
Advanced quantization techniques dramatically reduce vector storage footprints, lowering infrastructure overhead for enterprise search.
Source: marktechpost.com