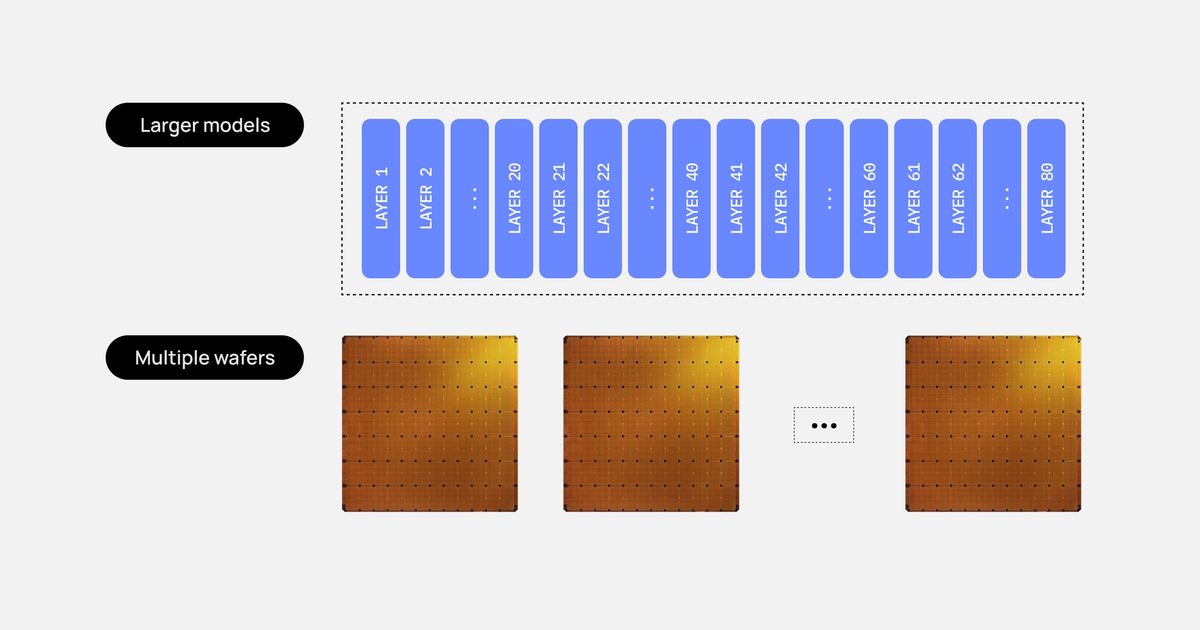
Cerebras Systems has outlined a deployment strategy using 59 WSE-3T wafer-scale chips to run multi-trillion parameter AI models, such as the open-source Kimi K3, at speeds of 1,000 to 2,000+ tokens per second. Because a single 44 GB on-chip memory wafer cannot hold multi-terabyte models, Cerebras uses a pipeline execution model mapped across multiple chips connected via low-latency RDMA over Ethernet.
Under this layout, individual layer weights remain statically stored in on-chip SRAM, while sequence activations move sequentially between wafers with approximately 2 microseconds of latency per hop. Cerebras maintains high hardware utilization across the pipeline stages by processing requests in micro-batches, preventing single-token bottleneck delays.
Why it matters
Enables real-time inference for multi-trillion parameter models previously restricted by memory bandwidth.
Demonstrates wafer-scale architecture viability against conventional GPU cluster topologies.
Provides alternative hardware strategies for scaling frontier coding and agentic models.
Source: cerebras.ai