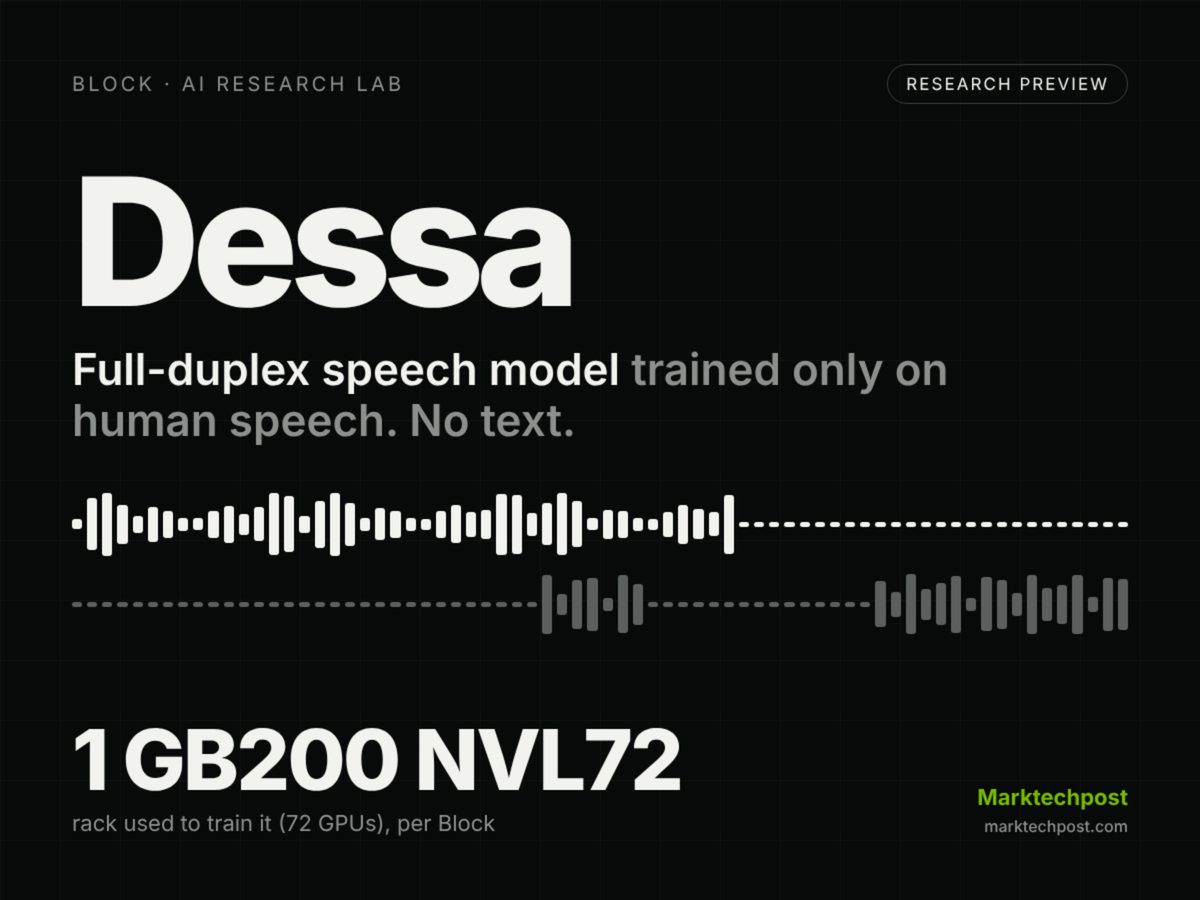
Block’s AI research lab released a research preview of Dessa, a full-duplex speech-to-speech model trained exclusively on human conversation. Unlike traditional speech systems that chain separate speech recognition, text language models, and text-to-speech synthesis components, Dessa operates entirely audio-in, audio-out without relying on text tokens or pretrained LLMs.
Because it processes and generates continuous speech natively, Dessa can listen and speak simultaneously, enabling real-time backchanneling cues such as “yeah” or “got it” and capturing conversational nuances like laughter, volume adjustments, and mid-sentence interruptions. Demo videos showed the model interacting dynamically with users and competing models like OpenAI’s GPT-Live-1 without human steering.
While Block has not disclosed the underlying model architecture, the project provides an alternative approach to full-duplex architectures like Kyutai’s Moshi, which uses time-aligned text tokens over a language model backbone.
Why it matters
Demonstrates native speech-to-speech modeling without text token reliance, enabling lower latency and dynamic conversational cues.
Offers a direct architecture alternative to pipeline-based voice agents and text-backed full-duplex systems.
Source: marktechpost.com