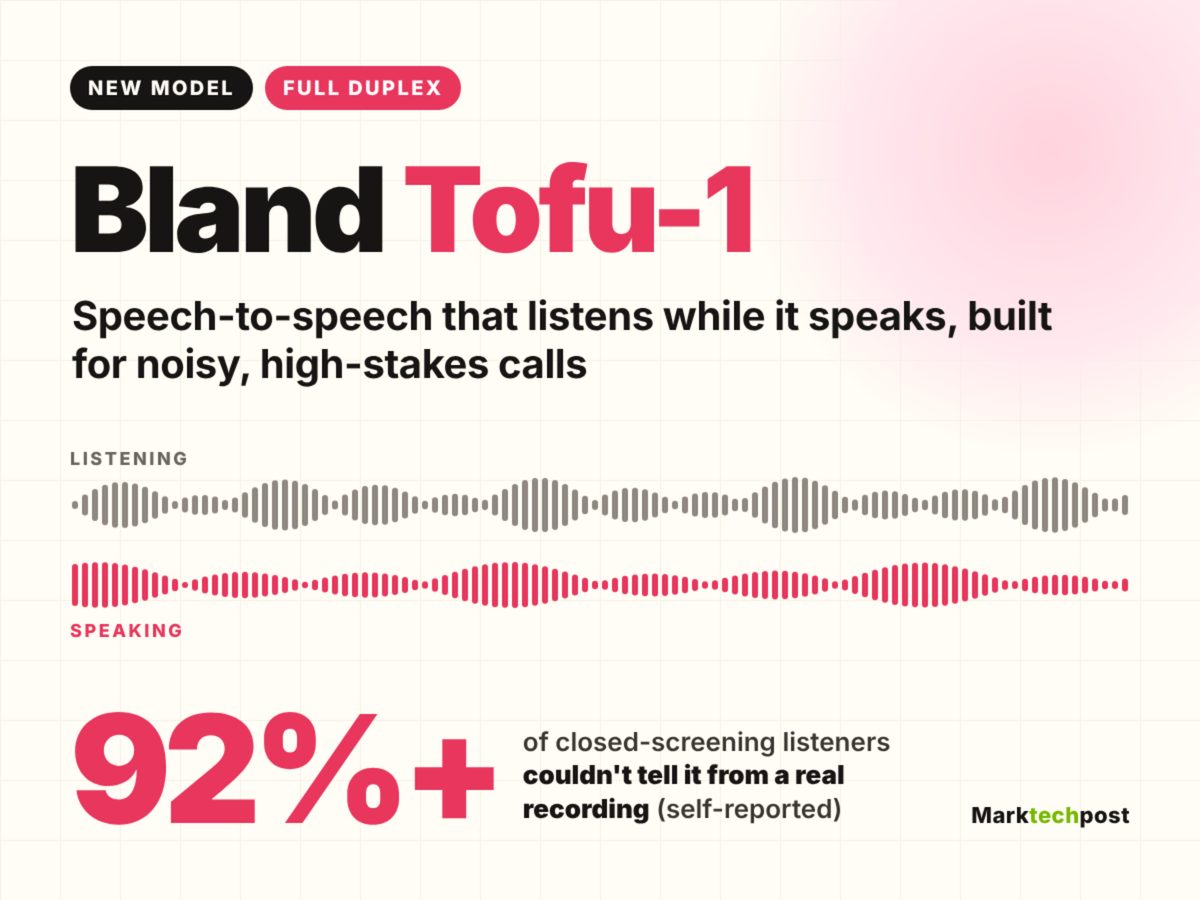
Voice AI startup Bland has launched Tofu-1 into research preview, presenting a full-duplex speech-to-speech model engineered for real-time phone calls. Unlike traditional voice agent cascades that convert audio to text, process it via an LLM, and synthesize speech, Tofu-1 processes incoming audio natively to capture emotional tone, pauses, and ambient background noise.
The model features full-duplex capabilities that allow callers to interrupt or correct the agent mid-sentence without breaking context. Bland claims Tofu-1 can maintain active conversations while processing background tasks, only confirming completion when work is fully executed. The company is initially pitching the model to enterprise clients in banking, healthcare, insurance, and government.
Bland has not disclosed the underlying architecture of Tofu-1. Access to the research preview is currently restricted to selected enterprise partners based on call volume, with deployment details made available via external tools.
Why it matters
Full-duplex native speech-to-speech architectures reduce latency and preserve contextual audio cues lost in traditional STT-LLM-TTS cascades.
Enables voice agents to handle real-time interruptions and complex phone environments like noisy vehicles or hospital rooms.
Signals growing enterprise demand for highly realistic automated voice agents in regulated industries like banking and healthcare.
Source: marktechpost.com