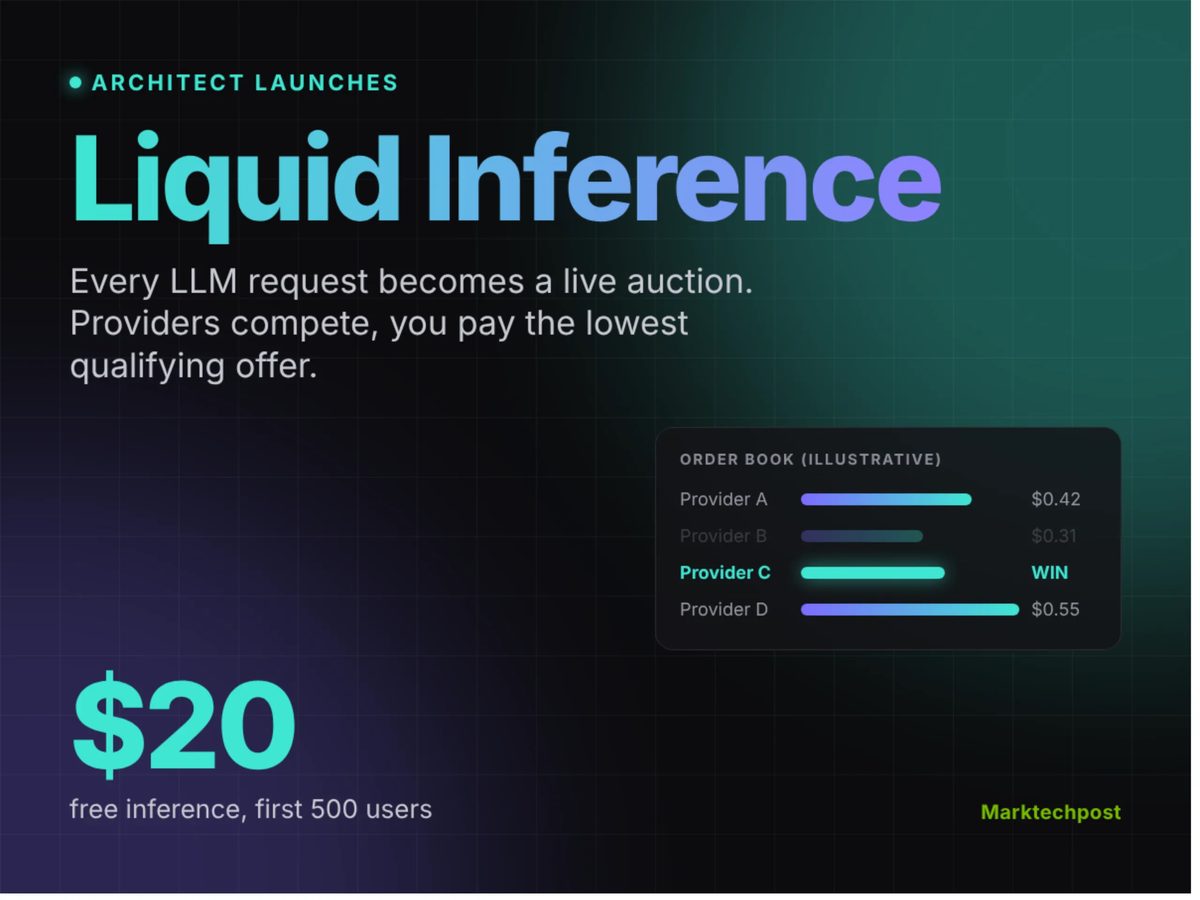
Architect Financial Technologies has released Liquid Inference, an exchange-style LLM router that runs a real-time reverse auction for every API call, according to MarkTechPost. Developed by a team with background in financial markets and perpetual futures exchanges, the marketplace allows inference providers to bid continuously on prompt execution, with the buyer automatically paying the lowest price that satisfies its custom operational constraints.
Developers can integrate the router by swapping their base URL while maintaining OpenAI API compatibility. Buyers can define custom routing rules including price caps, latency limits (time to first token), minimum throughput, zero data retention policies, and regional compliance requirements. The platform also offers an Auto mode for automated model selection alongside live order book visibility and transparent cleared transaction logs.
For compute providers, the platform offers rapid onboarding and REST or WebSocket APIs to dynamically adjust pricing and sell off excess GPU capacity on demand. Monetization and payouts are integrated directly through Stripe, providing itemized records for every completed job.
Why it matters
Developers can lower inference costs via live provider price competition without modifying existing OpenAI-compatible code bases.
GPU providers gain a dynamic liquid market to monetize spare compute capacity on a per-request basis with instant rate updates.
Real-time bidding tools enable granular enterprise controls over latency caps, geographic region routing, and zero-data-retention compliance.
Source: marktechpost.com