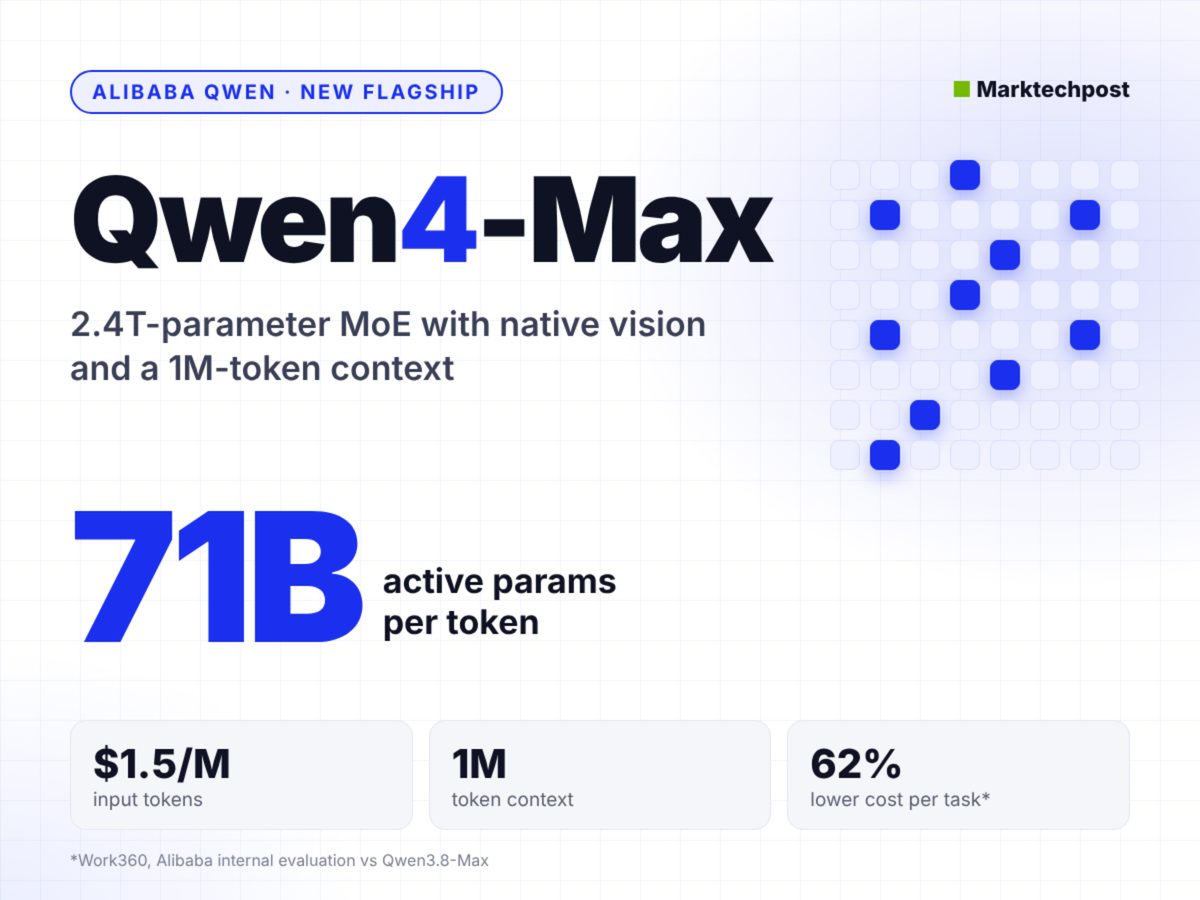
Alibaba’s Qwen team has launched Qwen4-Max, the first flagship model of its Qwen4 generation. The proprietary sparse Mixture-of-Experts (MoE) architecture features a 2.4-trillion-parameter backbone with 71 billion active parameters per token, supporting text, image, and video inputs alongside a 1-million-token context window.
To drive developer adoption, Alibaba lowered API pricing to $1.50 per million input tokens and $4.50 per million output tokens, alongside a 70% cut in context caching costs. Across its internal benchmark suite, Alibaba claims a 62% drop in average cost per complex task due to reduced token usage and lower baseline pricing, while Base model loss tests showed 5% to 13% improvements in compression efficiency over Qwen3.8-Max.
Available via QwenCloud with OpenAI and Anthropic API compatibility, the model includes features like structured output, batch processing, and function calling. However, Alibaba noted that top rival models such as Claude Opus 5.5 still hold leads in specialized benchmark categories like coding and advanced vision tasks.
Why it matters
Enterprise developers get access to frontier-class long-context MoE inference at significantly lower API token and context caching prices.
Drop-in Anthropic and OpenAI API compatibility reduces switching costs for organizations managing multi-model orchestration platforms.
Source: marktechpost.com