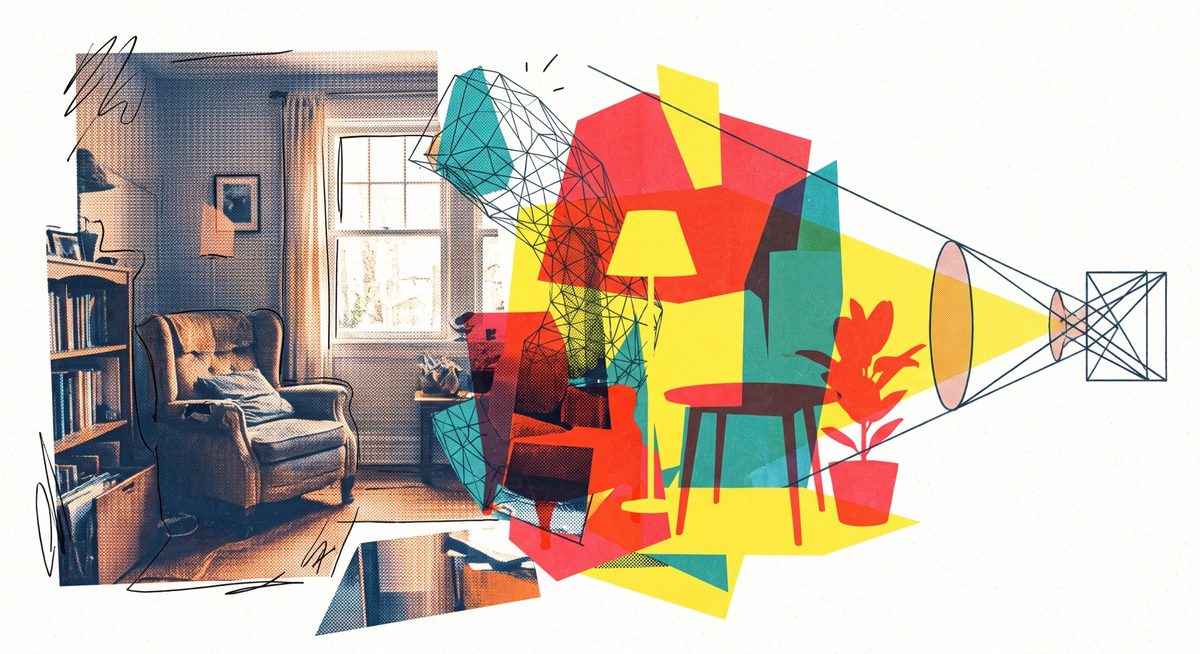
Researchers from the University of Maryland and AWS have introduced LEGO-Anything, an ‘Image-to-Code’ approach where AI coding agents iteratively generate Blender code to build editable 3D scenes from single photos. To evaluate performance, the team created LEGO-Bench, an automated benchmark featuring 208 images across 104 indoor and outdoor scenes using simulator-rendered ground truth.
While tested GPT configurations reliably generated executable scenes, geometric accuracy varied significantly. The top-performing model, GPT-6 Astra, achieved 53.4% accuracy on indoor scenes but only 39.6% on outdoor scenes. Analysis revealed that models struggle with self-assessment, frequently failing to identify whether code revisions improved spatial geometry. To fix this, researchers built LEGO-Plugin, an extension using concrete measurements instead of model self-judgment, yielding performance improvements across all tested models.
Why it matters
Demonstrates that current frontier LLMs cannot reliably judge 3D spatial accuracy without external measurement mechanisms.
Provides a deterministic benchmark (LEGO-Bench) for evaluating how accurately AI coding agents turn visual inputs into functional code.
Shows that anchoring iterative refinement in explicit algorithmic feedback yields dramatic performance gains over standard model self-critique.
Source: the-decoder.com