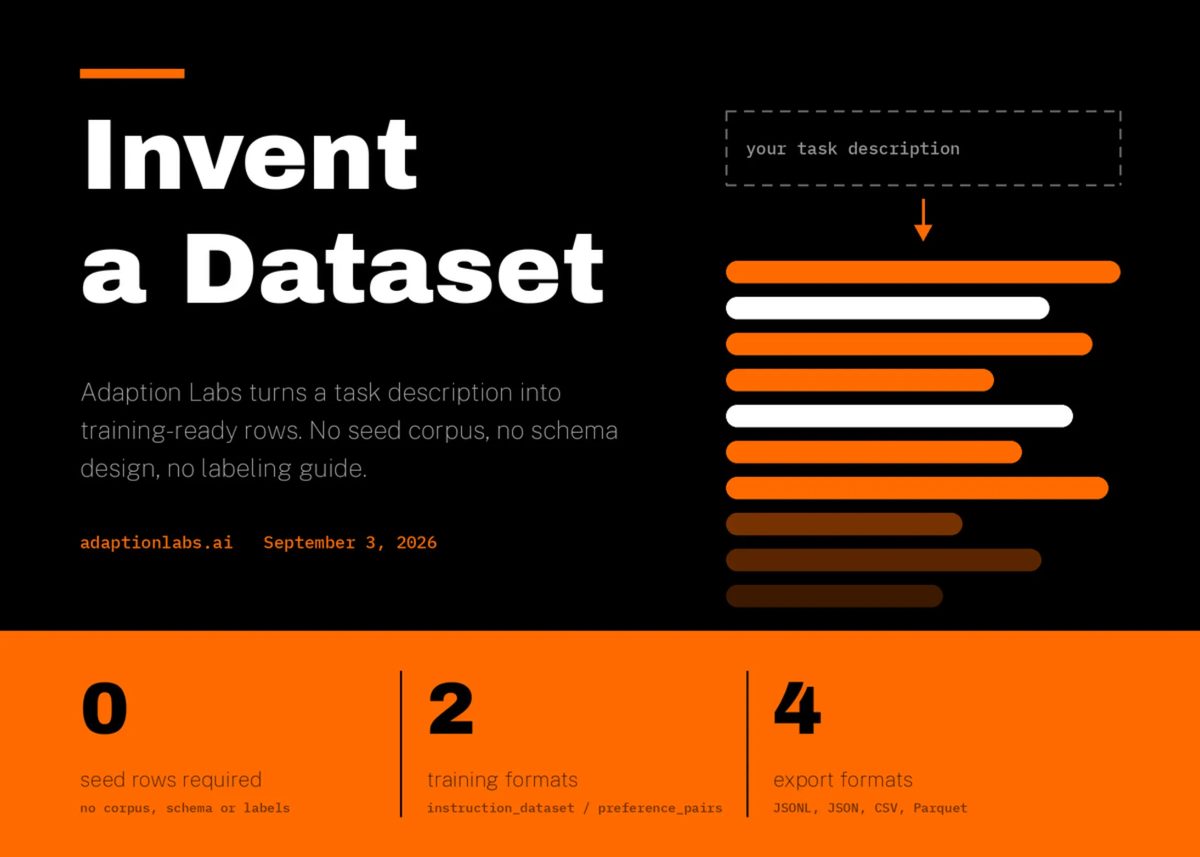
Adaption Labs has released ‘Invent a Dataset’, a new platform feature that generates structured, domain-specific training data directly from natural language task descriptions without requiring a seed dataset or human-curated schema. The tool is accessible via the Adaption web application, Python SDK, and REST API.
The service allows teams to request structured output formats—including instruction pairs for fine-tuning or preference pairs for Direct Preference Optimization (DPO)—governed by domain codes such as healthcare or finance. It also supports localization and translation features to expand generated data samples across multiple target languages and regions.
Generated datasets are exported in standard formats like JSONL, CSV, and Parquet for independent local or cloud training. The feature directly integrates into Adaption’s AutoScientist engine to automatically optimize data structures alongside model training recipes.
Why it matters
Accelerates model fine-tuning workflows by removing the requirement for pre-existing seed datasets.
Reduces reliance on expensive manual data labeling and schema design for specialized enterprise tasks.
Provides portable, standard-format synthetic datasets that can be trained across any infrastructure.
Source: marktechpost.com